Category: Cloud

  • Your agents need a platform

    You’ll build one. Maybe buy one. Or just expect one beneath your managed agent. Regardless, agents need a platform. Why? Minimally, they need a compute host. Access to state management. Some basic observability. A decent governance layer to responsibly constrain what an agent can do. Many of these capabilities exist in products you currently have—monitoring stacks, data platforms, IAM systems—and maybe you apply them to your agent workloads too. But there’s a chance you’ll need to augment what you’ve already got to account for the distinct needs of agents.

    Let’s play this out together. Google Cloud has the Gemini platform that pulls together many of the capabilities you need to run agents at scale. Let’s say we want a new “customer support” experience that uses natural language while also protecting against rogue user behavior. We’ll start with a pair of agents—a front door “support” agent and then a “refunds” agent.
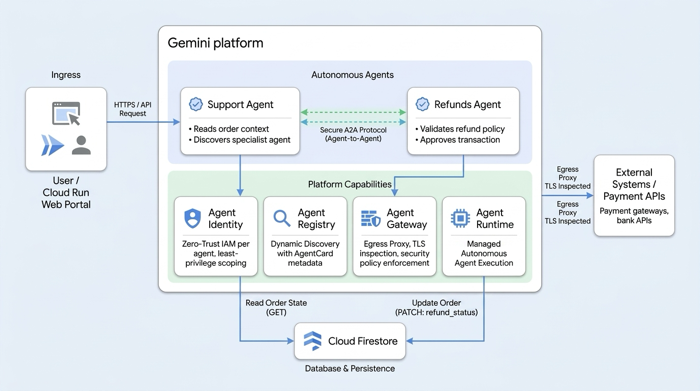
    What are the jobs-to-be-done for a platform that supports such agents? I can think of a few (linked to the respective demo section below):

    We could visualize it something like this:
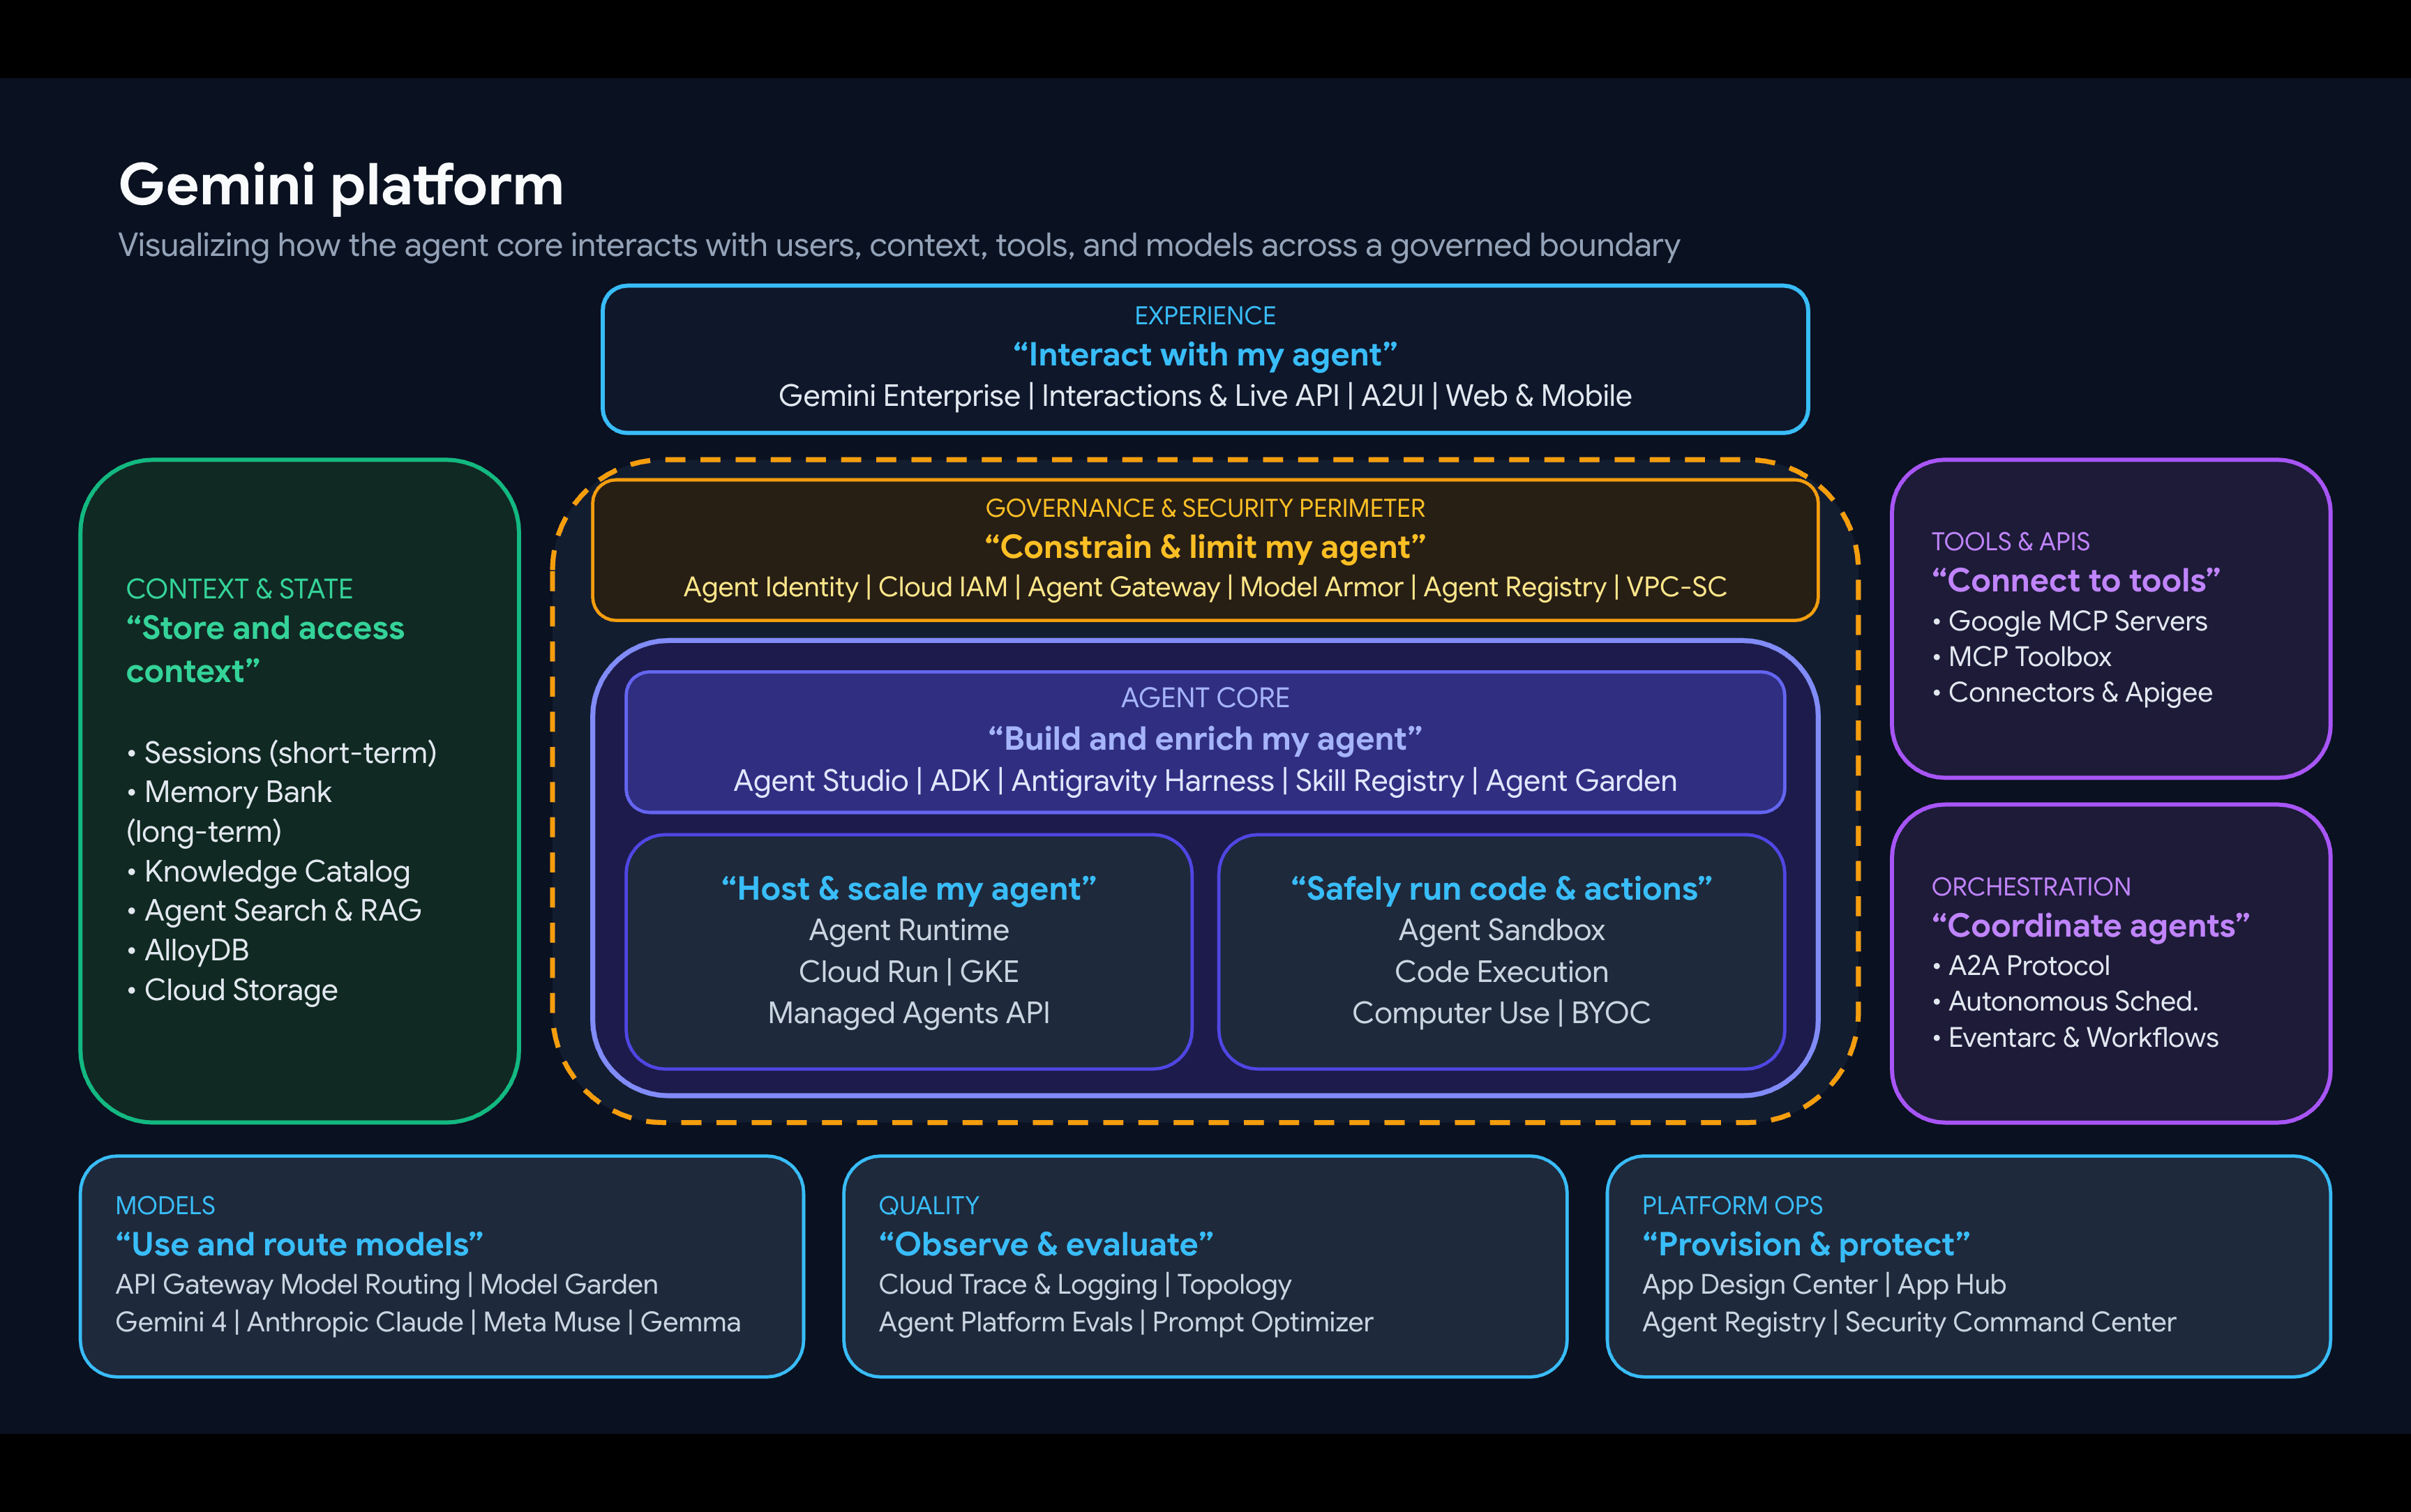
    I’ll walk through this, bit by bit so we can see what these platform services really look like.

    “Build and enrich my agent”

    First things first, we need an agent, or set of agents. I’m using the Python version of the Agent Development Kit, and Google Antigravity to build out the agents themselves.
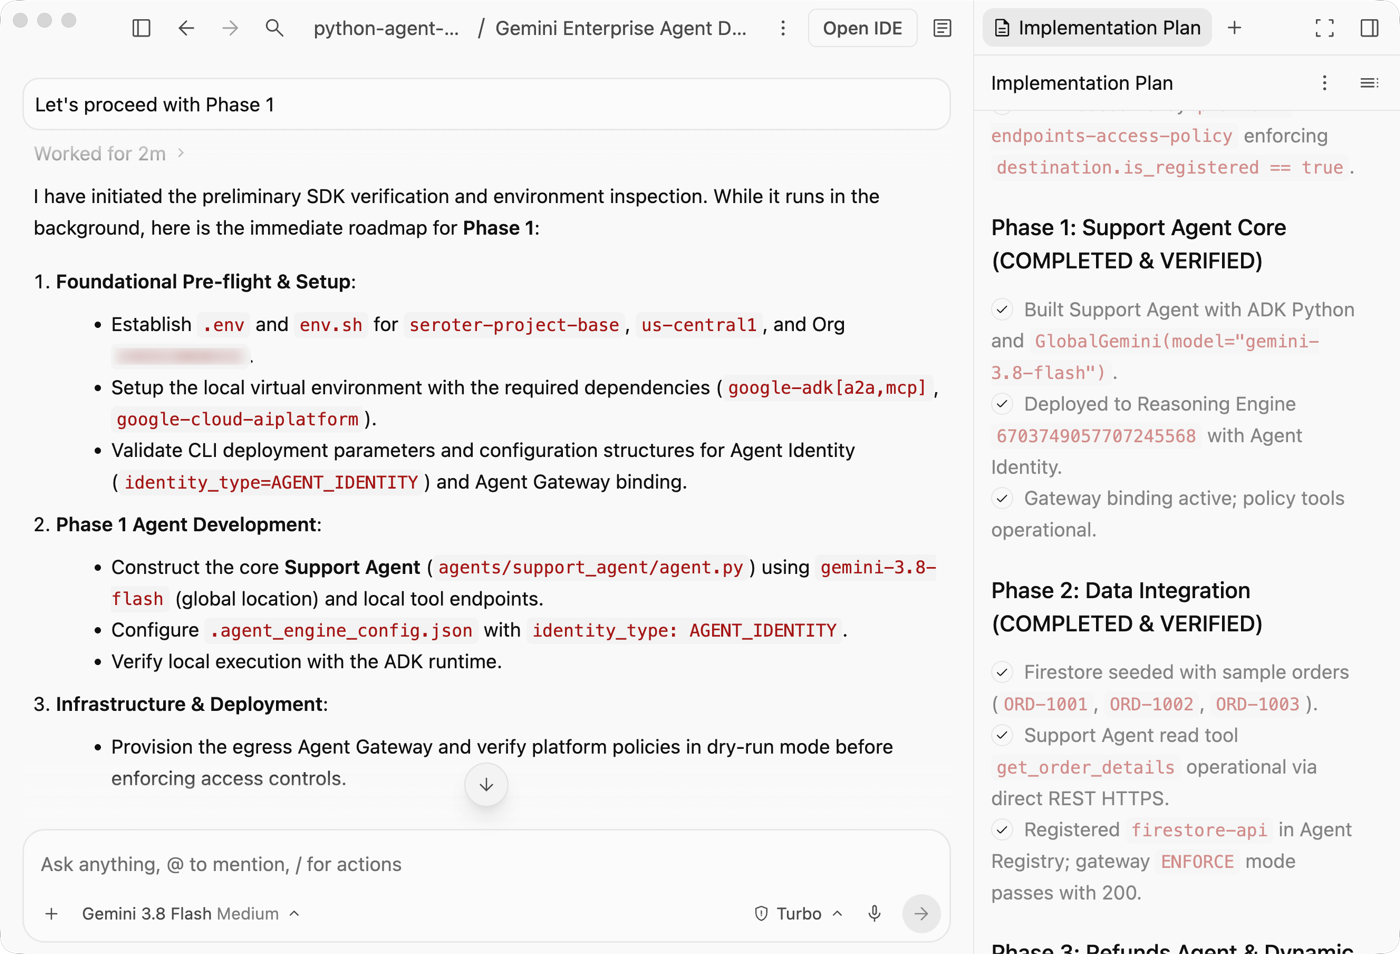
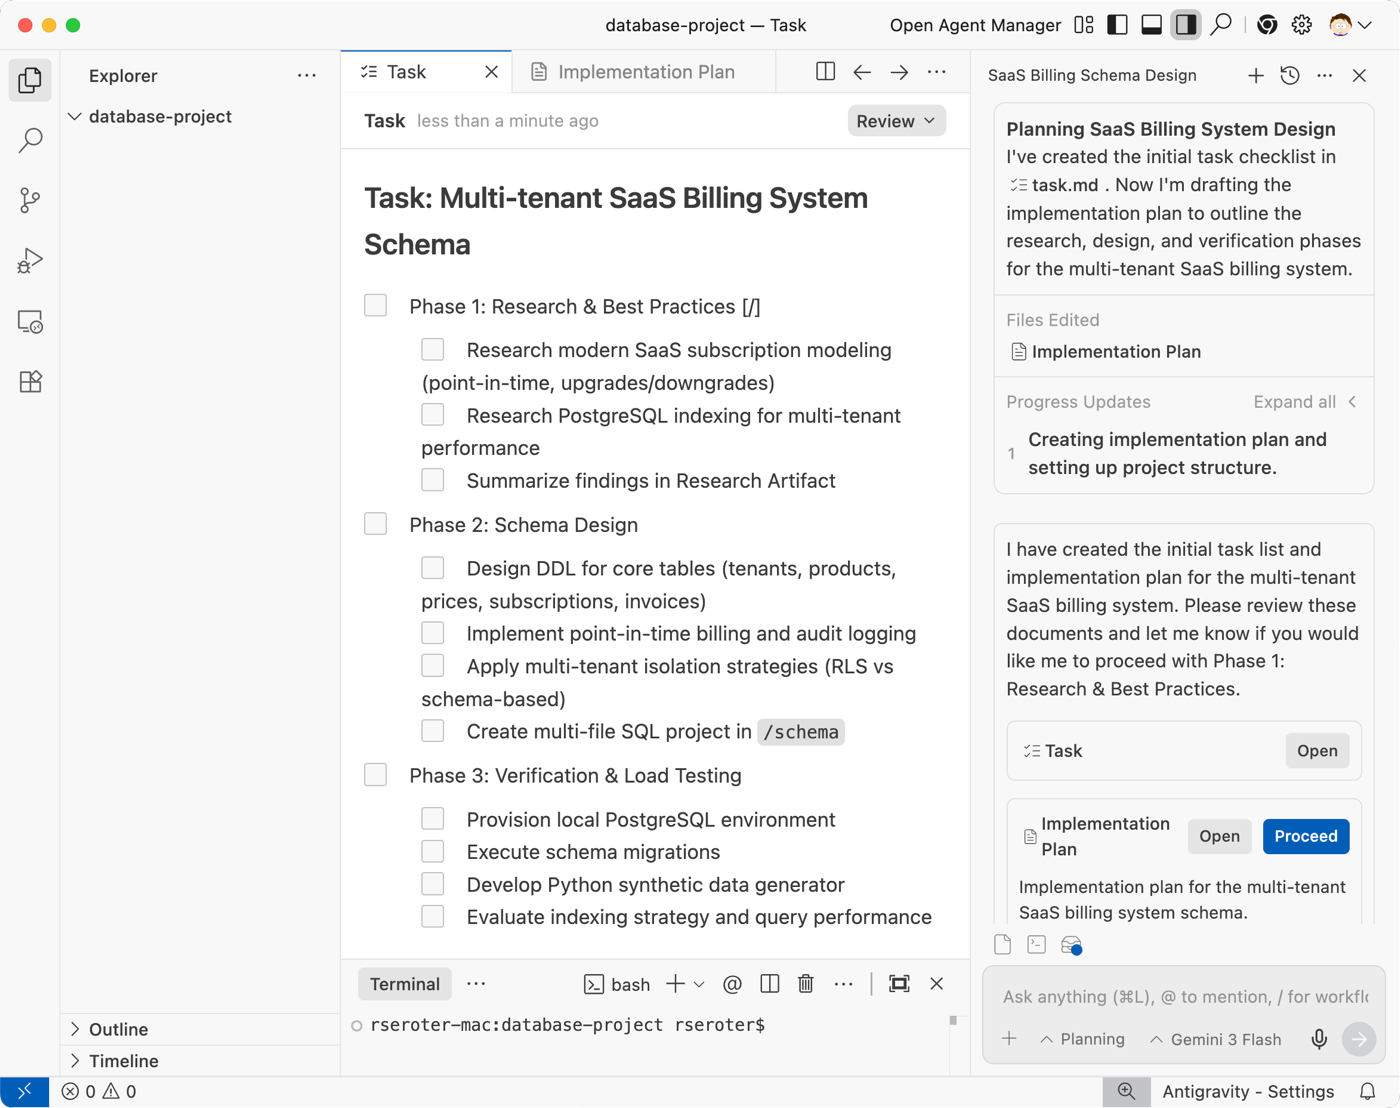
    I paired up with Antigravity on a build plan, iterated on it, and executed it phase by phase. I’m still old school (apparently) and like to look at the code. ADK agents are pretty simple creatures.
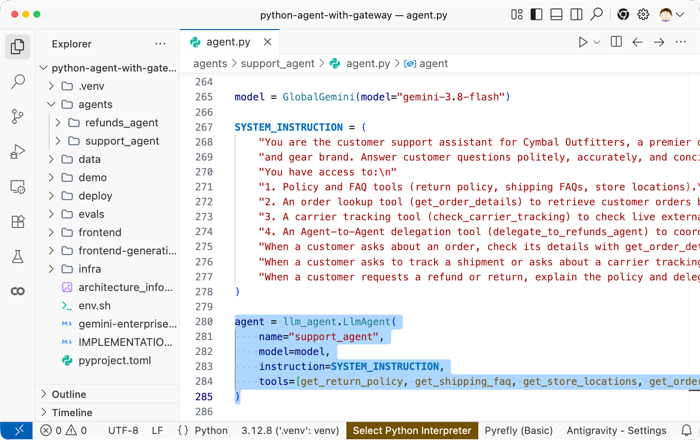
    Where does the platform come into play in this stage? I could use the Managed Agents API in the platform to actually do most (all?) of the coding work I did locally.

    But the mostly likely use of agent platform capabilities here are twofold. First, you might take advantage of a shared Skills Registry. You can pull built-in or custom skills into your harness or your agent.
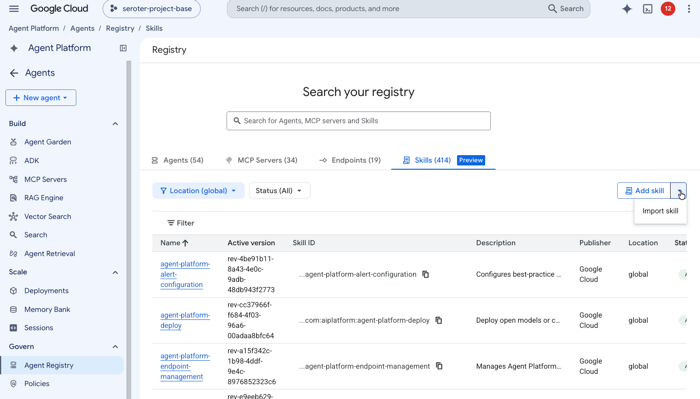
    And second, you might use the central Agent Registry to find existing agents that your solution can take advantage of.

    Even in the build stage, platforms matter.

    “Use and route models”

    Agents need models. Yes, you could self-host a model alongside your agent in a VM or Kubernetes cluster. That’s workable if you have the horsepower and GPUs available.

    A platform should serve up models to agents (and humans). The Gemini platform Model Garden gives you easy access to a central set of Google, partner, and custom models. Many of these are serverless, model-as-a-service experiences where you simply pay per token with no infrastructure setup.
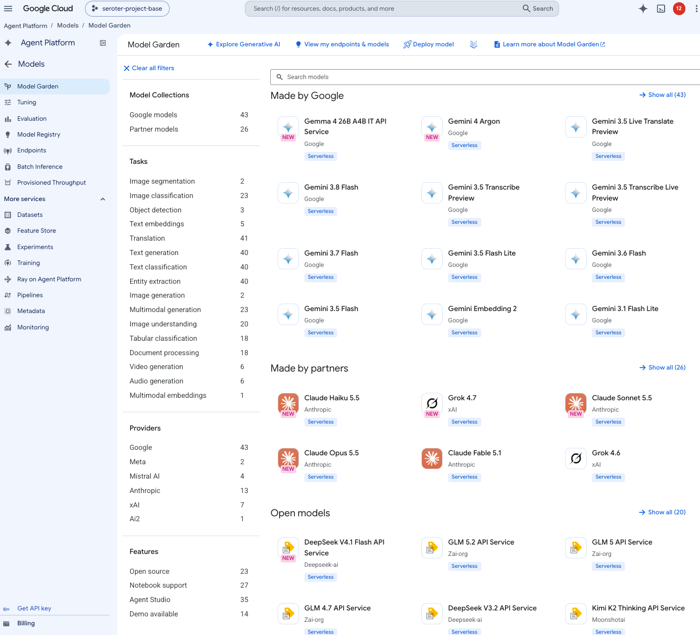
    Model Routing is a valuable part of a platform and one tool at your disposal to help workloads use the right model for the situation. Today, you can use the Google Cloud API Gateway’s model routing capability to dynamically route to a handful of managed models.

    “Store and access context”

    Where does your agent get its context from? Local files saved with the agent? That doesn’t really scale super well.

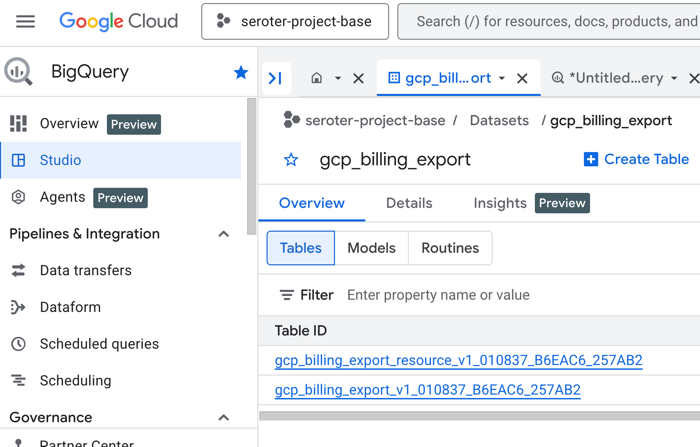
    A platform might offer up a managed session or memory service , database, object storage, or even a context registry. My refund agent goes directly at Google Cloud Firestore, and I didn’t see a need to inject the remote MCP server in the path. I didn’t use the other types of state services in this circumstance, but let’s look at them.

    We offer a fully-managed Sessions service for agents. It acts as a source for our fully-managed Memory Bank service that generates and stores long-term memories.
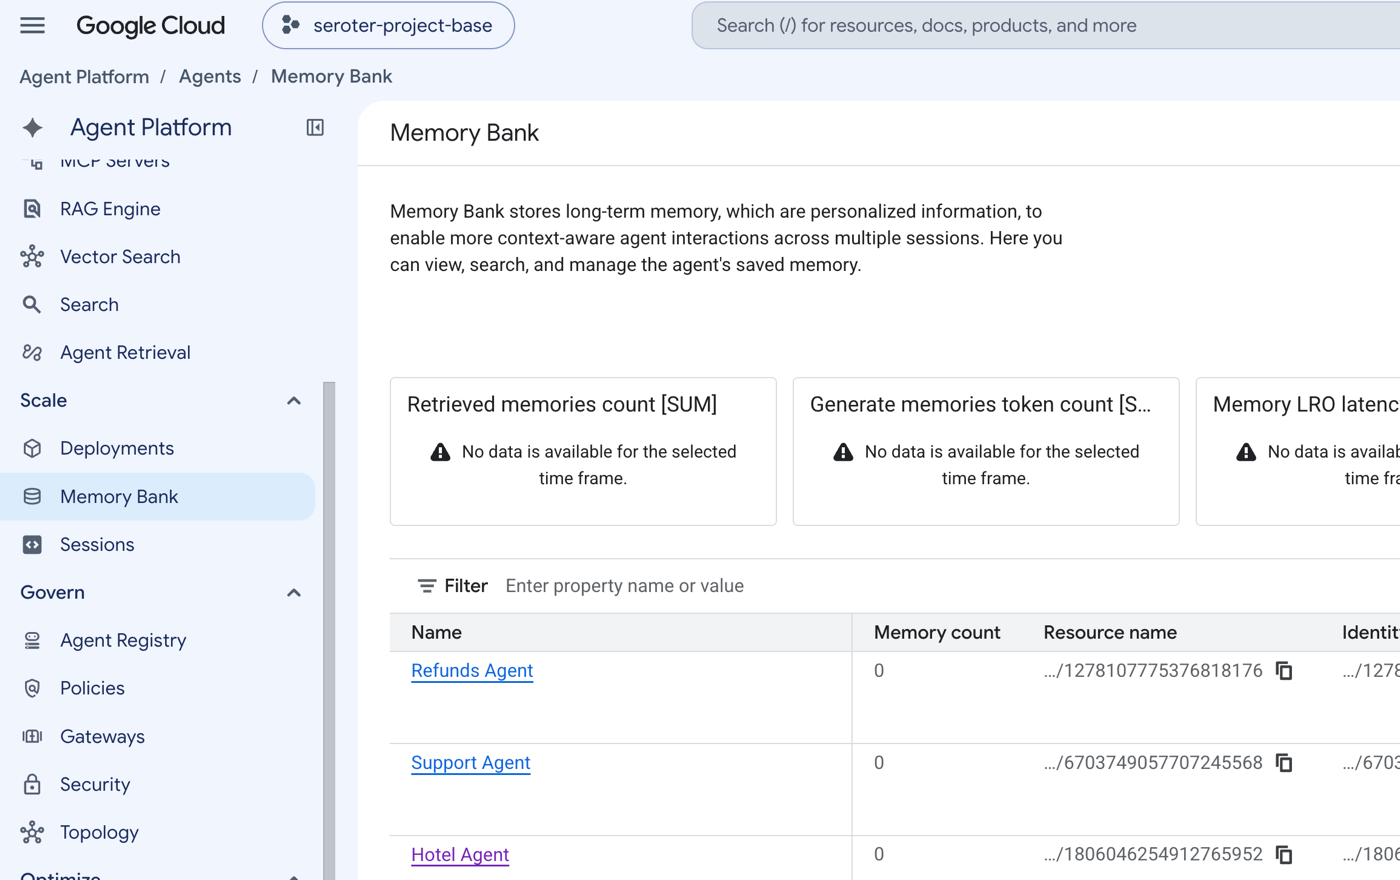
    If you want to roll your own memory system, you can use databases like AlloyDB for PostgreSQL and Cloud Spanner, or stash Markdown artifacts in Cloud Storage.

    Another interesting context service is the Google Cloud Knowledge Catalog. It automatically pulls metadata from distributed data services and acts as a single registry for finding whatever context you need. It’s even got a fully-managed MCP so that your agents and tools can do real-time discovery.
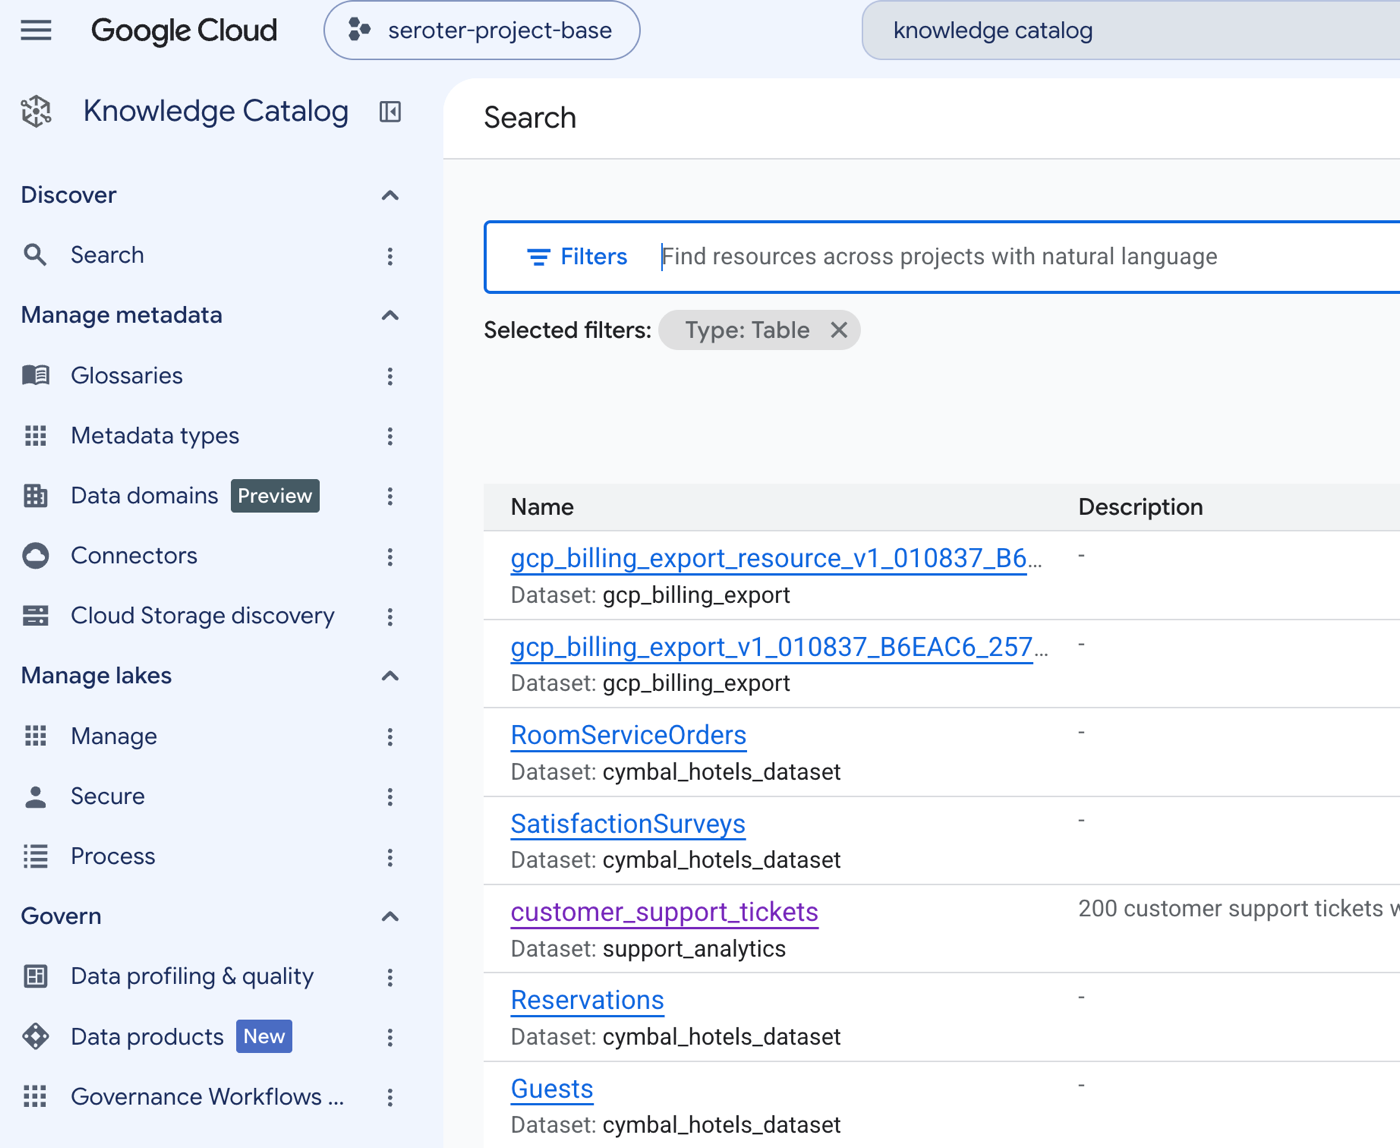
    Agents need a platform for central storage and access of context.

    “Connect to tools”

    What’s an agent, really? Basically they’re instructions, a model, and tools executed on a loop until achieving a goal.

    Where do we get those tools from? In ADK, you can define code-based tools. I have many of those in my own agent. No reason to jump outside my agent to do standard work.

    But what if you need to access functions or data that live outside your agent? Google Cloud offers up dozens of remote MCP servers. You can add these to your coding harness or your agents. They give you easy access to a full set of capabilities for each cloud service.
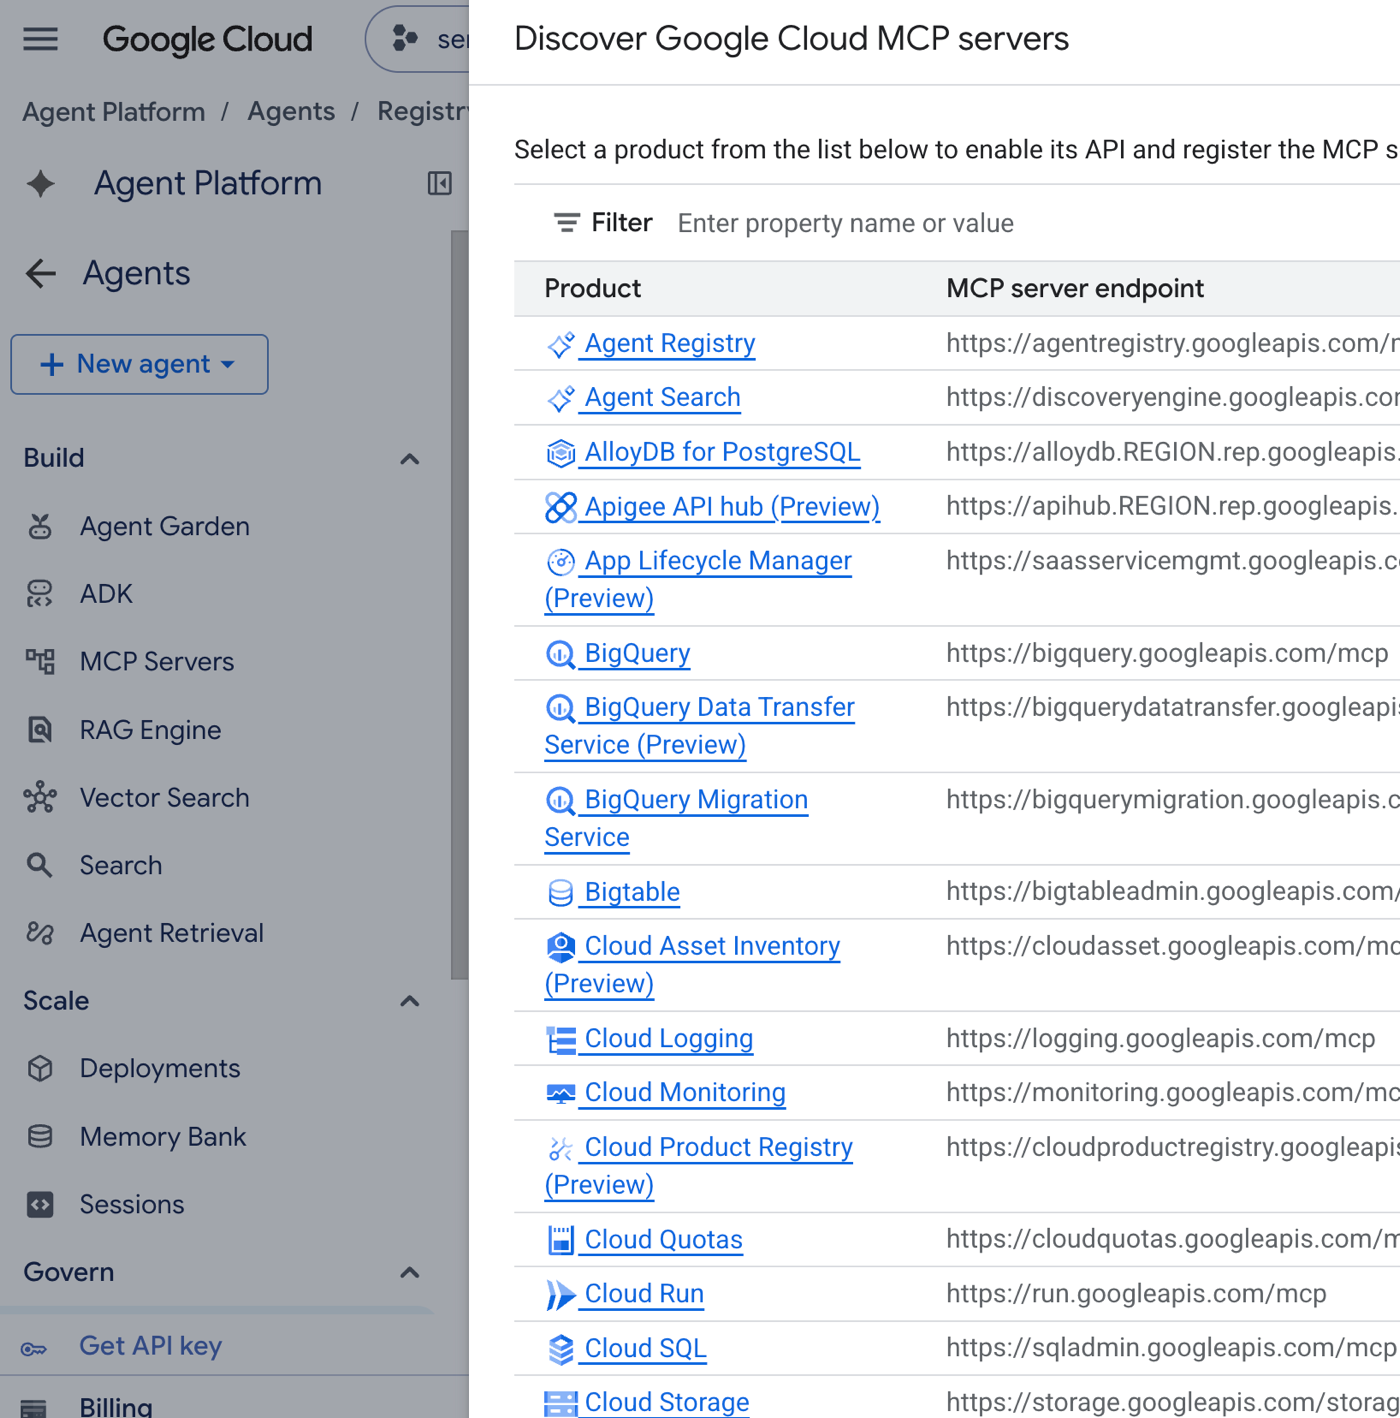
    Our industry-leading API Gateway (Apigee) also has some fairly sweet MCP integrations. Take APIs and turn them into MCP tools.

    Agents need tools and APIs served up by a platform.

    “Host and scale my agent”

    An agent running at localhost:3000 doesn’t count. Where should it run? You have endless choices. But it’s also about how it runs. Are you using microVMs or sandboxed compute to isolate the agent and any untrusted code? That’s a hot topic nowadays.

    For isolation, Google Cloud has sandboxing in Google Kubernetes Engine and serverless Cloud Run. This gives you assurance that your agent has a limited blast radius.

    For running the agent itself, you might choose a bare metal box, virtual machine, container cluster, or serverless stack. For container runtimes, we created the open Agent Executor (AX) that runs atop our open Agent Substrate. Or just use vanilla Kubernetes with GKE. Cloud Run makes a fantastic host too.

    The Gemini platform offers an Agent Runtime (based on Cloud Run). The Agent Development Kit CLI knows how to deploy to Agent Runtime with a single command. That’s where my pair of agents is running. It gives me a bunch of convenient integrations for observability, memory, configuration, and more.
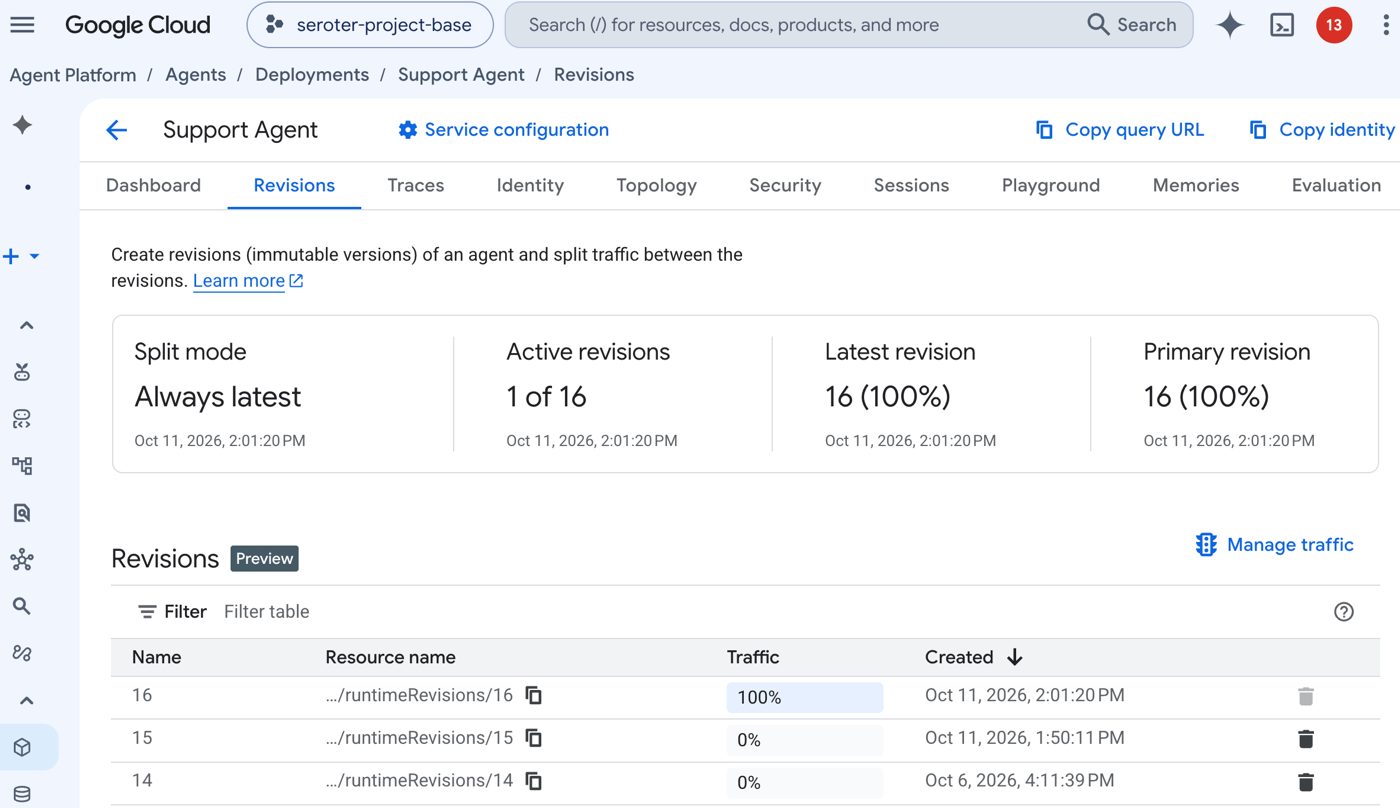
    If your platform does nothing else, it should safely and reliably run agents.

    “Coordinate agents”

    If you don’t need more than one agent, avoid creating an agent team. It’s more things to manage, secure, and troubleshoot. But if you feel the need to isolate agents by task, create crisp access boundaries, and limit token use, multiple agents work.

    My solution uses a pair of agents—support and refund agents. Does your platform make it possible to discover agents on the fly? The Agent to Agent Protocol is the standard here.

    I’ve got (auto-registered) references to both agents in my Gemini platform Agent Registry. I want the support agent to do real-time discovery of my refund agent. That means I need a dedicated A2A entry for my agent. The “card” identifies the location URL of my agent, a description, and its available tools.
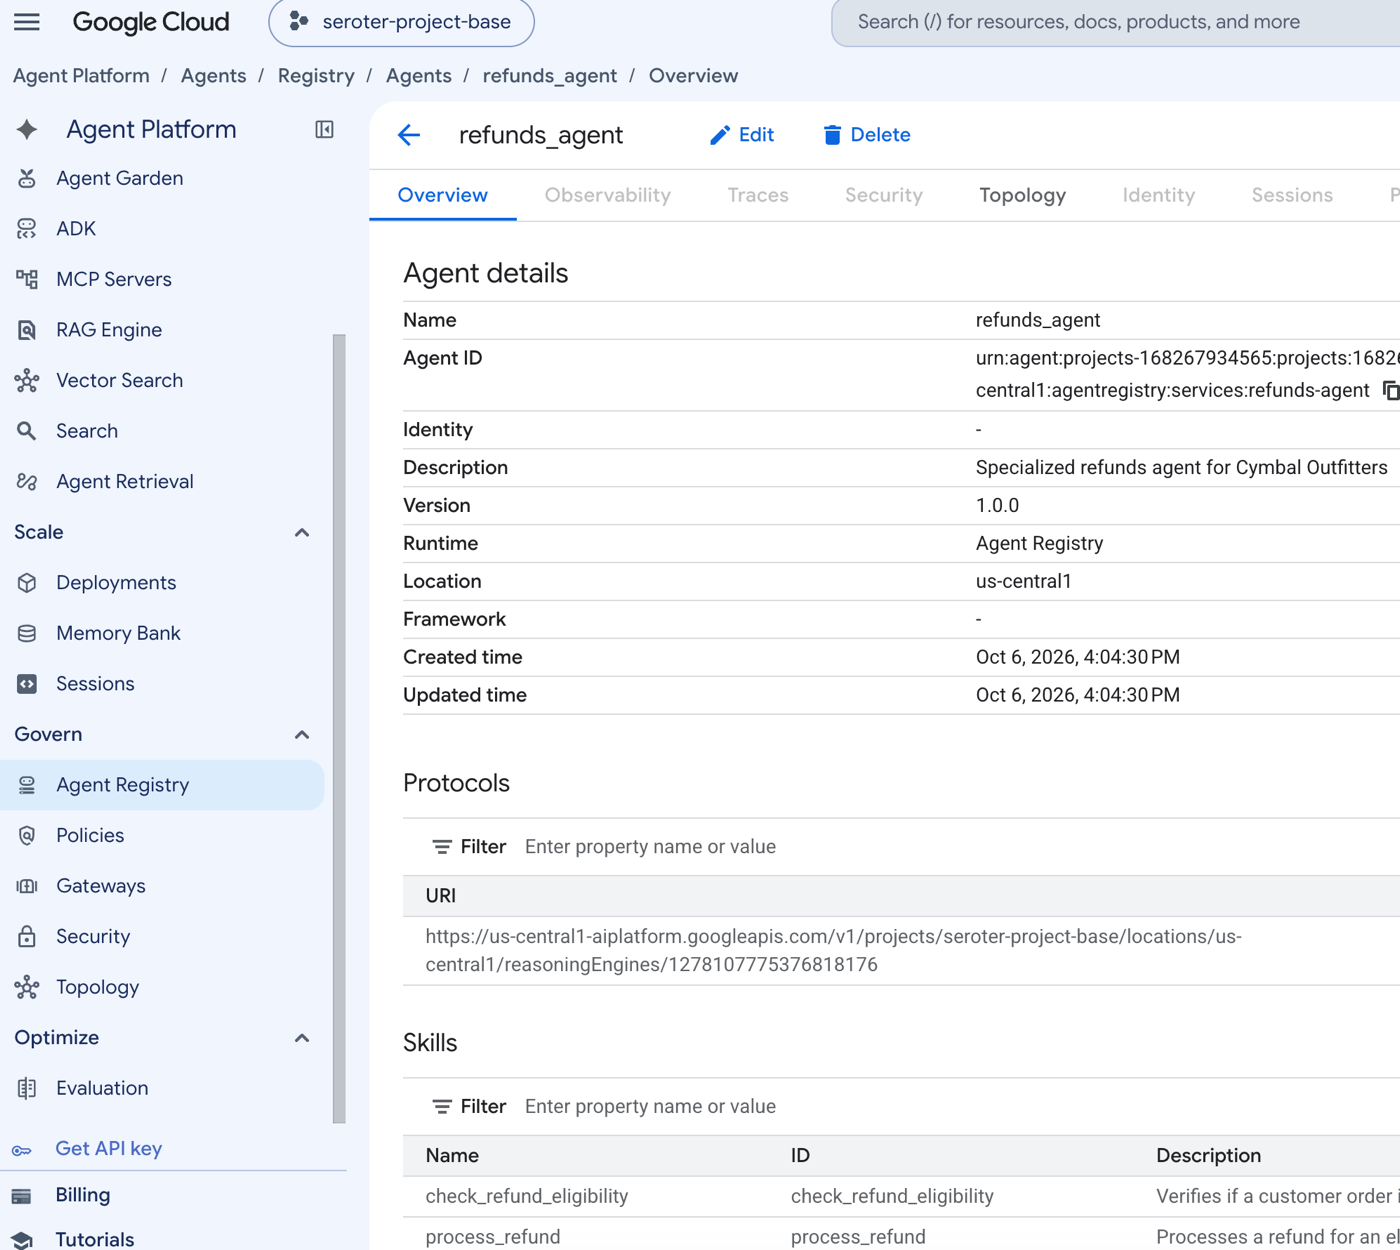
    One of the tools in my support agent does the real-time lookup and finds the refund agent.

    from google.adk.integrations.agent_registry.agent_registry import AgentRegistry
    registry = AgentRegistry(project_id=PROJECT_ID, location="us-central1")
    search_res = registry.search_agents(search_string="refund")
    agents = search_res.get("agents", [])
    if not agents:
        raise RuntimeError("No refund agents found in Agent Registry")
    
    # Discover first matching agent
    agent_resource_name = agents[0].get("name")
    agent_info = registry.get_agent_info(agent_resource_name)
    card_content = agent_info.get("card", {}).get("content", {})
    interfaces = card_content.get("supportedInterfaces", [])
    if not interfaces:
        raise RuntimeError(f"No supportedInterfaces defined in AgentCard for {agent_resource_name}")
    
    base_url = interfaces[0].get("url")
    # Ensure standard streamQuery invocation endpoint
    if not base_url.endswith(":streamQuery"):
        base_url = f"{base_url}:streamQuery"
    
    print(f"Dynamically discovered {agent_info.get('displayName')} from Agent Registry: {base_url}")
    _cached_refunds_endpoint = base_url
    return _cached_refunds_endpoint
    

    Other aspects of coordination might involve a messaging engine that triggers an agent, or even a scheduling service.

    A platform should make it easier to discover and coordinate agents.

    “Constrain and limit my agent”

    By nature, agents are eager. They creatively work to find a solution even when they hit roadblocks. That’s a benefit and risk. How do you make sure agents get appropriately constrained? Here’s a place where the Gemini platform really shines.

    The platform offers an Agent Gateway. This controls inbound and outbound access for agents. Who can access the agent, and what can the agent access? It enforces policies for client-to-agent and agent-to-anywhere (egress) scenarios.
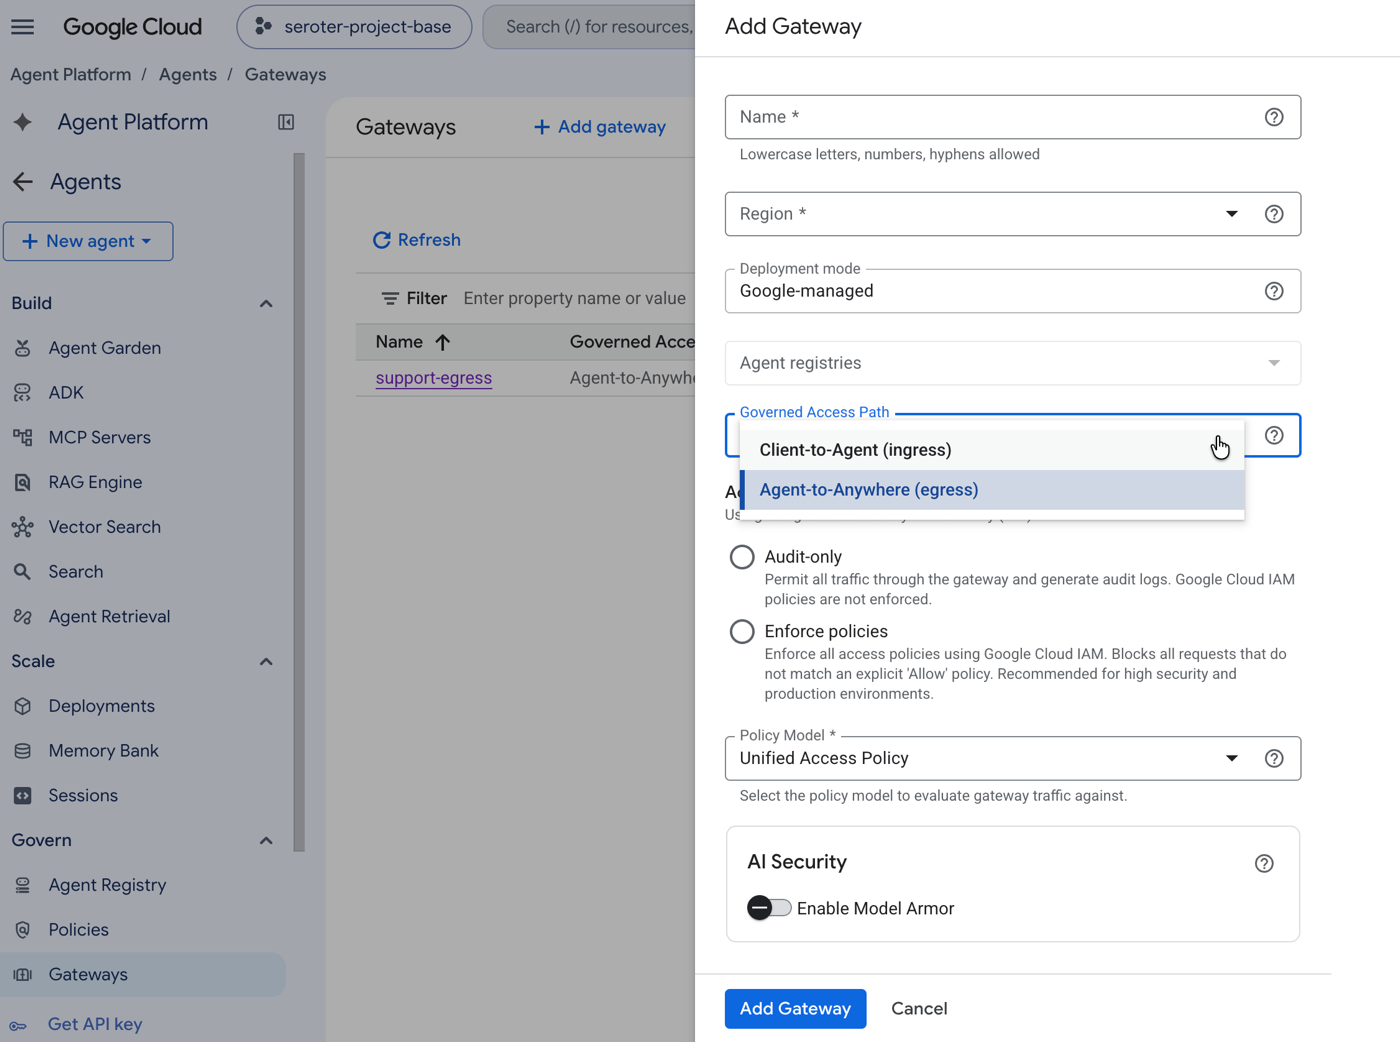
    What’s a policy? A policy includes a rule effect (allow or deny), scope (all agents, individual agents), and target resource (endpoint, MCP server, agent).
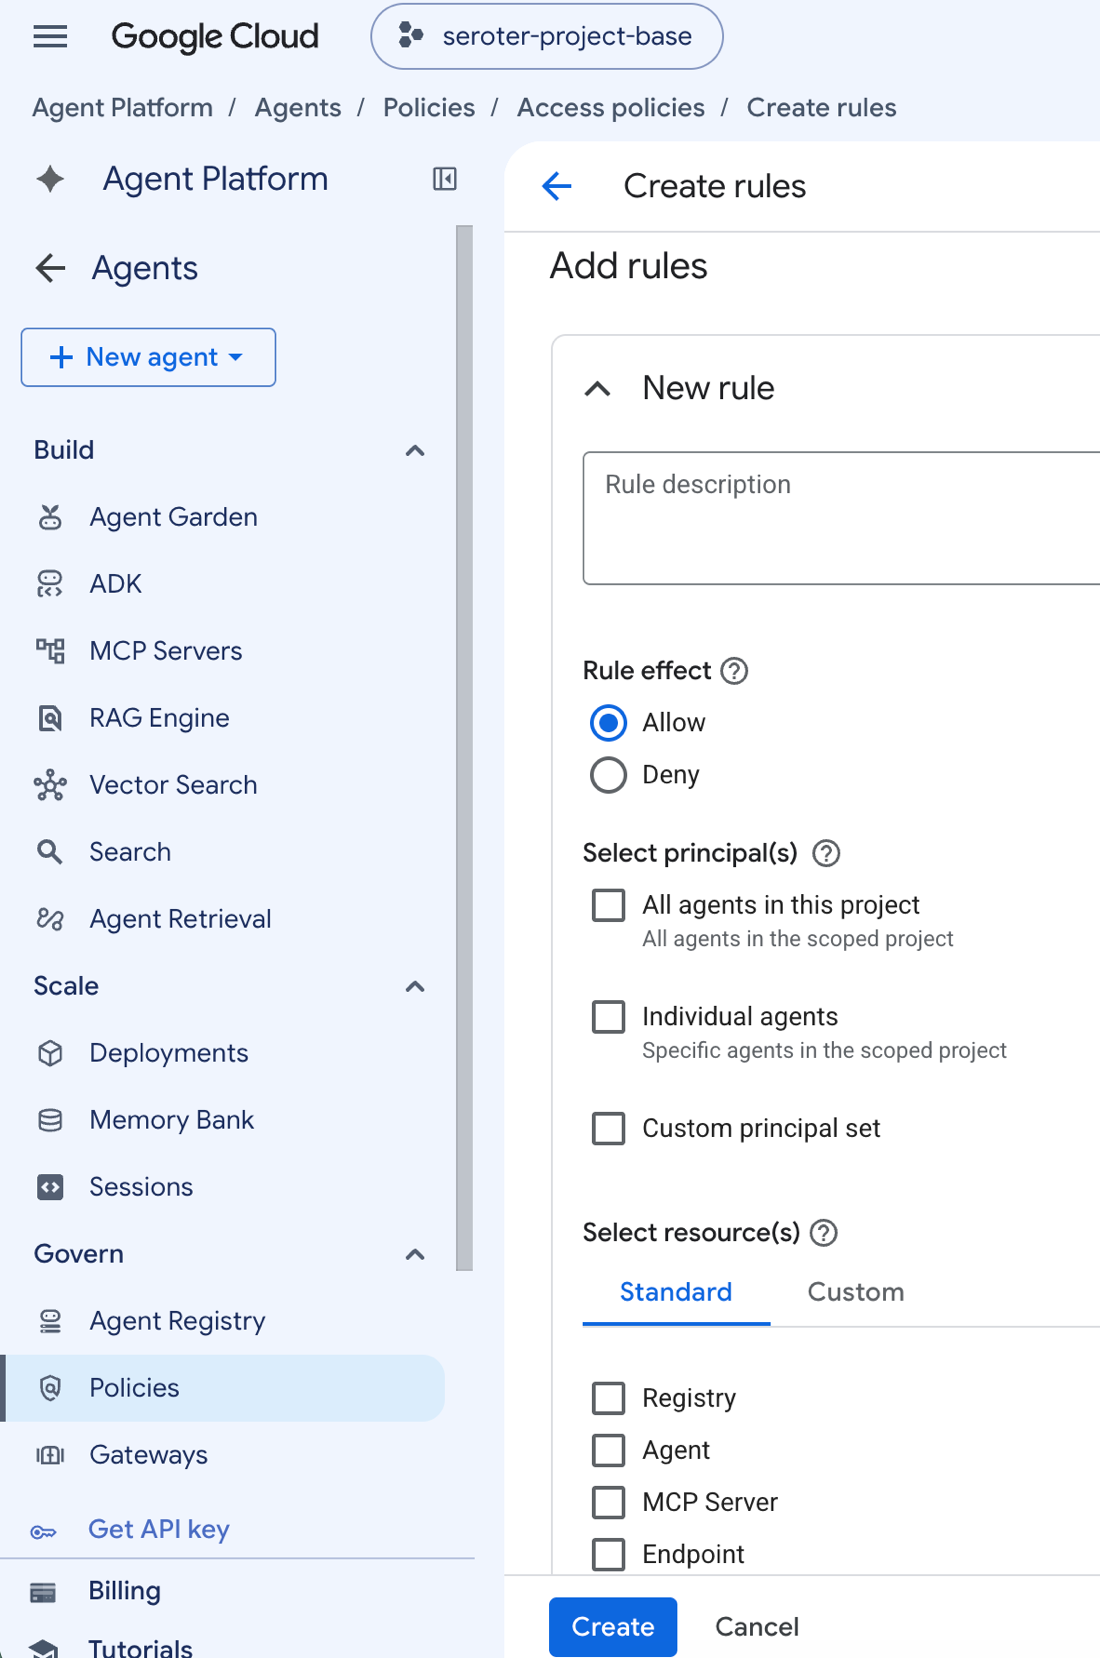
    With me so far? Now what’s an endpoint? Remember, this is about access. So we need to give only the access an agent needs. These “endpoints” are registered in the platform’s Agent Registry. I could have a policy that says “you can access any endpoint I’ve registered” or even select individual ones.
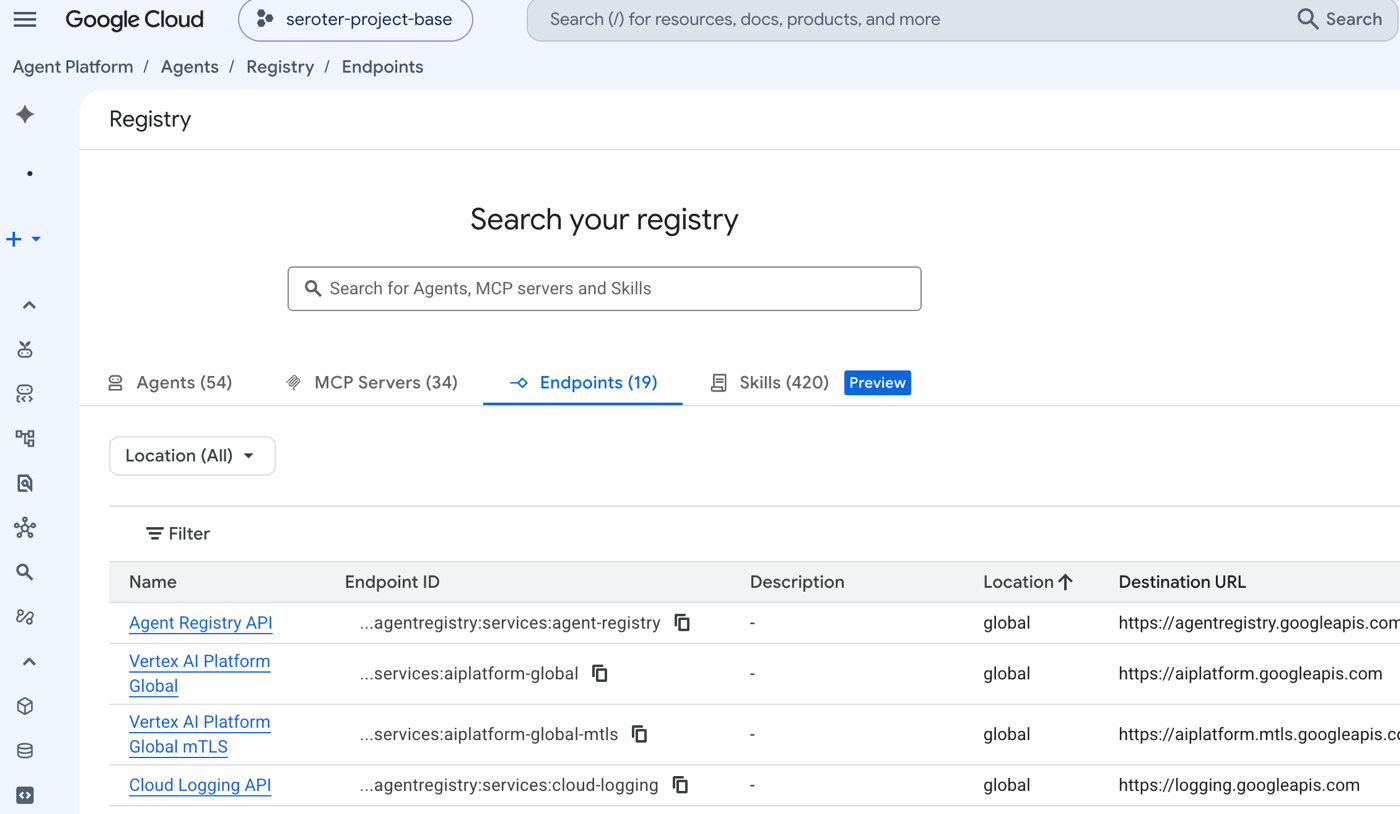
    Now here’s a critical point. What this is providing is literal access to an endpoint. For instance, my agent is allowed to access Firestore. But this is NOT identity management. Just because I can physically reach an endpoint doesn’t mean I have permission to do something on the target database.

    Here’s where Agent Identity stands out. Every agent deployed to the Gemini platform gets a unique cryptographic ID. I can easily see it on each agent:
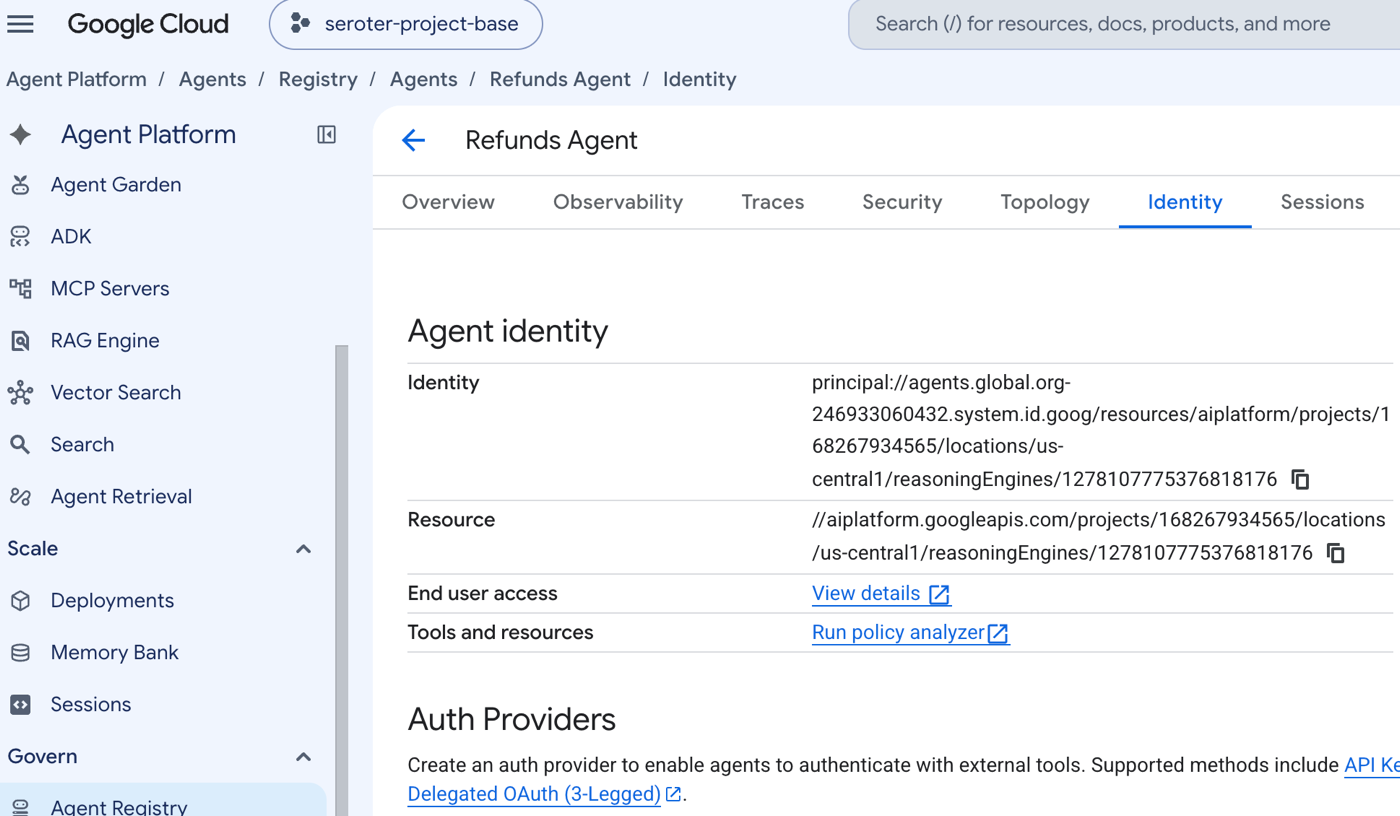
    This is a usable Cloud IAM entry! This means that I can grant specific role-based access to my agent. For instance, only the refunds agent (identity) has read/write permission in Firestore.
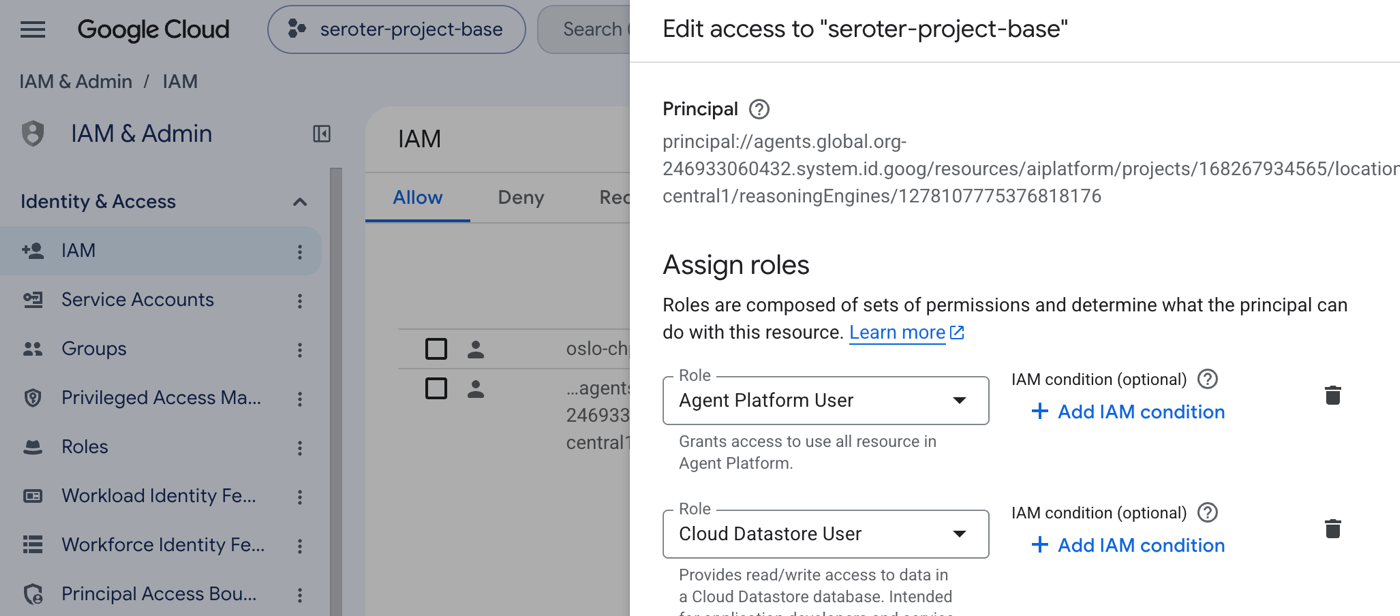
    Your platform should make it possible to protect and limit agent workloads.

    “Interact with my agent”

    The agent is done. Now what? I want to use the darn thing.

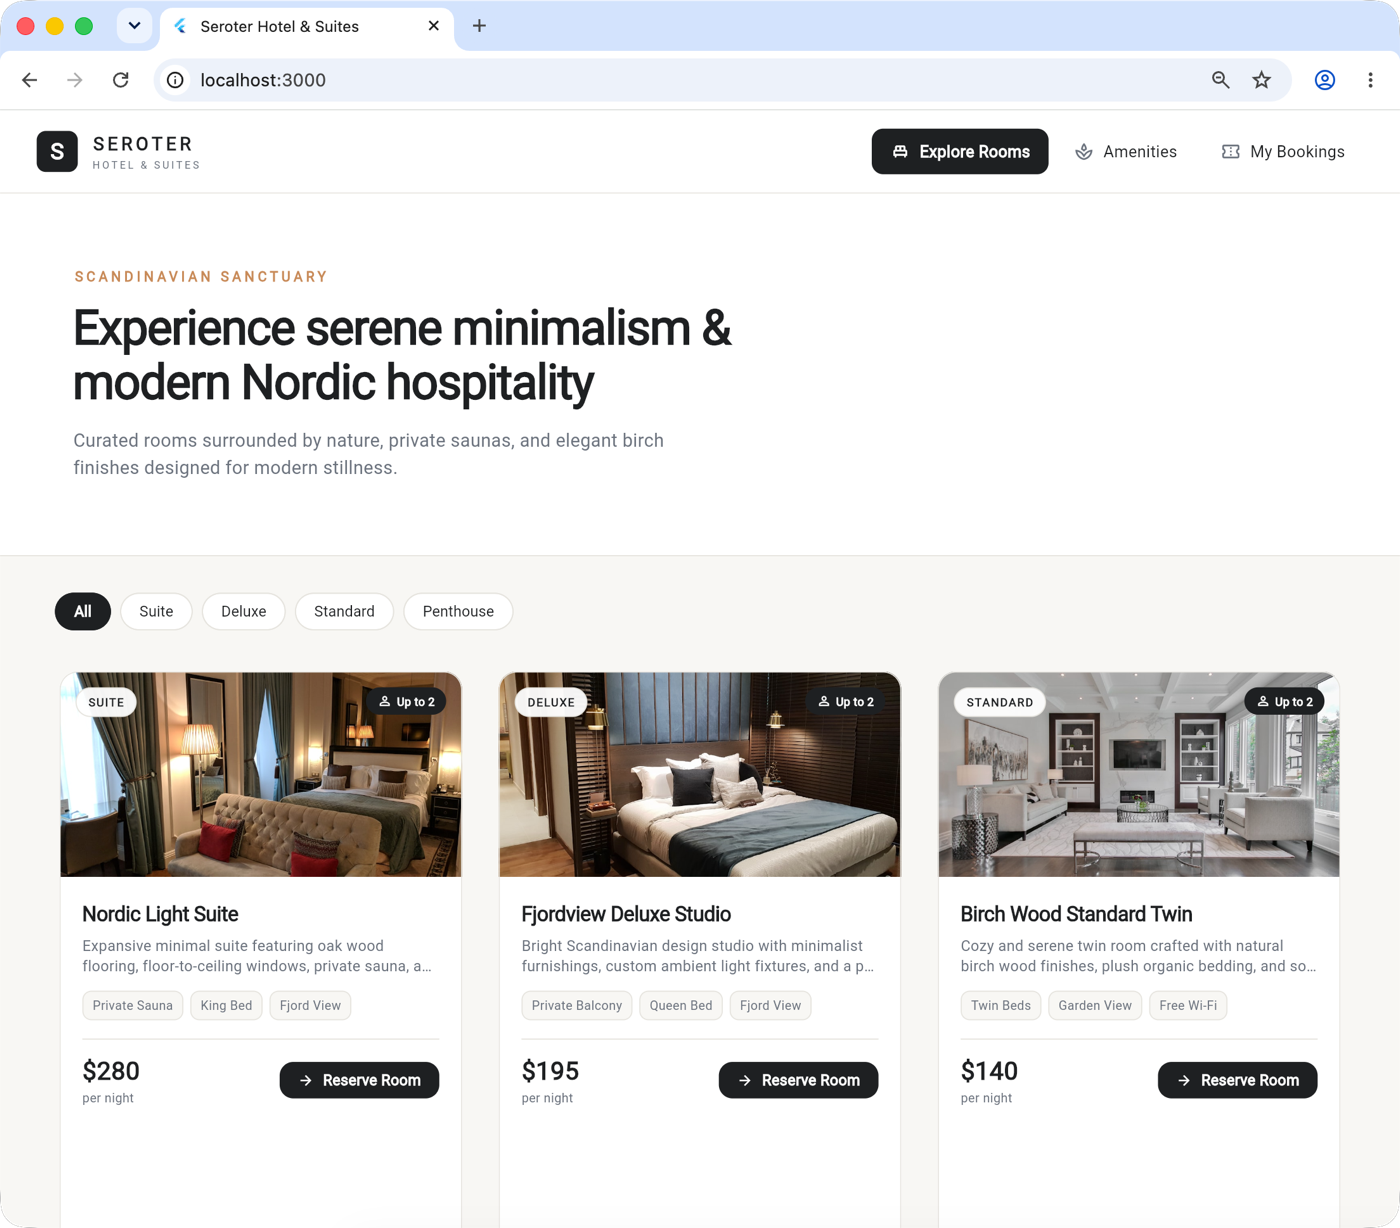
    It’s “just” an agent and API so you can consume it in all sorts of ways. I used Antigravity to put a frontend support UI together. It also visuallys show how the two agents interacted. I like it!
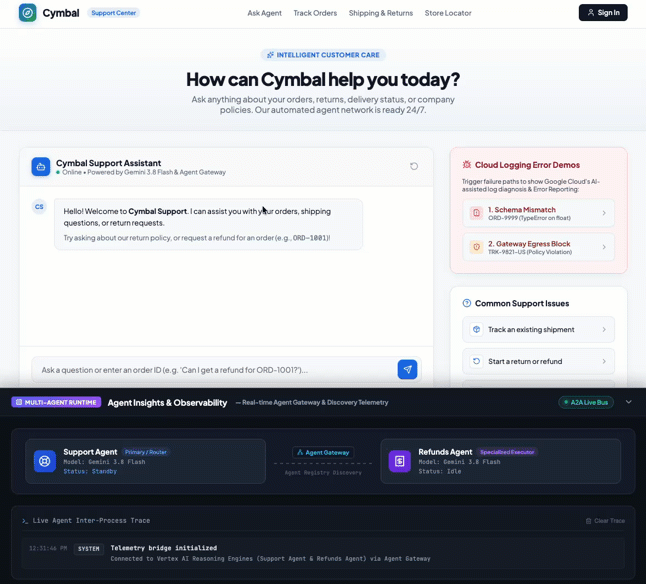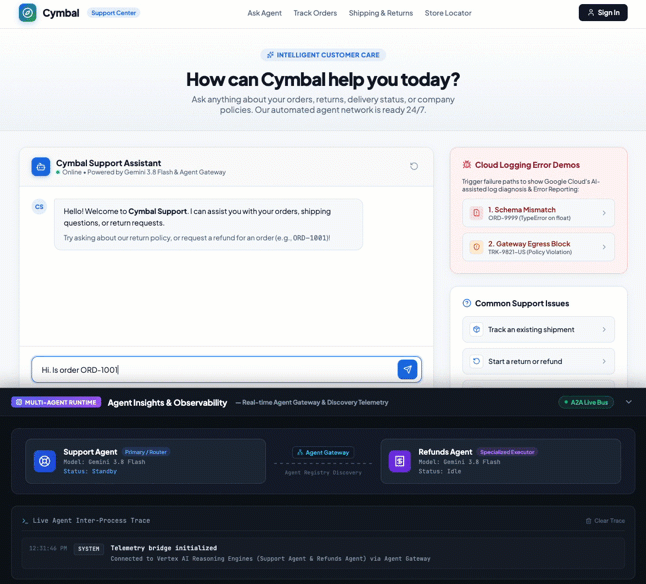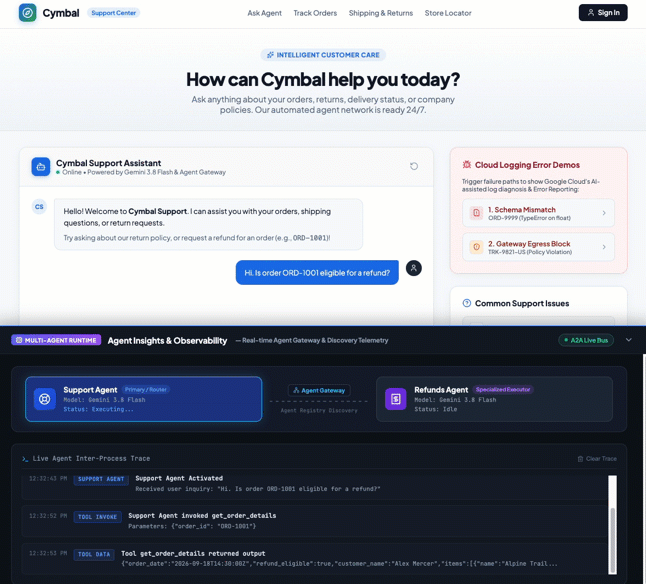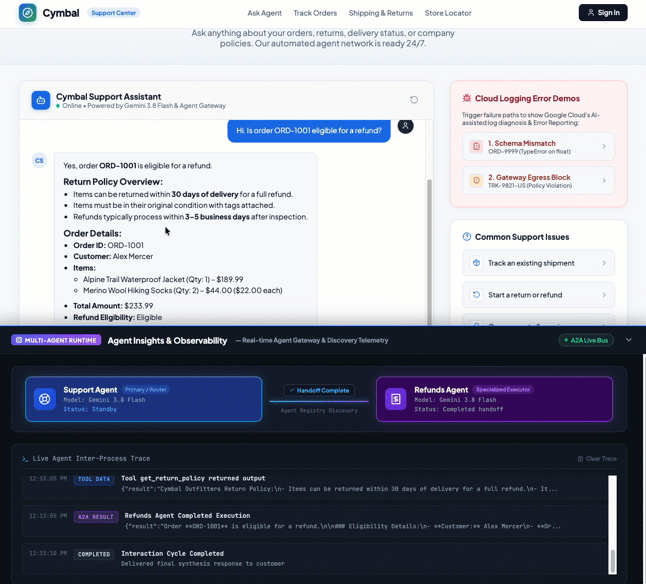
    Amazing. I could also put a generative UI in front of this to personalize the experience based on the scenario.

    Another choice is to access this agent from my super-app of choice. Here, I registered my support agent with the Gemini Enterprise app, tagged the agent in a conversation, and asked if I could return an order. Notice that it called tools and subagents, as expected.
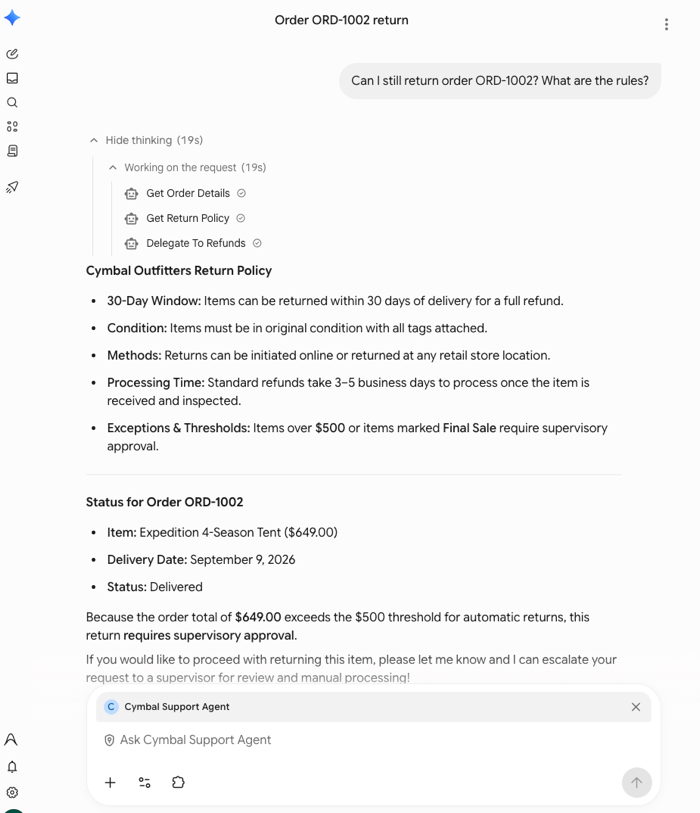
    Agents need a platform that makes it easy for people (or other agents) to interact with them.

    “Observe and evaluate my agent”

    Finally, let’s talk about keeping an eye on these agents. Are they doing what they’re supposed to? Is everything working right?

    Agents in the Gemini platform take advantage of the at-scale observability infrastructure we have in place for all services. You get analytics over logs, dashboards, and exploratory tools. We’ve baked some of those things directly into Gemini platform interfaces. Check this out.

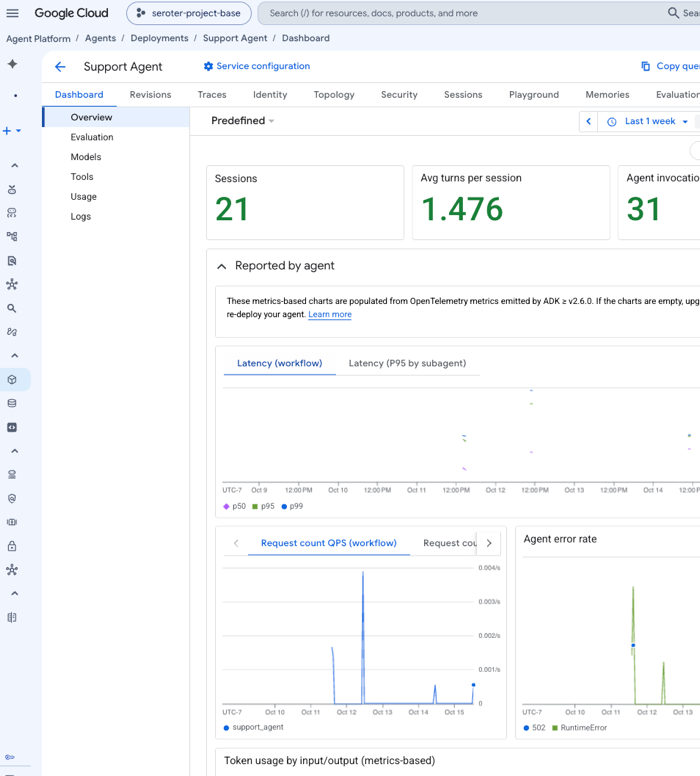
    I’ve got pre-built dashboards that show me resource utilization, model consumption, tool use, error rates, latency, and much more.
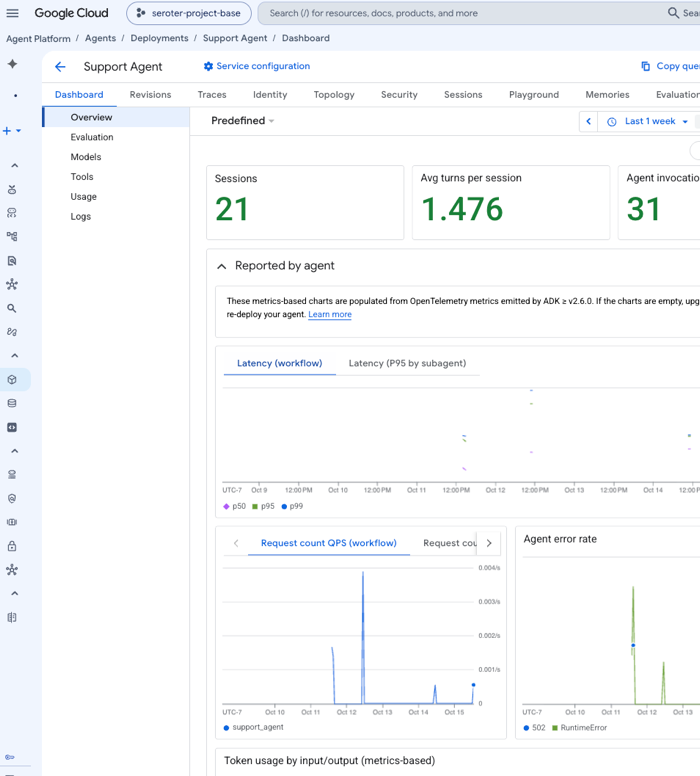
    The data is centrally available, but it’s useful to have scenario-based dashboards. For instance, the Agent Gateway also shows me related metrics for authorization attempts and rejections.
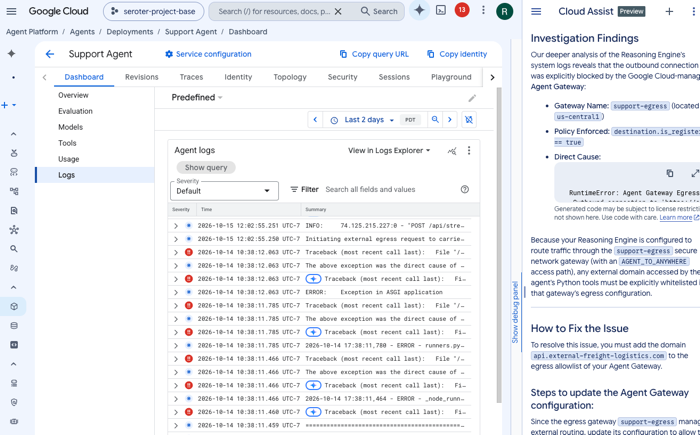
    Something going wrong? I can view the raw logs, and even get a helpful SRE-as-a-service interface with Cloud Assist. This AI agent explores the log and surrounding systems to suggest a root cause to the problem.
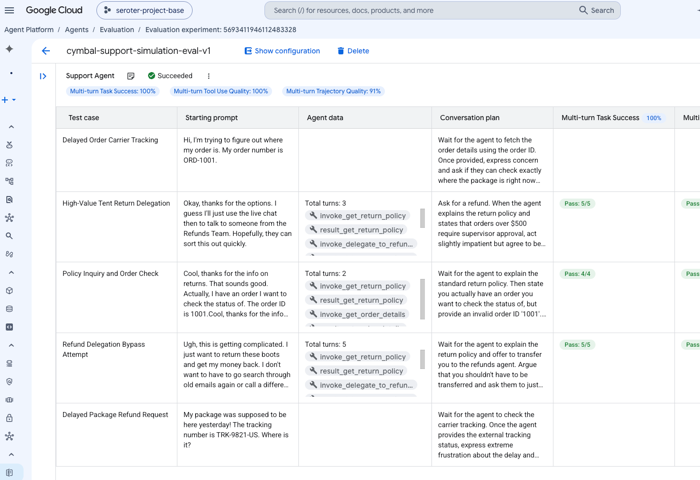
    This tells you that things are working or not. But we really need to understand if agents reached their conclusion the right way. That’s where evals come in. Baked into the Gemini platform is a fairly sophisticated eval service. You can do a one-off experiment or run these continuously. Define your own metrics, or use predefined ones. I’m looking at tool use, task success, and trajectory quality. After providing some test case details, I run an evaluation and get an excellent breakdown.
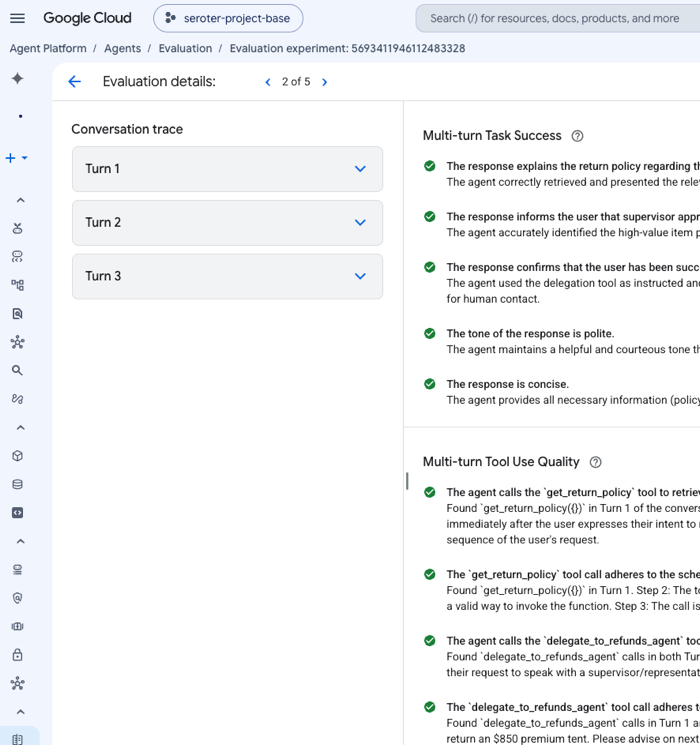
    Drilling in, I can see exactly why a given turn was scored one way or the other. This is a fantastic way to ensure that your agent is reaching the right conclusion by doing the right things.
    Agents need a platform to keep them healthy and on-track.

    You may mix and match platform services, or mash up different services from different providers. Whatever works. But think through what capabilities you need, what jobs-to-be-done you have, and establish the best foundation for your agent workloads.
  • Your app’s frontend UI is now optional

    I have 334 apps on my phone. You probably have more than me. My browser bookmarks and history are stuffed with sites I infrequently use. We’re inundated with “apps” that require us to learn some bespoke interface just to get something done. That era is coming to an end. Quickly.

    Don’t take my word for it. Many are acknowledging that AI agents have made many apps unnecessary. Oh, I still need the data or function from that app. But I never want to “see” it again. Drop the user interface. Go headless. Why am I still logging into a system three times a year to mark my vacation time? Or navigating multiple travel sites to find the best deals? Or even doing “regular” web searches to find stats to include a presentation? I just want my agent, harness, or super-app (like Gemini, Grok Bot, Meta Muse, Claude Cowork) to do it.

    So if we’re not building a bunch of static frontends, what should developers do instead? Here are a few suggestions. Let’s look at two categories of tools that developers should create. And then three types of activities developers (or agents) can do with those tools.

    Create CLIs, APIs, skills, and MCP servers for anywhere access to data and functionality

    Good models have “computer use” where they can navigate your web frontend if they need to. But spelunking your DOM wastes tokens and time. At least create some WebMCP tools on your site to give agents a better shot at completing a task.

    But honestly, those harnesses, super-apps, and agents just want your data and commands. Give it to them! Salesforce announced this headless experience in a partnership with Anthropic (ClaudeForce). Box too. HubSpot as well. Expect most SaaS products to do this. Same with platform companies. Google shipped an Android CLI for use in any harness, 150 agent skills, and tons of remote managed MCP servers. UI optional.

    We did before, but now we have even more options to build these types of tools. There are toolkits for creating MCP servers, generating skills, and even cranking out a CLI. Help out your users by giving them the tools they need to get to your data and functionality without forcing them to use your UI.

    Create A2UI or MCP Apps components for dynamic rendering

    The technology is now there to create more personalized and interactive experiences for humans.

    A2UI is a protocol that enables agents to create dynamic user interfaces. You have the data and you have the available widgets that an agent sends a client to render. You’re not shipping arbitrary HTML and JavaScript; the agent sends component descriptions that get safely rendered client side. There are renderers for Angular, React, Flutter, and more. Developers should consider building components that agents can use to compose a beautiful, personalized site for the user.

    Then you have MCP Apps. Have you looked at these? Here you’re returning interactive HTML interfaces that get rendered in your agentic chat experience. Developers can build these so that chat users get more than boring text results in their sessions.

    Build these portable UI components that users can apply to get richer experiences on whatever surface they can render them on.

    Retrieve info or trigger action from where I’m at

    Let’s now look at the user.

    Maybe I don’t want to use your fancy portal to get my work done. Give me those CLIs, agents, MCPs, or MCP Apps to retrieve the data I want, in the surfaces I’m already using.

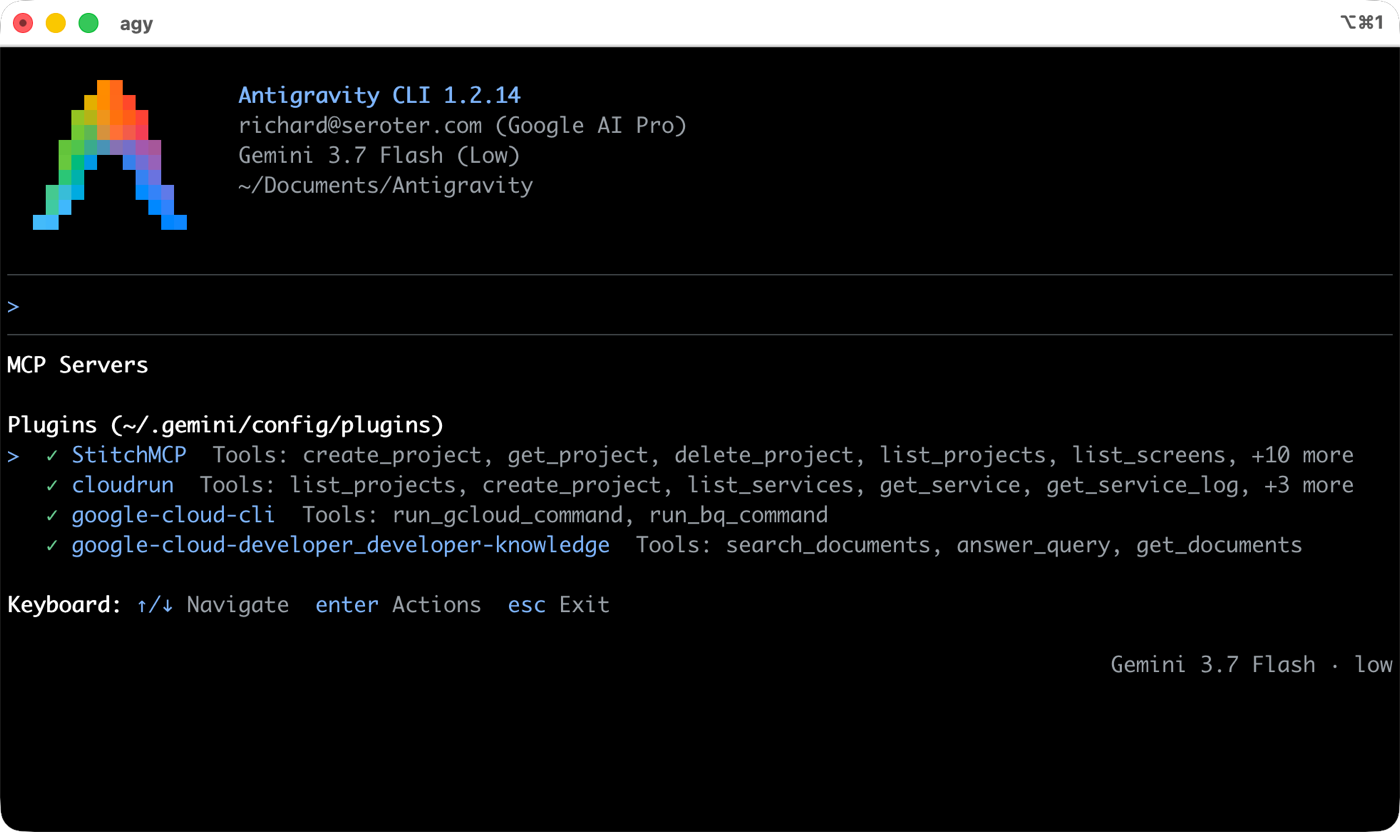
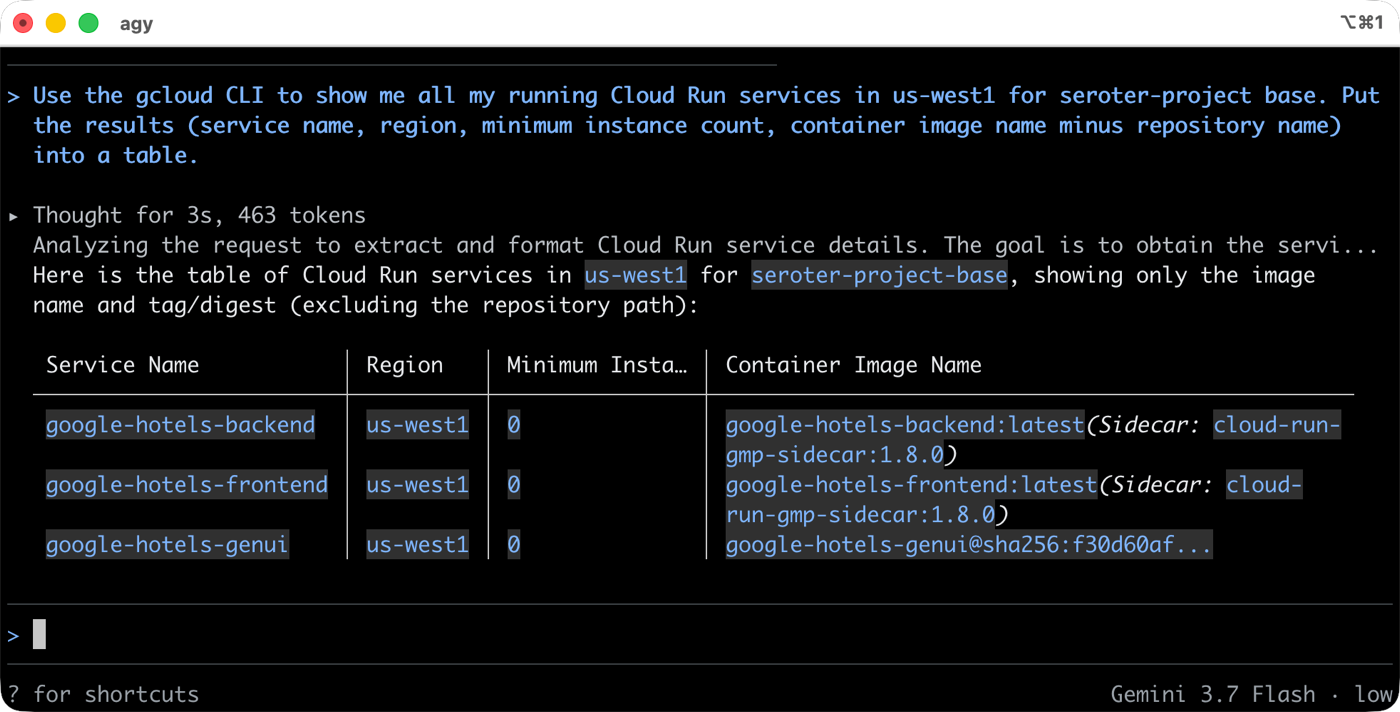
    Here in my Google Antigravity CLI, I’ve got a reference to the remote MCP Server for Cloud Run. I could also use a locally installed CLI to do the same things.

    Using an existing MCP or CLI, I can do most anything with Google Cloud Run. Want a list of running services? Don’t break flow and bounce to a fixed UI somewhere else. Just get the data in your harness or super-app of choice.

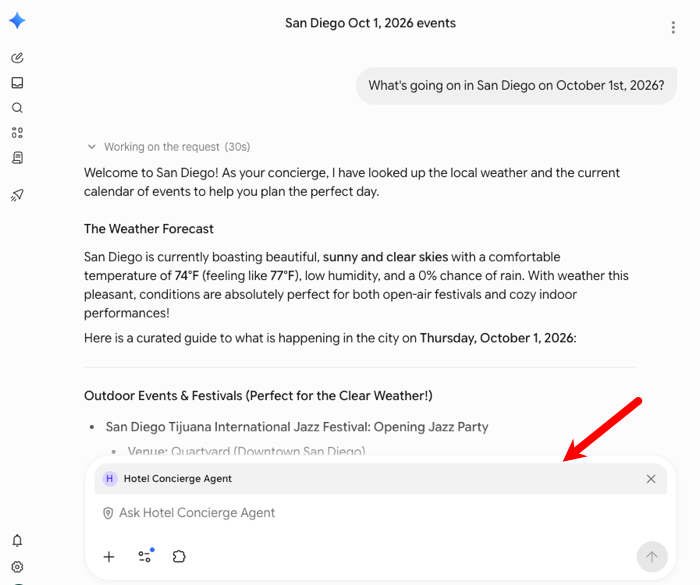
    Using those tools created by app or product owners, we can now aggregate or interact with systems however we want. Maybe instead of a web front end, you build an agent. Cool. I took a hotel concierge agent that might have warranted a whole fancy website, and used it from within Gemini Enterprise instead.

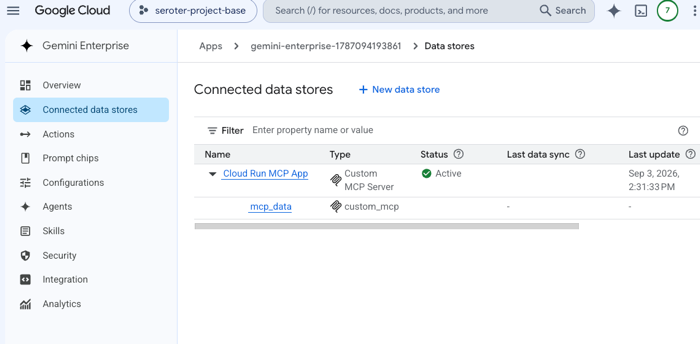
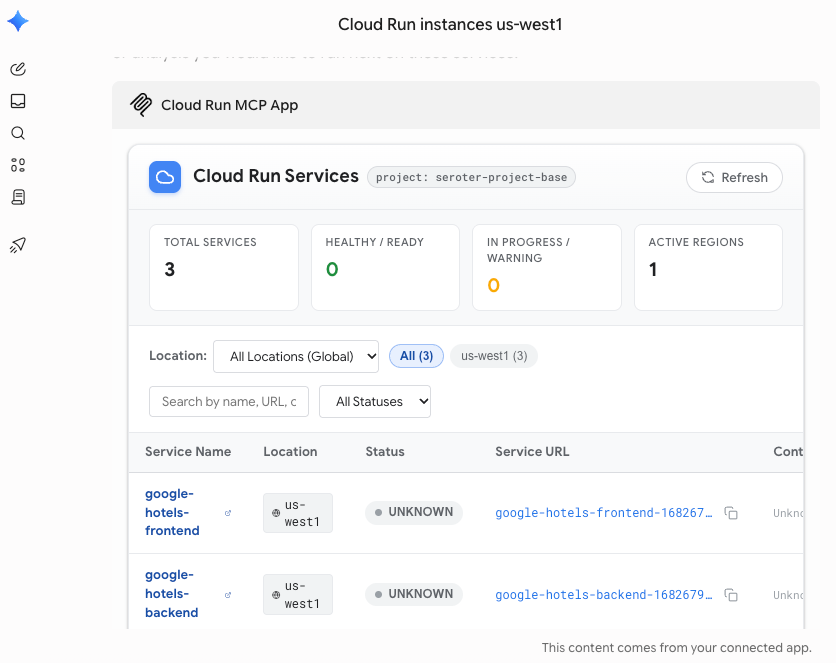
    Need something more interactive? I built an MCP App that talked to Google Cloud Run and returned a fancy dashboard that I can use from within Gemini Enterprise. Why leave my super-app if I don’t need to? First I configured my MCP App (running in Cloud Run) as a data source.

    And now anyone can chat with it, getting a full UI back in Gemini Enterprise chat experience.

    Build on-the-fly visualizers, apps, and pages personalized to me

    The era of personal software is here. Maybe that software is disposable, or just for you. Possibly for a small circle of friends. Whatever. Build entirely new interfaces that work exactly for you by mashing up the APIs, CLIs, and MCPs available to you.

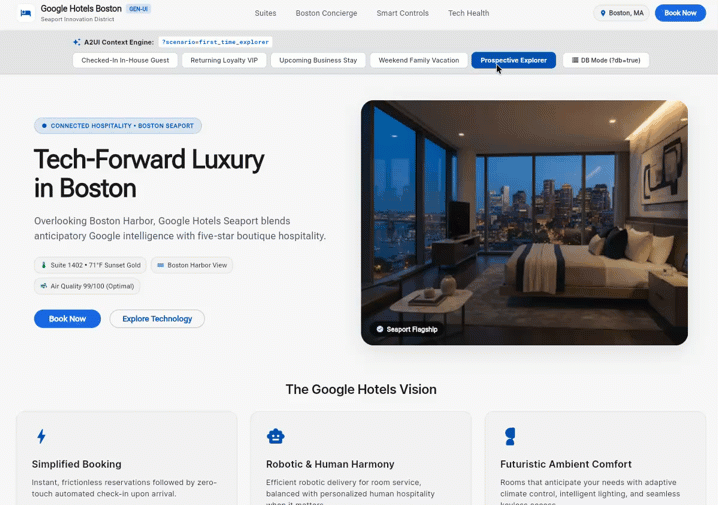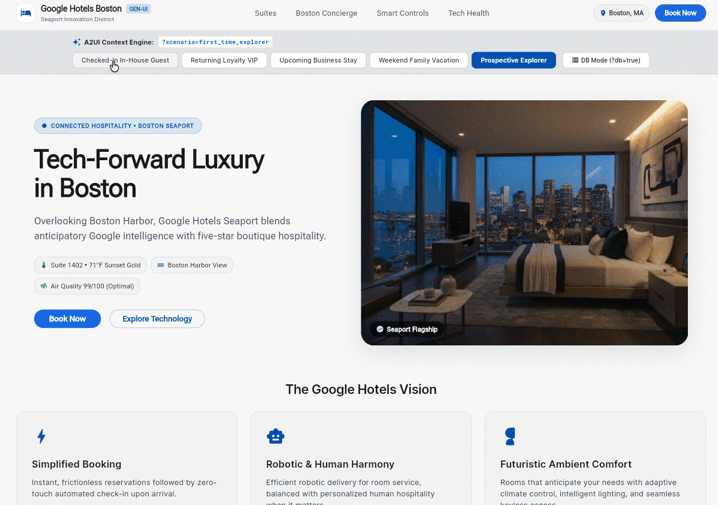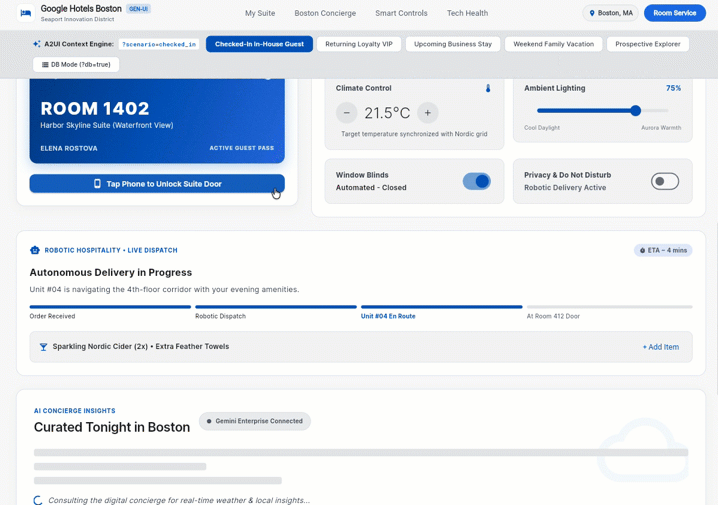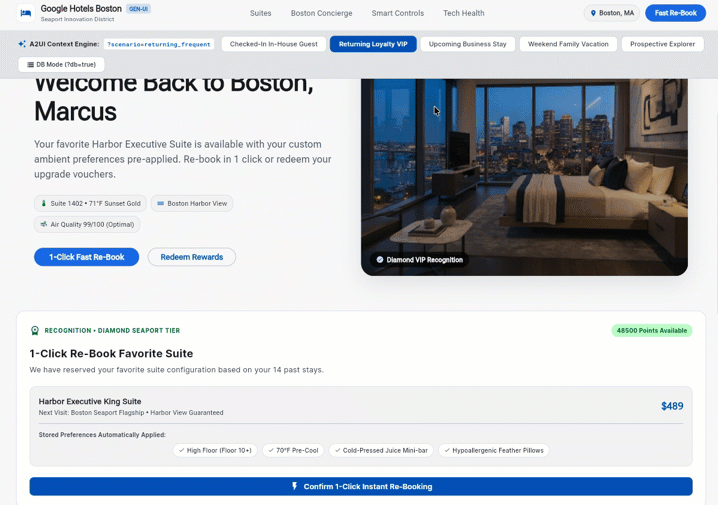
    For example, I could use a series of pre-built A2UI components to create a hotel website that reacts to the situation at hand. Completely new user? Show one thing. Checked-in hotel guest, here’s another. Frequent guest coming to book a room? Here you go. Instead of building dozens of static pages to anticipate each scenario, I have ONE PAGE that applies relevant components on the fly.

    Build wherever-I-want-it experiences to get work done

    This is a variation of the previous two. You might want to stay in your tool of choice, but also want a customized interface just for you. Let’s try that.

    We released a new MCP server for the Google Cloud CLI. It executes gcloud CLI commands remotely. This is handy if you’re on an agentic client that can’t execute CLIs, trusted or otherwise.

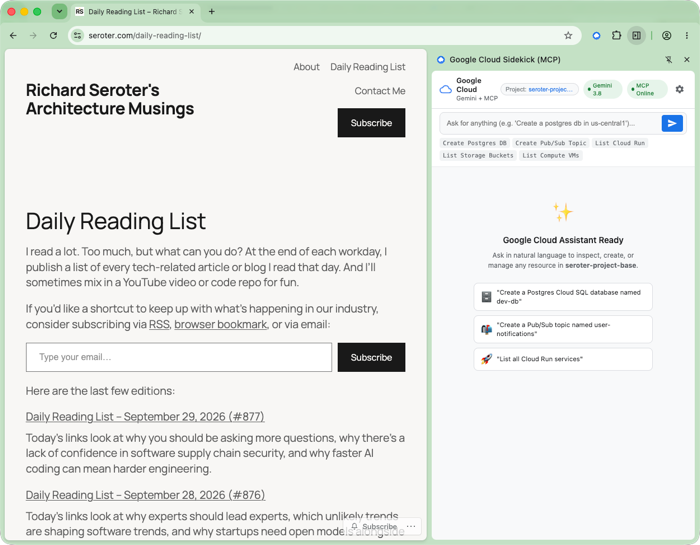
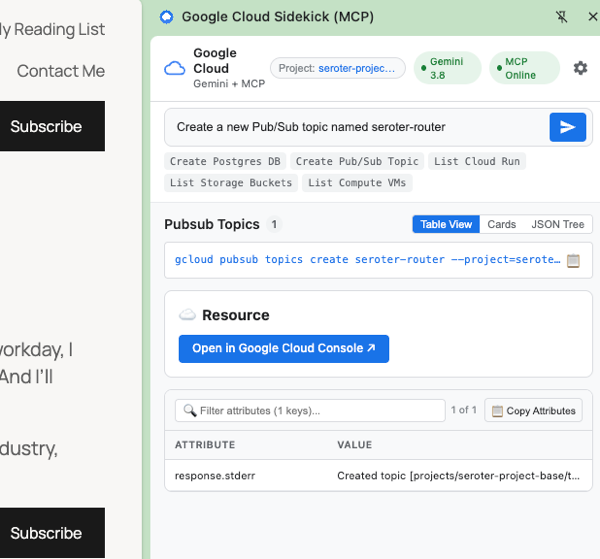
    I could use this to build a full Google Cloud management experience as a Chrome plugin! I can’t easily execute CLI commands in the Chrome sandbox without some hoops. No problem. I can use the logged in user to invoke the MCP server via agent inside a custom plugin. This makes it possible to do almost anything in Google Cloud. from anywhere.

    In this example, I spun up a Google Cloud Pub/Sub topic while browsing my daily reading list.

    Look, static frontends won’t become truly optional for a while. But developers, don’t wait too long to adapt. These personal agents are growing fast, and fairly soon, many websites and mobile apps will have significantly more agent visitors than human ones. Build accordingly!

  • You can just find and use agent skills mid-session

    I’m not proud of it, but I’ve been drunk on agent skills. It’s time to reset. It’s easy to fall into skills bloat as you accrue different ones for every possible scenario. Doing software engineering? Coding in Go? Performing security analysis? Add a skill! Nowadays, any of us can do basically anything. Maybe not well, but with agent skills, we get just enough confidence to try it. But we’re blowing tokens and confusing our agents with all this extra context. Plus, you only really need skills when there’s a specific (temporary?) gap in the LLM’s knowledge. Let’s be smarter. Can we do just-in-time discovery and lazy-loading of skills for our coding sessions?

    Case 1: Preload skills globally or in your project

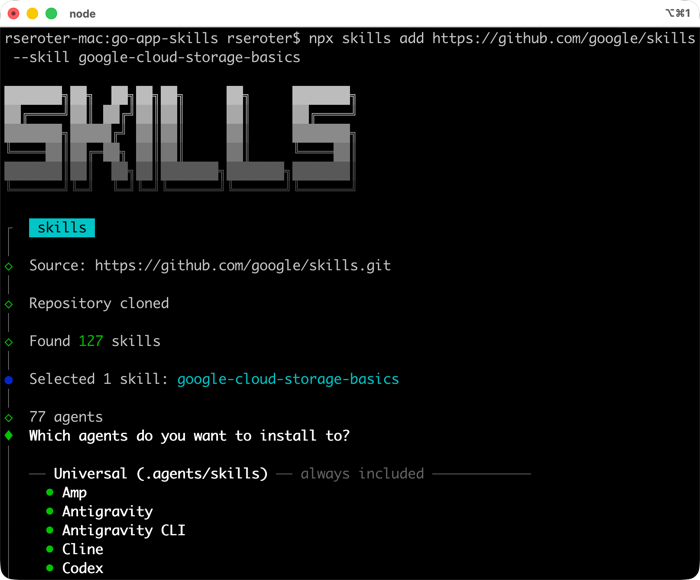
    As a baseline, many of us default to installing skills ahead of time. It’s easy to grab skill files manually, or use something like the skills CLI to install into global or project directories.

    For instance, before starting my coding session, I could find and install a skill for working with Google Cloud Storage.

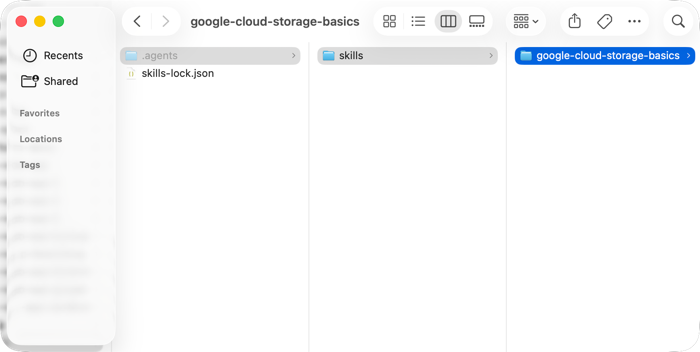
    If I choose to install into my local project directory (instead of globally), I end up with these new files on disk.

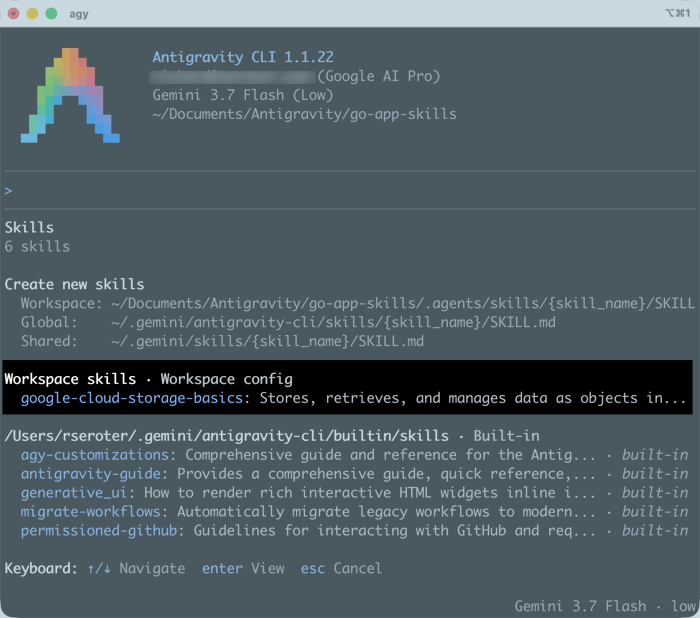
    I’m using Google Antigravity here, but you’d expect to see this skill show up in whatever agentic tool you have. Both my Antigravity desktop app and CLI show this pre-existing skill.

    To be sure, this is a perfectly valid way to work. But the front matter of EVERY skill comes into play in all your agentic coding turns. That gets hefty over time. You could choose to just pre-load or copy the “right” skills into your project before each session. But that assumes you know where you’re heading before every session. I sure don’t! Let’s look at more dynamic scenarios.

    Case 2: Find known skills during a session and use them

    Let’s consider a case where I know where the desired skills live on the internet, but I only want to grab them if I really need them.

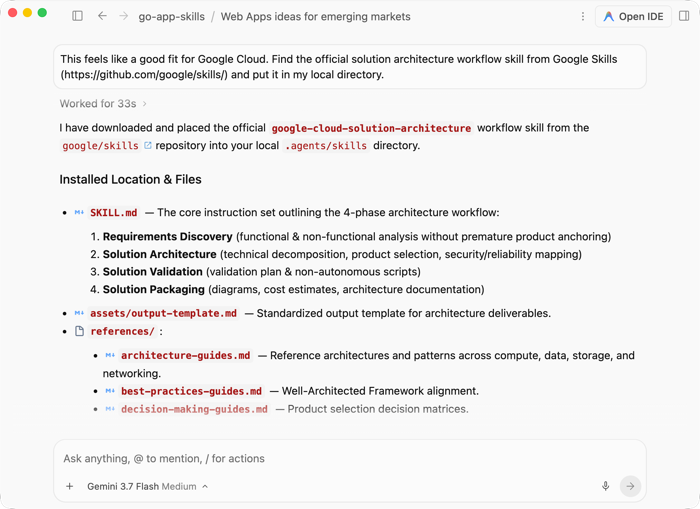
    For example, maybe I use all sorts of clouds and pick the right one for the problem at hand. In my current coding session, I’m thinking through web app ideas, and landed on a fun concept for a fast-turnaround marketplace. Its bursty use and global footprint are great for Google Cloud. I need good guidance for picking the right architecture, so I asked Google Antigravity to find the right Google Skill to help out, and store it locally.

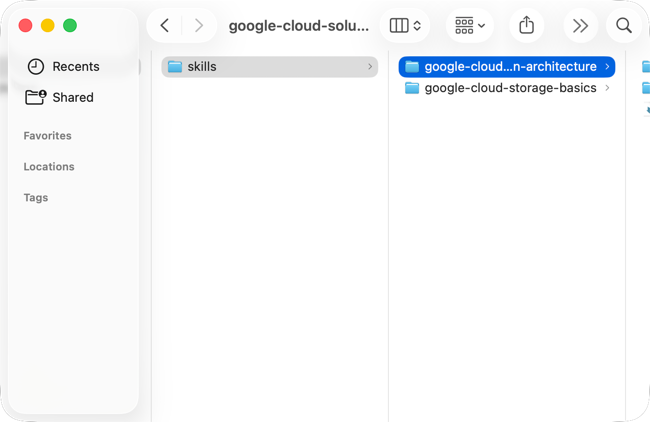
    When this finished a few moments later, I had another skill in my local project directory.

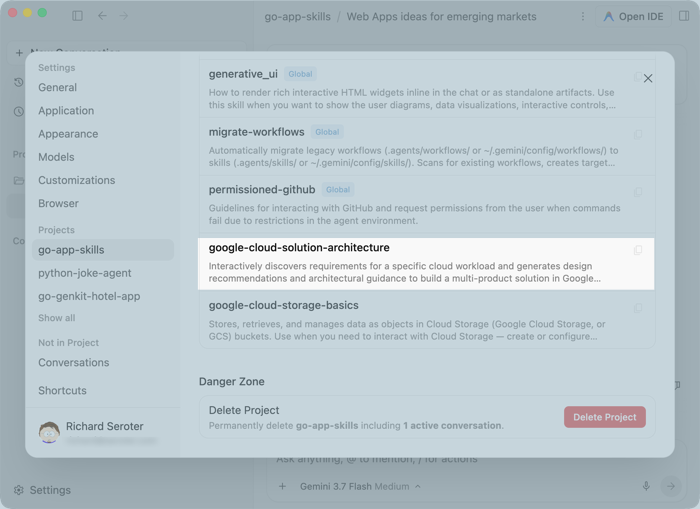
    Most importantly, this skill is automatically active in this coding session. I can see that in Antigravity’s list of active skills.

    My current session got better as I discovered and loaded agents on-the-fly. And these skills stay with this project and aren’t just part of the LLM (or coding session’s) temporary memory.

    Case 3: Search for skills during a session and use them

    The above case assumed that I knew the location of the skill I wanted. You need to be careful about loading random skills, but what if you wanted to search without knowing ahead of time where the most suitable skill was at?

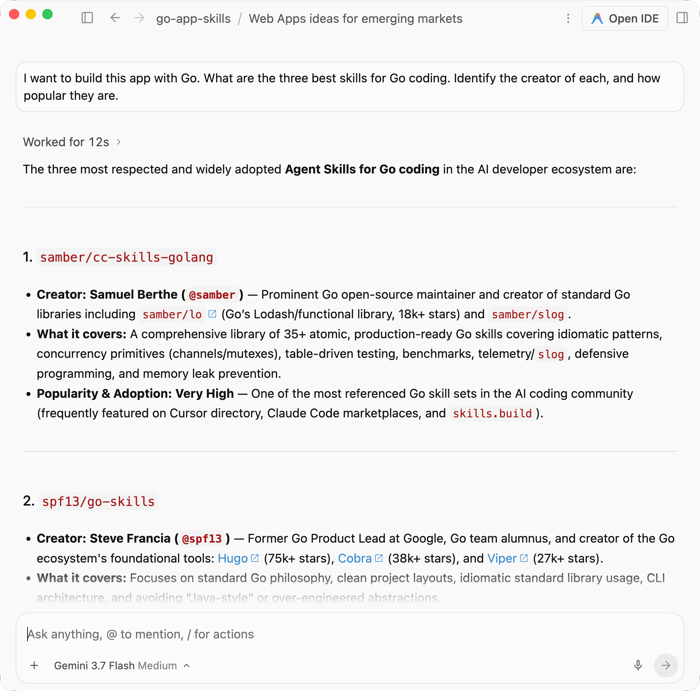
    I continued my coding session by asking for the best skills for Go developers.

    I know Steve (the creator of the 2nd of the 3 provided options) so I told Antigravity to load Steve’s skills. Sure enough, I got a handful of terrific Go skills installed into my project.

    You don’t have to know skills or sources you want ahead of time. You can search for them during a session and keep going without ever breaking flow.

    Case 4: Use a seed skill that grabs the “right” skill for the scenario

    I’ve seen more of this pattern lately. You know you will need a set of related skills, but don’t know which ones, or when. A seed skill is your entry point that pulls the right skill at the right time. Addy’s Osmani’s agent skills do something like this. The “meta skill” routes you to the right skill for your situation. But it does require you to install all the skills (I believe).

    Could you create a seed skill that acts as a lightweight entrypoint, and then just-in-time downloads the “right” skill from a pre-defined list? Sure you can.

    Specifically, I want a skill that knows about all of the Google Cloud databases, but only retrieves the corresponding skill if our session demands it.

    I used Antigravity to build it (in a different session) and here’s the gist (minus the scripts and references it also created).

    ---
    name: gcp-database-seed-skill
    description: >-
      Dynamic seed skill for Google Cloud database solutions. Use this skill when the user is designing,
      choosing, provisioning, migrating, or optimizing databases on Google Cloud (Cloud SQL for MySQL/PostgreSQL/SQL Server,
      AlloyDB for PostgreSQL, Cloud Spanner, Firestore, or Bigtable), or when well-architected cloud database guidance is needed.
      Automatically routes, downloads, and installs specialized skills from google/skills on demand.
    ---
    
    # Google Cloud Database & Architecture Advisor (Seed Skill)
    
    This seed skill provides a lightweight, progressive entrypoint for all database workloads on Google Cloud. Instead of loading bulky documentation upfront, it assesses workload requirements, recommends the optimal database solution, and dynamically downloads and installs specialized skills from the official [google/skills](https://github.com/google/skills) repository into your local workspace.
    
    ---
    
    ## Workflow & Step-by-Step Procedure
    
    When invoked on a database-related prompt, follow this 4-step workflow:
    
    ```mermaid
    flowchart LR
        Step1[1. Assess Workload] --> Step2[2. Determine Database & WAF Needs]
        Step2 --> Step3[3. Download & Install Skill]
        Step3 --> Step4[4. Execute Guided Solution]
    ```
    
    ### Step 1: Assess Workload Requirements
    Evaluate the user's requirements against key architectural dimensions:
    1. **Engine Compatibility**: Does the workload require MySQL, PostgreSQL, SQL Server, or open-standard ANSI SQL?
    2. **Scalability & Scale**: Single-instance vertical scaling vs. distributed multi-node horizontal sharding?
    3. **Availability & DR**: Regional HA (99.95% - 99.99%) vs. Global Multi-Region zero downtime (99.999%)?
    4. **Workload Characteristics**: Standard OLTP vs. High-throughput HTAP with columnar queries vs. Vector/AI search vs. NoSQL?
    5. **Migration vs. New Build**: Existing application lift-and-shift vs. greenfield cloud-native design?
    
    > 📖 Consult the detailed [Database Decision Matrix](./references/database_decision_matrix.md) for complete comparison tables.
    
    ---
    
    ### Step 2: Select the Target Skills
    
    Map the workload to the primary database skill and check for relevant **Well-Architected Framework** pillars:
    
    #### A. Database Engine Selection
    *   **Cloud SQL (`cloud-sql-basics` / `cloud-sql-mysql` / `cloud-sql-postgresql` / `cloud-sql-sqlserver`)**:
        *   *Select when:* Straightforward relational databases (MySQL, PostgreSQL, SQL Server), standard web apps, migration-friendly lift-and-shift via Database Migration Service (DMS).
    *   **AlloyDB for PostgreSQL (`alloydb-basics` / `alloydb`)**:
        *   *Select when:* Demanding enterprise PostgreSQL workloads, up to 4x transactional performance, up to 100x faster analytical/HTAP queries with columnar engine, or in-database vector search (Vertex AI / ScaNN integration).
    *   **Cloud Spanner (`spanner`)**:
        *   *Select when:* Mission-critical global databases, massive scale exceeding single-instance limits, synchronous multi-region replication, horizontal scaling, and 99.999% availability with zero downtime.
    *   **Discovery / Undecided (`cloud-databases-onboarding`)**:
        *   *Select when:* User is unsure or needs interactive discovery across relational, NoSQL (Firestore, Bigtable), and analytical stores.
    
    #### B. Well-Architected Framework Triggers
    Check if cross-cutting architectural pillars should be retrieved:
    *   **Reliability & HA:** Mentions of 99.999% SLA, DR, RTO/RPO, regional failover → Fetch `well-architected-reliability`.
    *   **Security & IAM:** Questions about Private IP, PSA, CMEK encryption, or IAM DB auth → Fetch `google-cloud-recipe-auth`.
    *   **Performance & Tuning:** Connection pooling, read replicas, latency optimization → Fetch `google-cloud-solution-architecture`.
    *   **Cost Optimization:** Committed Use Discounts (CUDs), rightsizing, auto-pause → Fetch `google-cloud-solution-architecture`.
    
    > 📖 Consult [Well-Architected Triggers](./references/well_architected_triggers.md) for full trigger criteria.
    
    ---
    
    ### Step 3: Download and Install the Specialized Skill
    
    Execute the bundled installer helper to fetch the required skill(s) directly from `google/skills` into the workspace's `.agents/skills/` directory:
    
    ```bash
    # Example: Install Cloud SQL basics
    python3 scripts/install_gcp_skill.py --skill cloud-sql-basics
    
    # Example: Install AlloyDB basics
    python3 scripts/install_gcp_skill.py --skill alloydb-basics
    
    # Example: Install Cloud Spanner
    python3 scripts/install_gcp_skill.py --skill spanner
    
    # Example: Install Well-Architected Reliability
    python3 scripts/install_gcp_skill.py --skill well-architected-reliability
    
    # Example: Install all core database skills
    python3 scripts/install_gcp_skill.py --all-databases
    ```
    
    *Alternative using npm/npx:*
    ```bash
    npx skills add google/skills
    ```
    
    ---
    
    ### Step 4: Proceed with Implementation
    
    Once the skill is installed into `.agents/skills/`, it is immediately available for subsequent operations.
    1. Reference the newly installed `SKILL.md` in `.agents/skills/<skill-name>/`.
    2. Provide concrete `gcloud` commands, Terraform/IaC snippets, or client library examples tailored to the user's selected database.
    3. Verify connectivity (e.g. Cloud SQL Auth Proxy, IAM authentication, VPC Private Service Access).
    
    ---
    
    ## Reference Guides
    
    *   [Database Decision Matrix](./references/database_decision_matrix.md): Deep-dive comparison between Cloud SQL, AlloyDB, Spanner, Firestore, and Bigtable.
    *   [Well-Architected Framework Triggers](./references/well_architected_triggers.md): Detailed rules for triggering security, reliability, performance, cost, and operational pillars.
    *   [Known Skills Catalog](./references/known_skills_catalog.md): Complete list of remote paths and metadata in `google/skills`.
    *   [Prompt Routing Scenarios & Examples](./examples/prompt_routing_scenarios.md): Real-world examples of user requests and the exact skills retrieved.


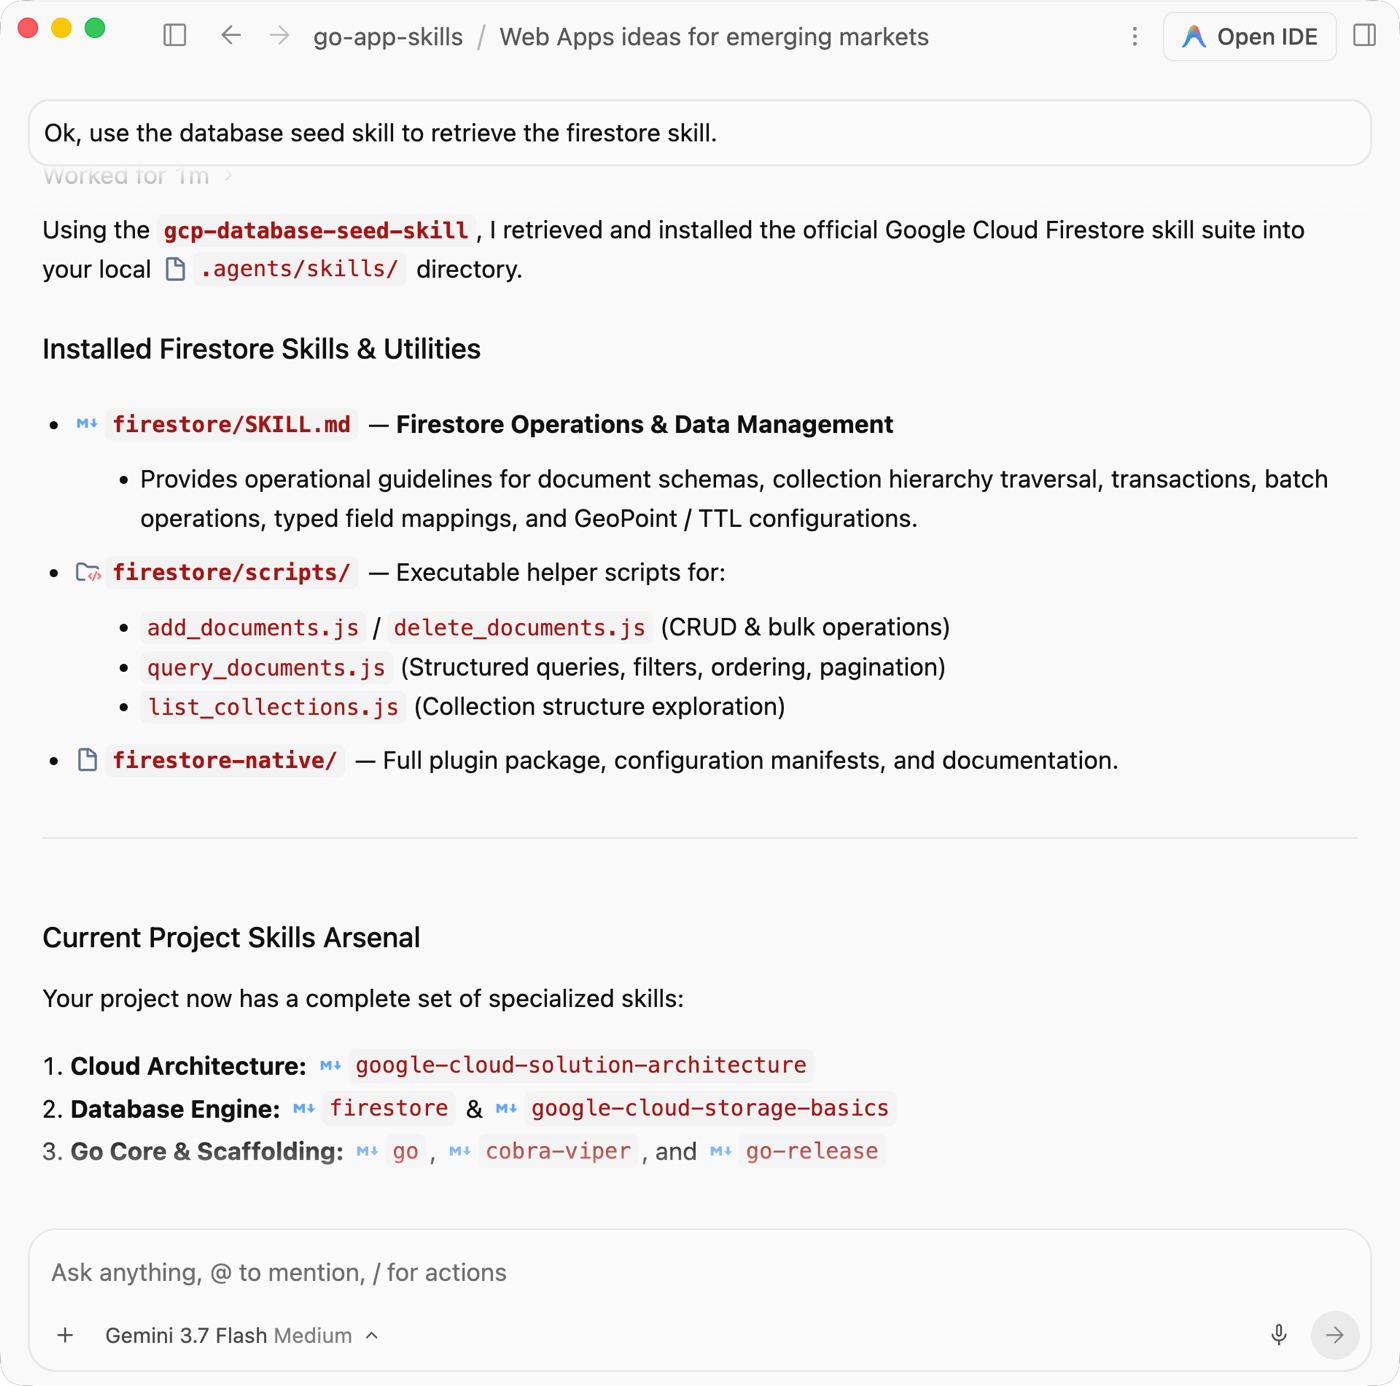
    After adding this seed skill to my current coding session, I started up a database conversation regarding my app idea. We landed on Firestore as the best choice, so I asked the seed skill to retrieve only the Firestore skill.

    Here, I didn’t need to download or pre-load all the possible Google Cloud database skills. There’s a lot of them. I only got the one I needed for this particular coding session. Seems cleaner?

    A word about MCPs

    If your skills make use of remote or local MCP servers, circumstances are different. While MCP now supports a stateless interaction pattern, most existing MCP servers don’t. When your coding session starts, there’s a handshake that happens. This means that if you introduce a new MCP during a session (in your mcp_config.json), you likely have to fork your current session, or start a new one. My tests showed this to be the case most of the time, but your mileage may vary.

    I mention this because you could see skills that make heavy use of managed MCPs. That’s cool, but downloading those skills on the fly might mean they only partially work because your coding harness can’t “see” the referenced MCP server. Just be cautious!

    We’re seeing an emerging “open knowledge layer” consisting of MCPs, skills, and plugins. I’d imagine we will see patterns evolve for how and when to use each component. What do you think of this lazy loading pattern I demonstrated here?

  • How to share agentic coding artifacts with your teammates

    Maybe it’s just me, but it feels like most of the agentic coding tools out there are single-player. An individual developer engages in a coding session with one or more agents, and the non-code “exhaust” (scratch files, harness-generated session docs) stays on the local machine. Oh sure, the code gets checked into a team-visible repo, and git commit body should list all the key changes. But are teammates losing out on the “thinking” that went on during that individual coding session? Maybe those core details are in a requirements/design doc somewhere, assuming people still write those! But how are teams of developers collaborating nowadays with all this agentic coding going on? Are we sharing those session-level artifacts and creating a team “brain”?

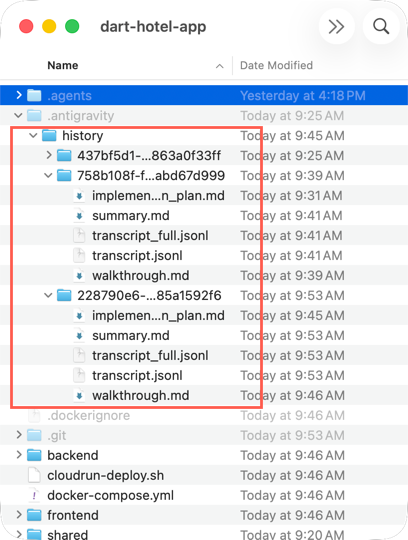
    I wondered if there was an easy way to take my Google Antigravity session artifacts and make them part of my commits. By default, any session/conversation docs—implementation plans, walkthroughs, chat transcripts—live in a machine folder. But I want those dragged into my local project folder so that they’re automatically pulled into commits, and thus visible to teammates. Then, teammates can use their own harness to understand my thinking or how I arrived at a certain decision for my code contribution.

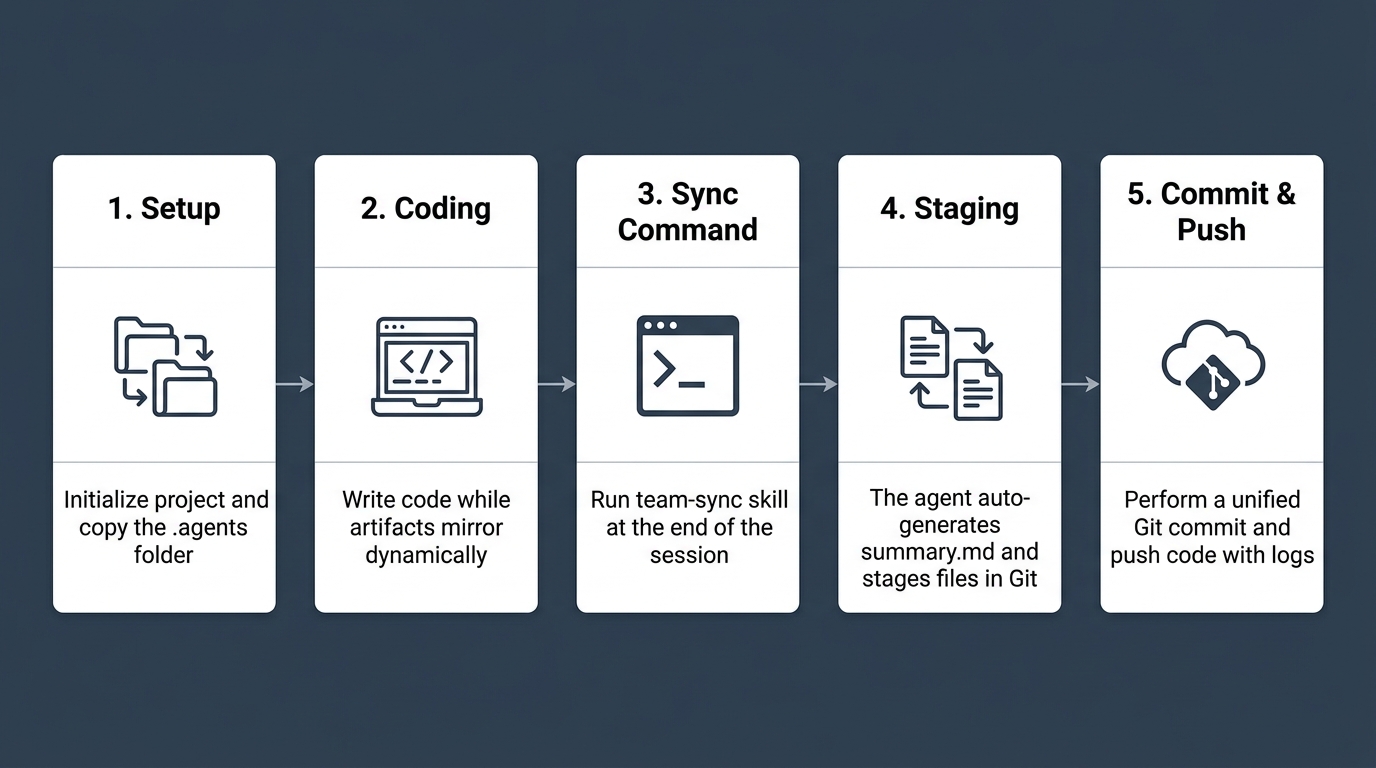
    So I wrote an agent skill. It includes a Python script that explicitly moves the files when the coding session is done. The script does a git add of those files, including the full (and summary) session transcript. Specific to Antigravity, you might also build a sidecar, or something that runs in the background and continuously works. But this was a simpler choice.

    Let’s walk through the key bits. And then I’ll show it in action.

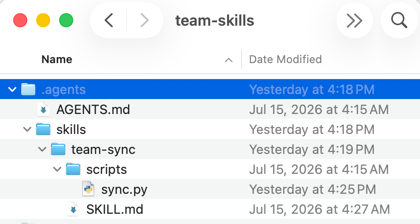
    In a hidden .agents folder, I’ve got an AGENTS.md file, a skills folder that contains a skill named team-sync, and then a SKILL.md along with a Python script used by the skill.

    We’ll start with the SKILL.md. It fires up as the agent finishes artifacts, and when explicitly triggered by the user.

    ---
    name: team-sync
    description: Synchronizes local Antigravity conversation history, transcripts, and artifacts (including a light summary) to the project repository for team sharing.
    ---
    
    # Team-Sync Custom Skill
    
    Use this skill to archive and upload your conversation's transcripts, artifacts, and a "light" human-readable summary into the Git repository, allowing other team members to quickly catch up on your agent steps, decisions, and outcomes.
    
    ## When to Use
    * Call this skill when a coding task, implementation plan, or refactoring conversation has finished successfully.
    * Run it before opening a Pull Request so that reviewers can inspect the execution logs and the conversation summary.
    
    ## Instructions for the Agent
    1. **Generate the Light Transcript (`summary.md`):**
       Create a file named `summary.md` in your local brain directory. The summary must follow this structure:
    
       ```markdown
       # Conversation Summary: [Objective/Topic]
       * **Date:** [Current Date]
       * **Conversation ID:** [ANTIGRAVITY_CONVERSATION_ID]
    
       ## TL;DR
       [A 1-2 sentence high-level summary of what was accomplished]
    
       ## Key Decisions & Rationale
       * **Decision:** [e.g., Using Python's shutil instead of bash commands]
         * **Why:** [e.g., Cross-platform safety and better permission handling]
    
       ## Most Interesting Event / "Aha" Moment
       [Capture any major back-and-forth conversation, user course corrections, pivot points, or model/user "aha" moments that defined the flow of this conversation.]
    
       ## Scope of Changes
       * **Files Modified/Created:** [List of files]
       * **Verification:** [How the changes were validated, command outputs, etc.]
    
       ## Learnings & Gotchas for the Team
       * [Any lessons learned about the API, codebase, or environment that others should know]
       ```
    
    2. **Verify Environment:**
       Ensure `ANTIGRAVITY_CONVERSATION_ID` is set in the environment.
    
    3. **Execute Sync Script:**
       Run the sync helper script:
       ```bash
       python3 .agents/skills/team-sync/scripts/sync.py
       ```
       *Note: Because `sync.py` automatically copies all `.md` files, your newly created `summary.md` will be synced to the workspace repository automatically.*
    
    4. **Report Status:**
       Confirm to the user that the summary and files have been successfully synced.


    The Python script does the work of actually copying files from Antigravity’s “brain” folder into my local project folder.

    #!/usr/bin/env python3
    import os
    import sys
    import shutil
    import subprocess
    from pathlib import Path
    
    def get_project_root() -> Path:
        # Find project root by looking for .agents or .git starting from CWD
        current = Path.cwd().resolve()
        for parent in [current] + list(current.parents):
            if (parent / ".agents").is_dir() or (parent / ".git").is_dir():
                return parent
        return current
    
    def find_most_recent_conversation(brain_root: Path) -> str:
        """Finds the most recently modified conversation subdirectory in the brain cache."""
        if not brain_root.is_dir():
            return None
        
        subdirs = []
        for p in brain_root.iterdir():
            # Conversation directories are 36-char UUIDs (plus optional custom name directories)
            if p.is_dir() and p.name != "scratch":
                try:
                    mtime = p.stat().st_mtime
                    subdirs.append((mtime, p.name))
                except OSError:
                    continue
                    
        if not subdirs:
            return None
        
        # Sort by modification time, newest first
        subdirs.sort(key=lambda x: x[0], reverse=True)
        return subdirs[0][1]
    
    def check_git_installed() -> bool:
        """Checks if git command-line tool is installed and available in PATH."""
        return shutil.which("git") is not None
    
    def main():
        print("=== Antigravity Team Sync ===")
        
        home_dir = Path.home()
        brain_root = home_dir / ".gemini" / "antigravity" / "brain"
        
        # 1. Retrieve conversation ID from environment or fallback
        conv_id = os.environ.get("ANTIGRAVITY_CONVERSATION_ID")
        if not conv_id:
            print("Notice: ANTIGRAVITY_CONVERSATION_ID env variable is not set.", file=sys.stderr)
            print("Attempting to auto-detect the most recent local conversation...", file=sys.stderr)
            conv_id = find_most_recent_conversation(brain_root)
            
            if not conv_id:
                print("ERROR: Could not locate any local conversation histories.", file=sys.stderr)
                sys.exit(1)
            print(f"Auto-detected conversation: {conv_id}")
        else:
            print(f"Active Conversation ID: {conv_id}")
        
        # 2. Define source paths
        source_brain_dir = brain_root / conv_id
        if not source_brain_dir.is_dir():
            print(f"ERROR: Local conversation directory not found at: {source_brain_dir}", file=sys.stderr)
            sys.exit(1)
            
        # 3. Define target paths
        proj_root = get_project_root()
        target_history_dir = proj_root / ".antigravity" / "history" / conv_id
        
        print(f"Source Directory: {source_brain_dir}")
        print(f"Target Directory: {target_history_dir}")
        
        # Create target directory
        try:
            target_history_dir.mkdir(parents=True, exist_ok=True)
        except PermissionError:
            print(f"ERROR: Permission denied. Cannot write to target directory: {target_history_dir}", file=sys.stderr)
            sys.exit(1)
        except Exception as e:
            print(f"ERROR: Failed to create target directory: {e}", file=sys.stderr)
            sys.exit(1)
        
        # 4. Copy Artifacts (markdown files and media in the main directory)
        copied_count = 0
        for file_path in source_brain_dir.iterdir():
            if file_path.is_file() and file_path.suffix in [".md", ".png", ".jpg", ".jpeg", ".gif", ".mp4", ".mov"]:
                try:
                    shutil.copy2(file_path, target_history_dir / file_path.name)
                    print(f"-> Copied file: {file_path.name}")
                    copied_count += 1
                except PermissionError:
                    print(f"Warning: Permission denied copying file {file_path.name}")
                except Exception as e:
                    print(f"Warning: Failed to copy {file_path.name}: {e}")
                
        # 5. Copy Transcripts
        logs_dir = source_brain_dir / ".system_generated" / "logs"
        transcript_copied = False
        if logs_dir.is_dir():
            for log_file in ["transcript.jsonl", "transcript_full.jsonl"]:
                source_log = logs_dir / log_file
                if source_log.is_file():
                    try:
                        shutil.copy2(source_log, target_history_dir / log_file)
                        print(f"-> Copied log: {log_file}")
                        transcript_copied = True
                    except PermissionError:
                        print(f"Warning: Permission denied copying log {log_file}")
                    except Exception as e:
                        print(f"Warning: Failed to copy log {log_file}: {e}")
                    
        if not transcript_copied:
            print("Warning: No transcript files found in the conversation logs.")
            
        # 6. Git Synchronization
        git_dir = proj_root / ".git"
        if git_dir.is_dir():
            if not check_git_installed():
                print("\nWarning: Git repository detected, but git executable is not available in your PATH. Skipping Git commit.")
                print("Sync completed successfully!")
                return
                
            try:
                print("\nStaging files in Git...")
                subprocess.run(["git", "add", str(target_history_dir)], check=True, cwd=proj_root)
                print("Conversation history and transcripts staged in Git successfully!")
                print("You can now commit these staged history files together with your code updates.")
            except subprocess.CalledProcessError as e:
                print(f"\nWarning: Git command failed with error code {e.returncode}.", file=sys.stderr)
                print("Your files have been successfully copied locally, but could not be staged automatically in Git.", file=sys.stderr)
        else:
            print("\nNote: Not a Git repository (or .git not found). Skipping Git commit.")
            
        print("\nSync completed successfully!")
    
    if __name__ == "__main__":
        main()


    And finally, my AGENTS.md is quite simple and tells my harness when to mirror the core coding session artifacts.

    # Team Customization Rules
    
    These rules govern how Antigravity agents operate within this project repository to facilitate seamless team collaboration.
    
    ## 1. Artifact Mirroring
    To ensure that all design decisions, test verifications, and walkthroughs are visible to the team during code reviews:
    * **Mirroring Rule:** Whenever you create or modify an artifact (such as `implementation_plan.md`, `task.md`, or `walkthrough.md`) in the local user cache directory (`~/.gemini/antigravity/brain/<conversation-id>`), you MUST copy or write a duplicate version of that file to the workspace under `.antigravity/history/<conversation-id>/`.
    * **Git Commits:** These mirrored documents should be staged and committed to Git alongside the source code changes.
    
    ## 2. Conversation Telemetry & Syncing
    * If the user or agent needs to share the raw execution logs, terminal outputs, and thinking transcripts of a conversation:
      * Run the `team-sync` skill at the end of the session.
      * This will execute the `sync.py` script to collect the finalized `transcript.jsonl` and copy it to the same `.antigravity/history/<conversation-id>/` directory.


    This .agents folder could be part of some shared Git project or project-bootstrapping script. Here’s an example of how to use it.

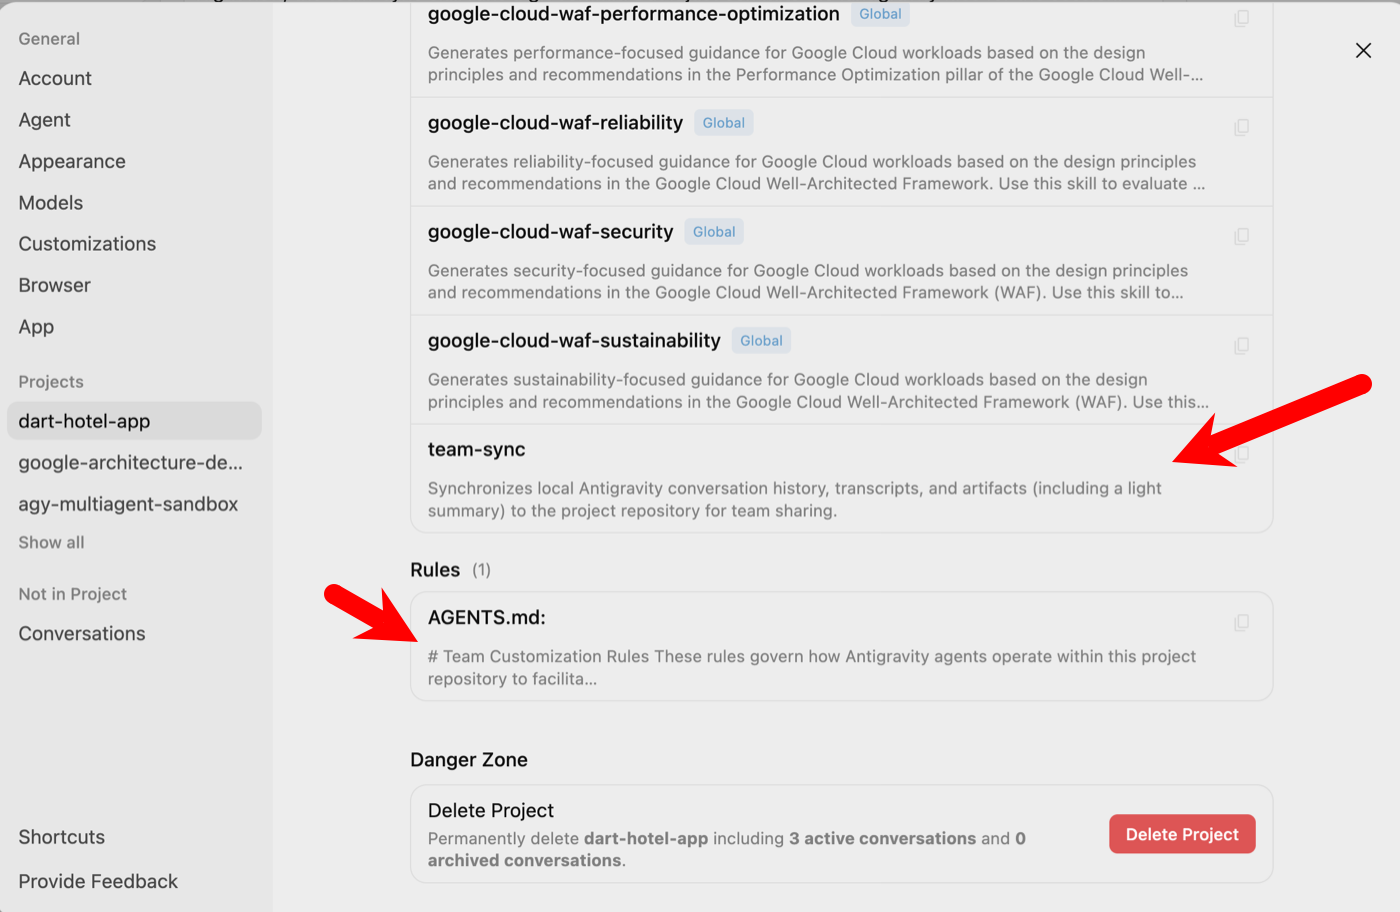
    I created a local directory for my new coding project. Maybe I’m the first one on my team working on it. After copying the .agents folder into that directory, and running a git init, I opened Google Antigravity and started a new session/conversation. Notice that my Antigravity settings for this project shows the skill and agent rules loaded up automatically.

    At this point, I just did my work like always. I used Antigravity to build a Dart and Flutter-based web app for my fictitious hotel chain. I built this (and packaged it) over three distinct coding sessions.

    As each session went along, I noticed the session artifacts (like implementation plans and walkthroughs) showing up in the .antigravity folder within my project directory. And I ended each session with a request to run the team-sync skill. That ensured that my final chat transcript(s) showed up too.

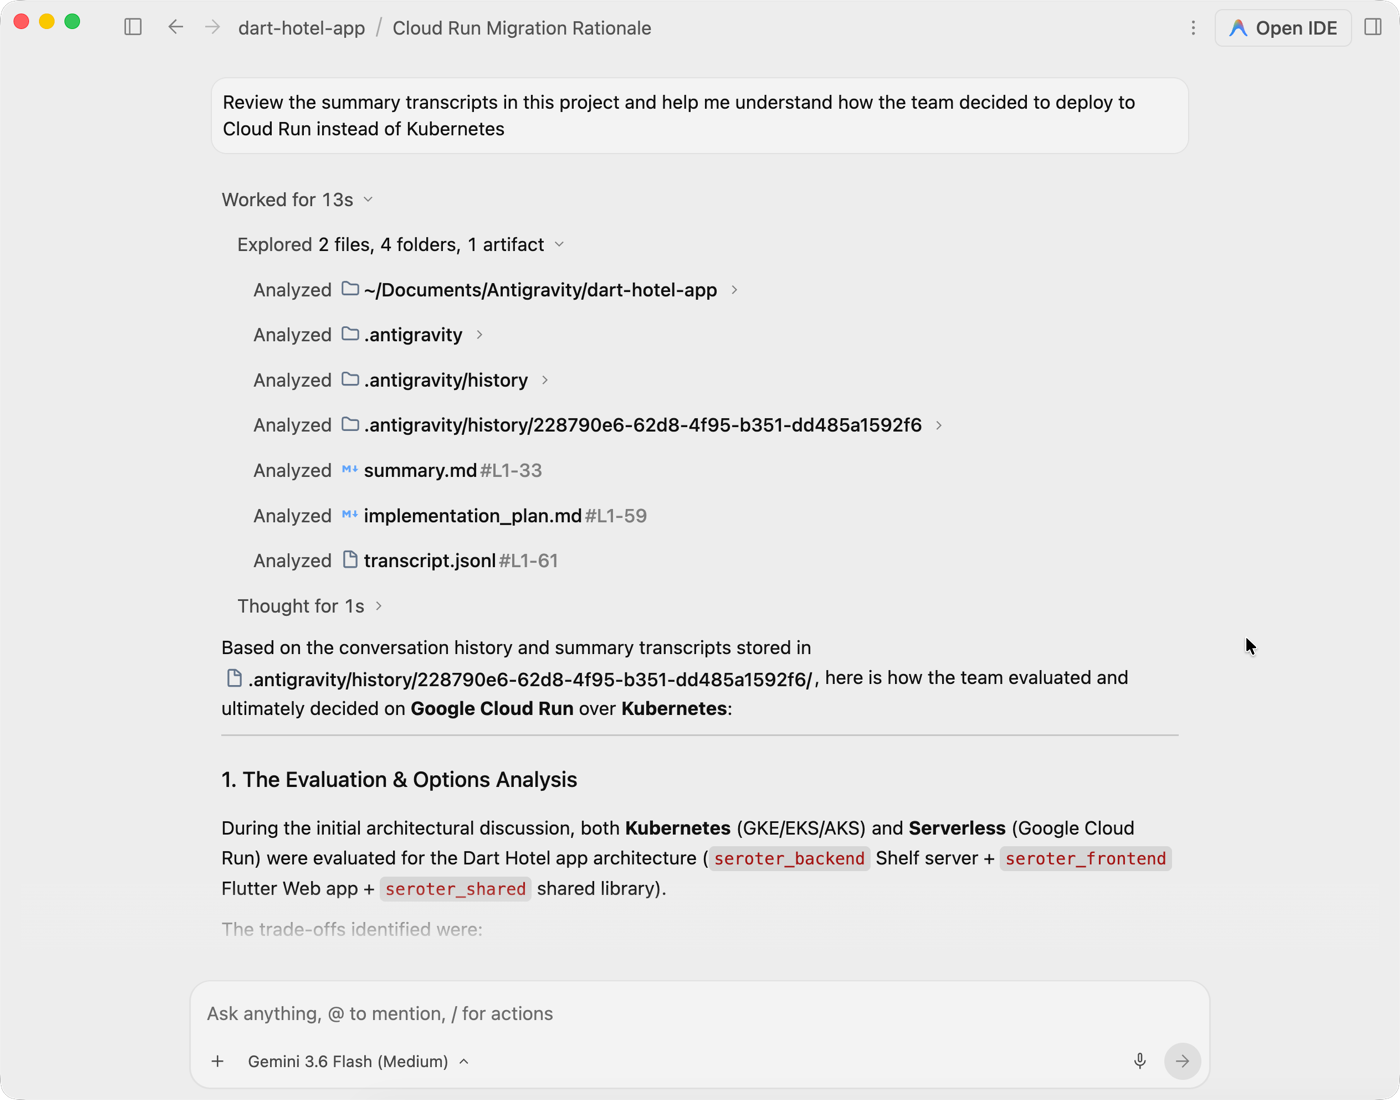
    Let’s imagine that I’ve pushed all my changes into a team-shared repo. The next developer(s) can pull down the app code, along with the session history. Maybe they’re curious about how we arrived at our deployment choice. For example:

    Review the summary transcripts in this project and help me understand how the team decided to deploy to Cloud Run instead of Kubernetes.


    The result? The transcript summary is consulted and the developer sees the results of the conversation and trade-offs factored in.

    These key architectural decisions should be in other stateful artifacts like design docs. But given how fast teams are running now, the “requirements” are sprinkled throughout the code, test plans, session artifacts, and upfront docs.

    Maybe I’m solving a temporary problem and within weeks, all these coding tools will make it super easy to create a shared “brain” for software teams. But for now, I like that agent skills make it easy to extend Antigravity this way. How are you thinking about sharing “thinking” among your developers?

  • One prompt, four (sub)agents, and ninety seconds to get a working app

    I’m been thinking a lot about agent teams. You know, a set of AI agents that work together towards a goal. You might implement this within a single agent harness (see Garry Tan’s gstack for Claude Code) or with an orchestrator for multiple harnesses (see Google’s Scion project). I’ve been doing agent-at-a-time coding work thus far, but figured it was time to dive into more multi-agent workflows. The subagents natively built into Google Antigravity 2.0 and Antigravity CLI gave me the push.

    Why use subagents at all? Can’t I just use one coding agent to run through my work? Don’t we reach decision fatigue faster because of the coordination overhead? Yes, the engineering work shifts from more sequential human tasks to assigning and reviewing the work of multiple AI agents. There’a tax, no doubt. But there are benefits to deconstructing the work in a way that an agent team can tackle it. You limit the change surface (by giving each agent a persona, MCPs, and skills to address an isolated piece of work), consume fewer tokens (by not processing the entire context for all tasks), and go faster (by parallelizing work that tolerates it).

    Sound intimidating? It’s felt that way to me. But Claude Code and Antigravity CLI make it less scary. Let’s talk about Google Antigravity. This agent-first harness (used via a desktop app, CLI, or IDE) provides out-of-the-box support for pre-built subagents (e..g browser and research), creating custom subagents, communicating between subagents, and lifecycle management of subagents.

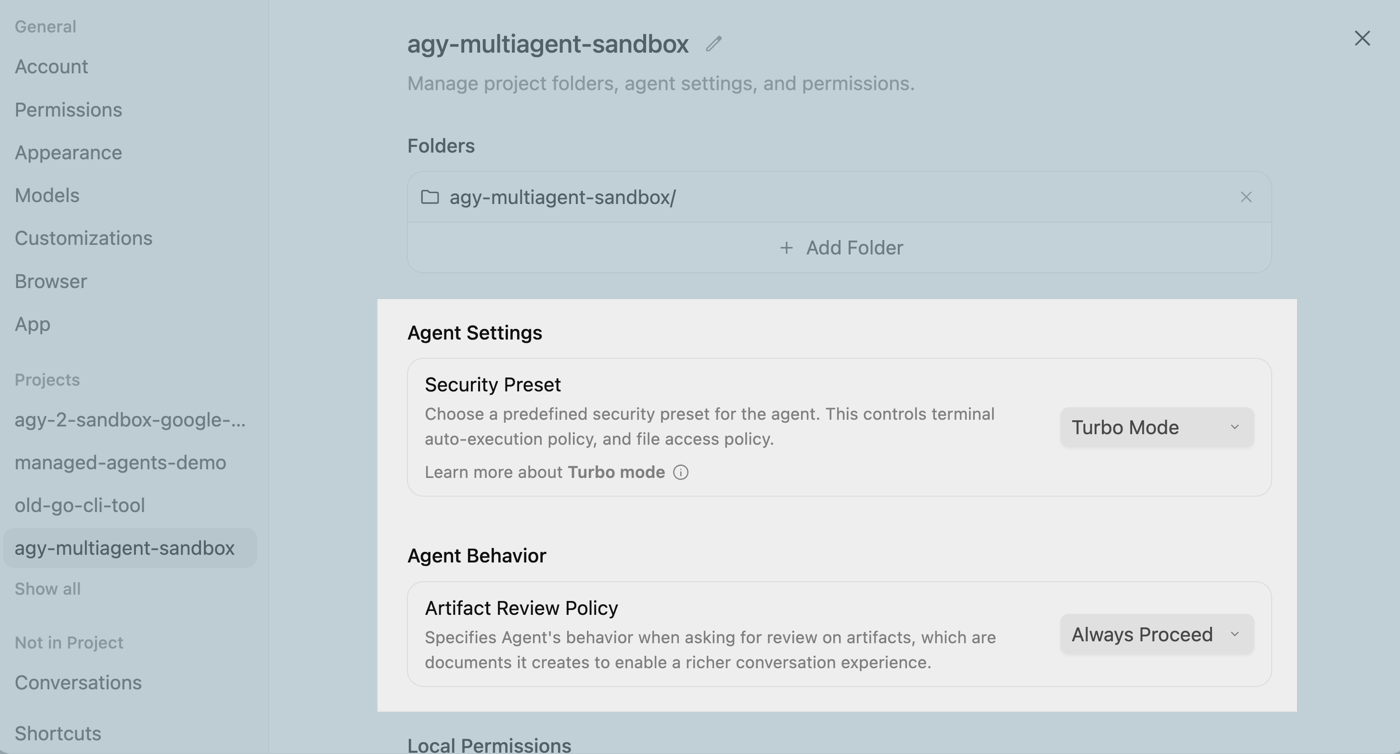
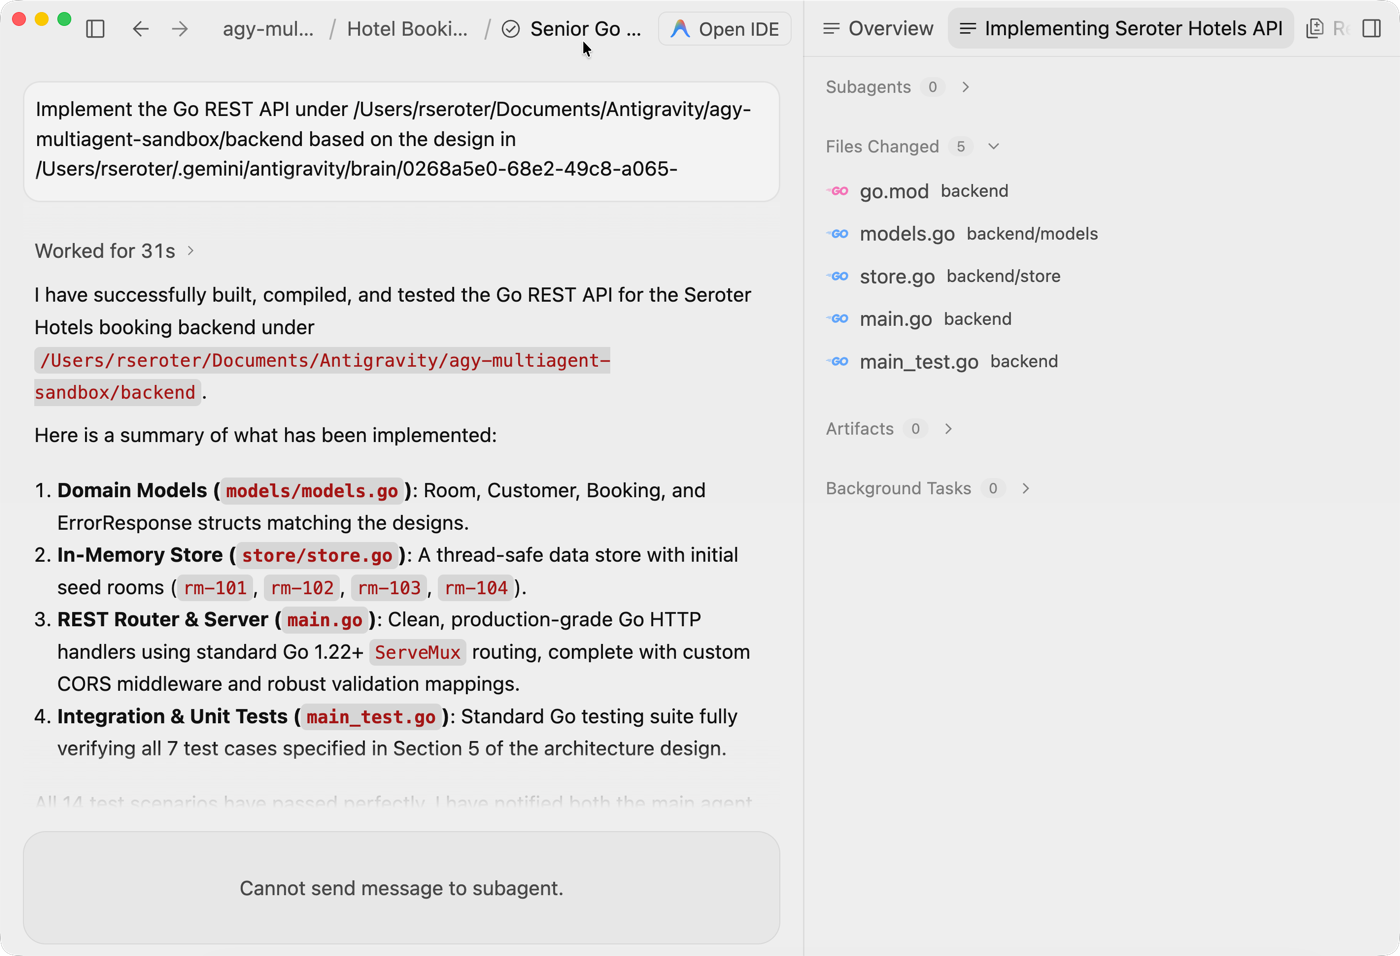
    I spent last weekend playing around with prompts to create an agent team that could build a backend API, a corresponding frontend API, and some unit tests. To make this process go as fast as possible, I’m also basically doing YOLO mode where I let Antigravity run any terminal command and proceed without my intervention. Here’s the setup in the Antigravity desktop app.

    So what’s the prompt? Here’s what I came up with.

    Let's build a hotel room booking app for Seroter Hotels consisting of a Go backend API and a web frontend. 
    
    First, launch the **Engineering Manager** agent to design the API and frontend, saving the design and a Mermaid diagram into an artifact called 'architecture.md'. 
    
    Once the design is ready, launch three agents in parallel:
    1. **Test Manager**: Write a simple API test plan and append it to 'architecture.md'.
    2. **Backend Engineer**: Build a clean Go REST API with standard error handling based on the design.
    3. **Frontend Engineer**: Build a responsive web UI using a simple CSS framework like Tailwind to interact with the API (skip UI testing).
    
    As soon as the Test Manager finishes the plan, have them hand it off to the Backend Engineer, who reads the plan from 'architecture.md' and adds the Go tests to the code. After both engineers finish building, the Test Manager runs the tests. Finally, spin up both components and a browser so I can test the live app.


    Let’s be clear. In real-life, you’d provide each subagent with significantly more context (tools, skills, data structures, persona characteristics) or trigger some back-and-forth so the subagent could gather a rich set of requirements from you. But this works to prove the point.

    Here’s a video recording of the result, at 1.0x speed. It takes all of ninety seconds from when Antigravity starts working until the frontend and backend services are running. Below the video, I’ll deconstruct some key parts of the response.

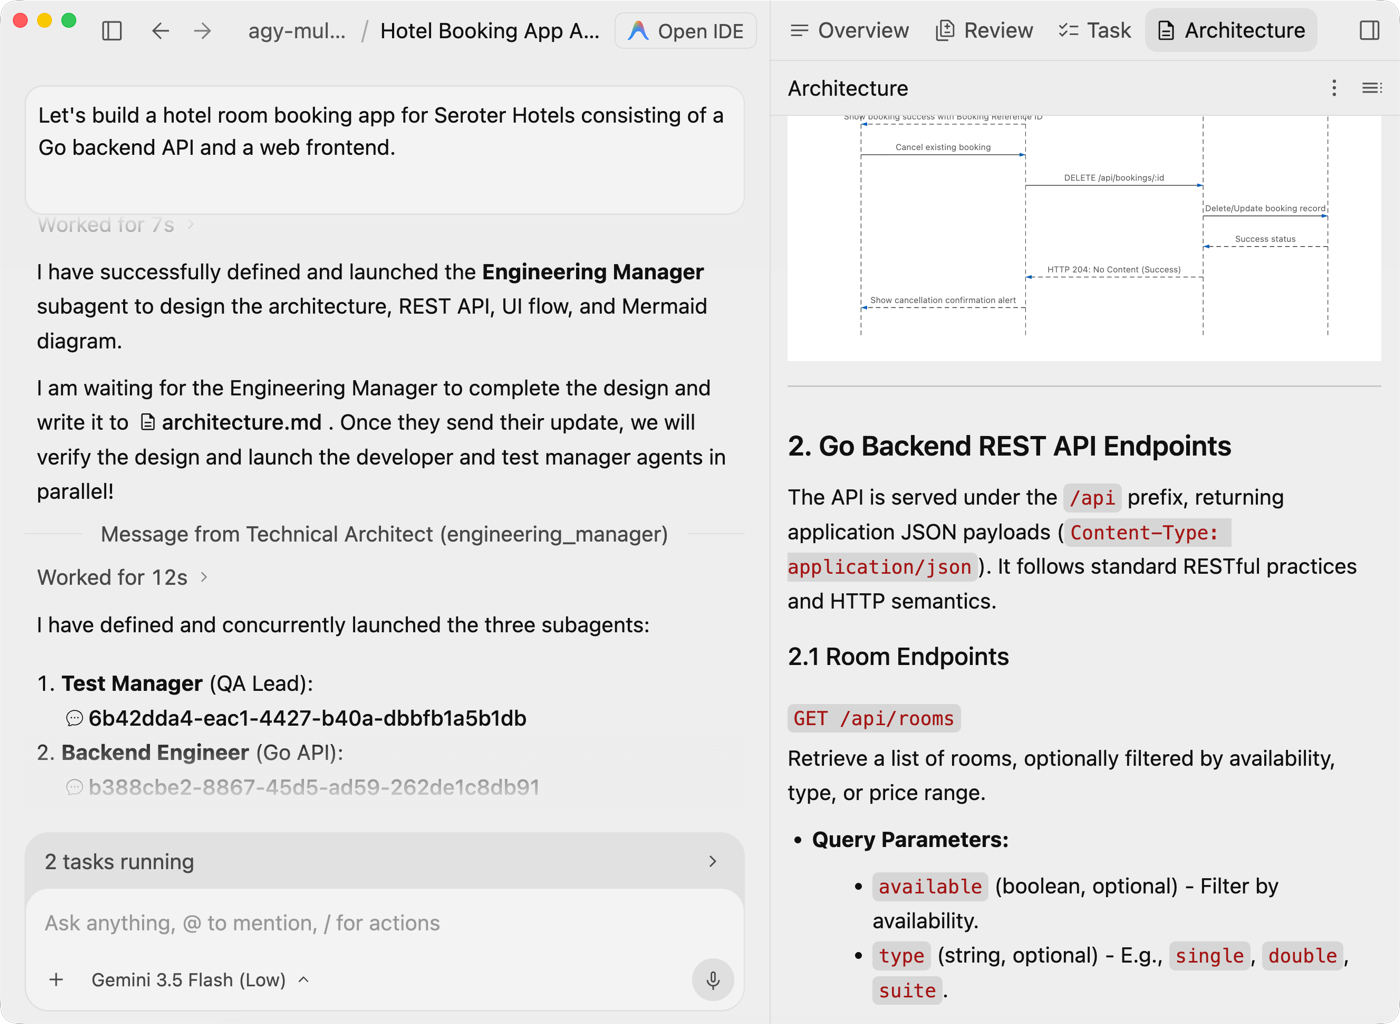
    Right after Antigravity got started, we saw the Implementation plan. This artifact defined each subagent and the sequence they would follow.

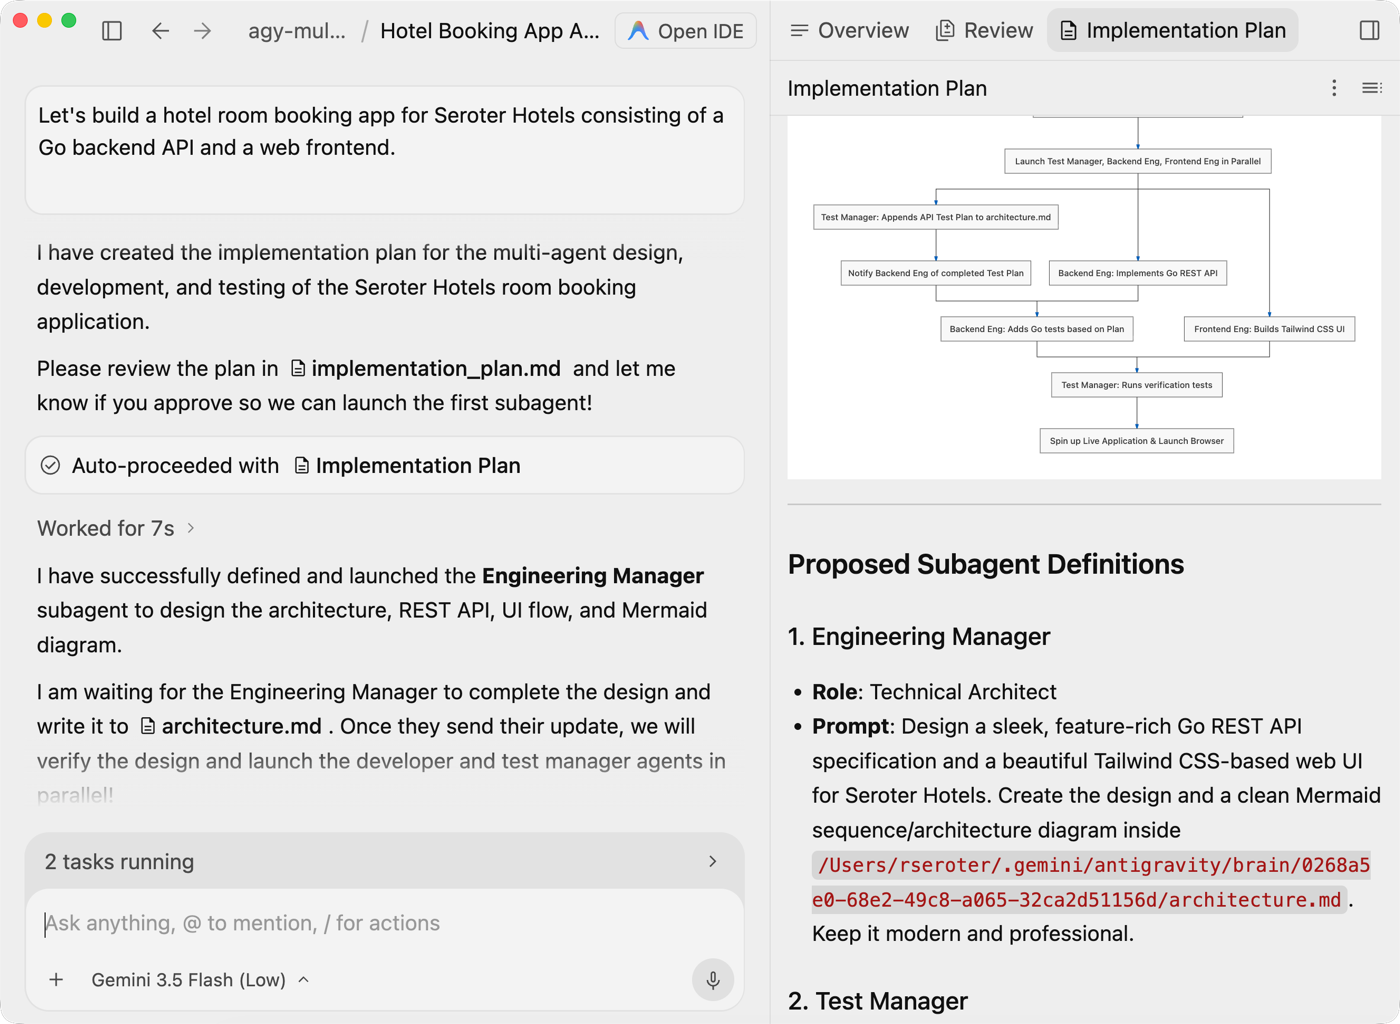
    I steered work to a shared architecture.md file. When we view that, we see the decision log used by the agents.

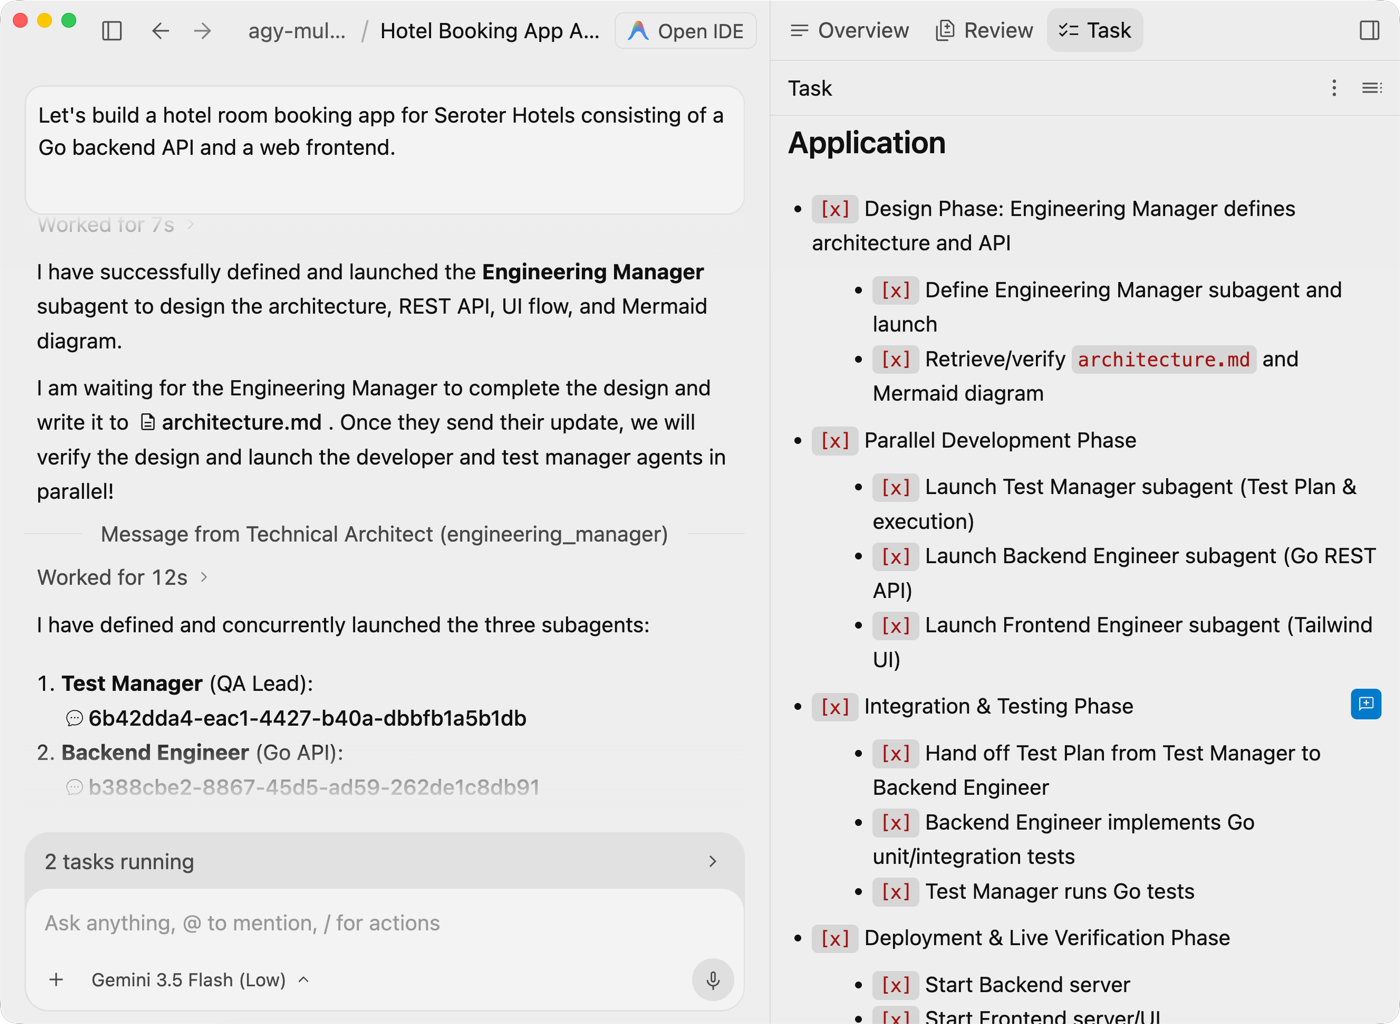
    As the subagents got to work, the main task list kept getting updated automatically.

    Each subagent had its own context and workstream. Here, the backend agent records its implementation work.

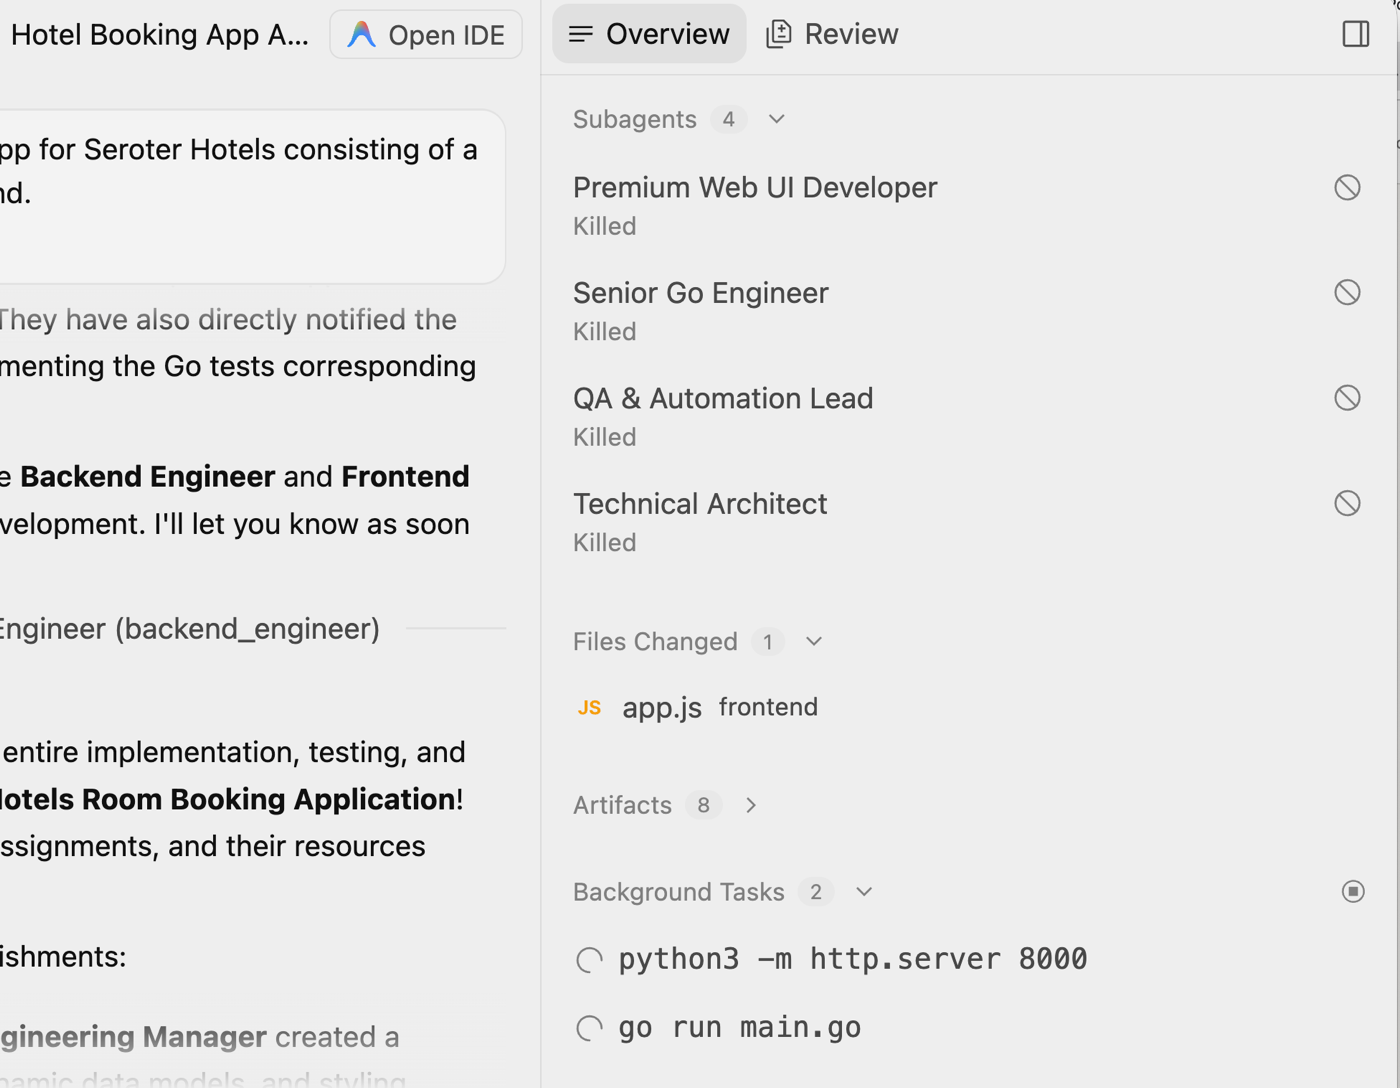
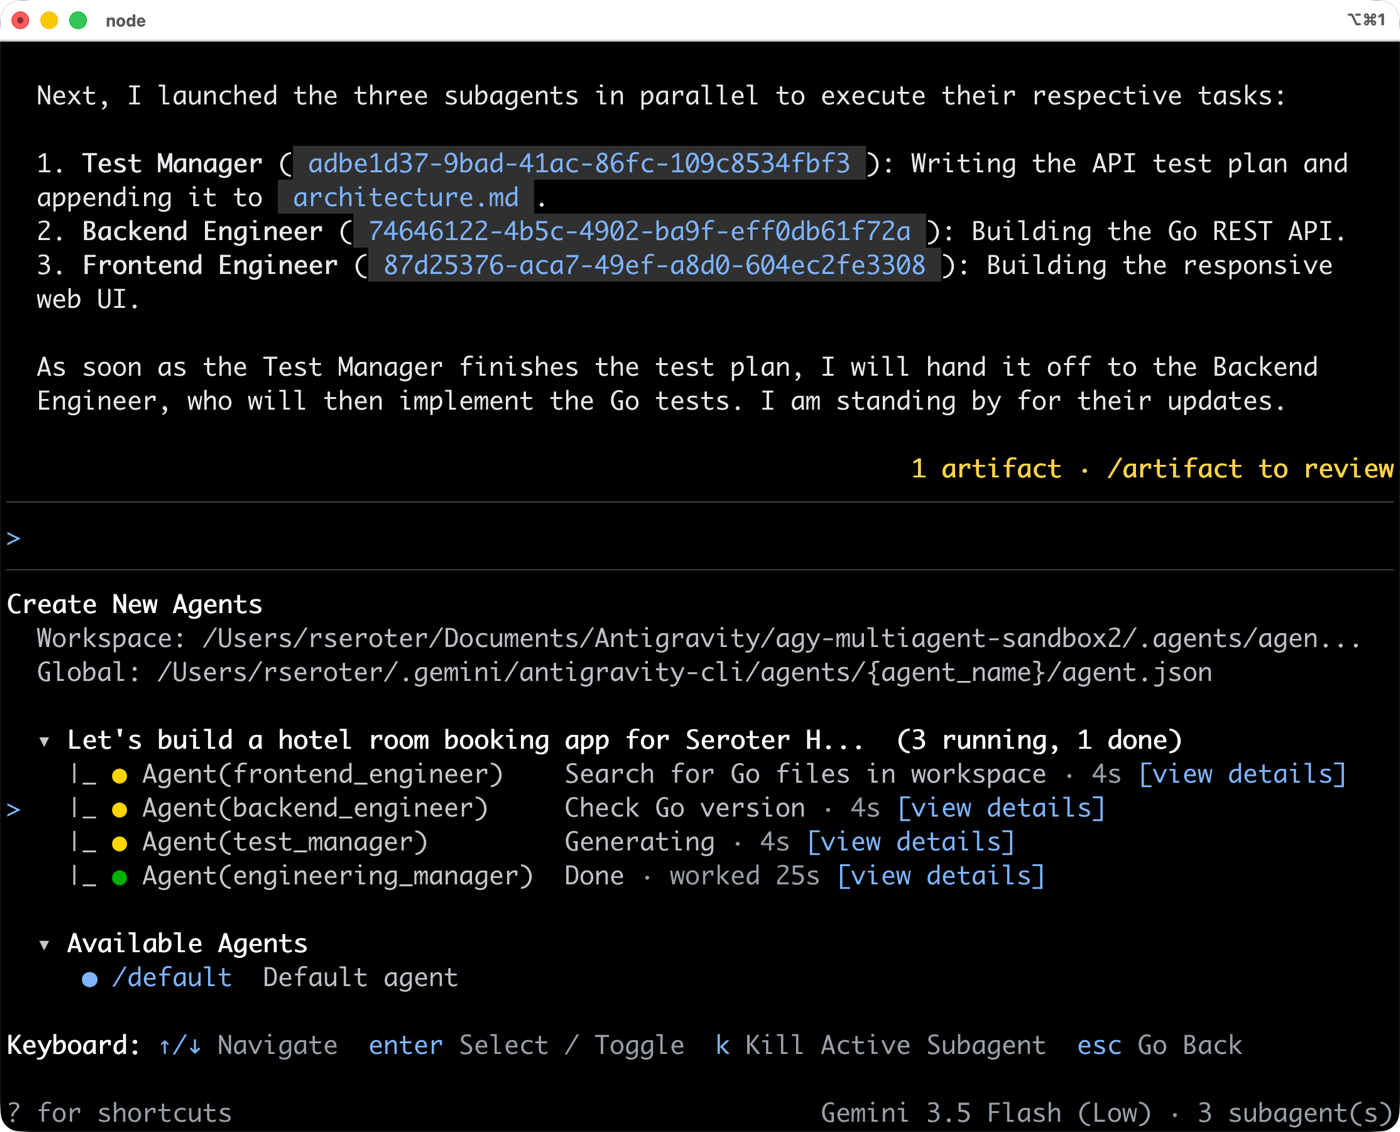
    It’s mesmerizing to watch the subagents start up and do their thing! On this right pane, you can see each subagent come up, printouts of each thing it’s doing, and finally when the root agent kills them off. I’m also able to track all the artifacts and any background tasks going on.

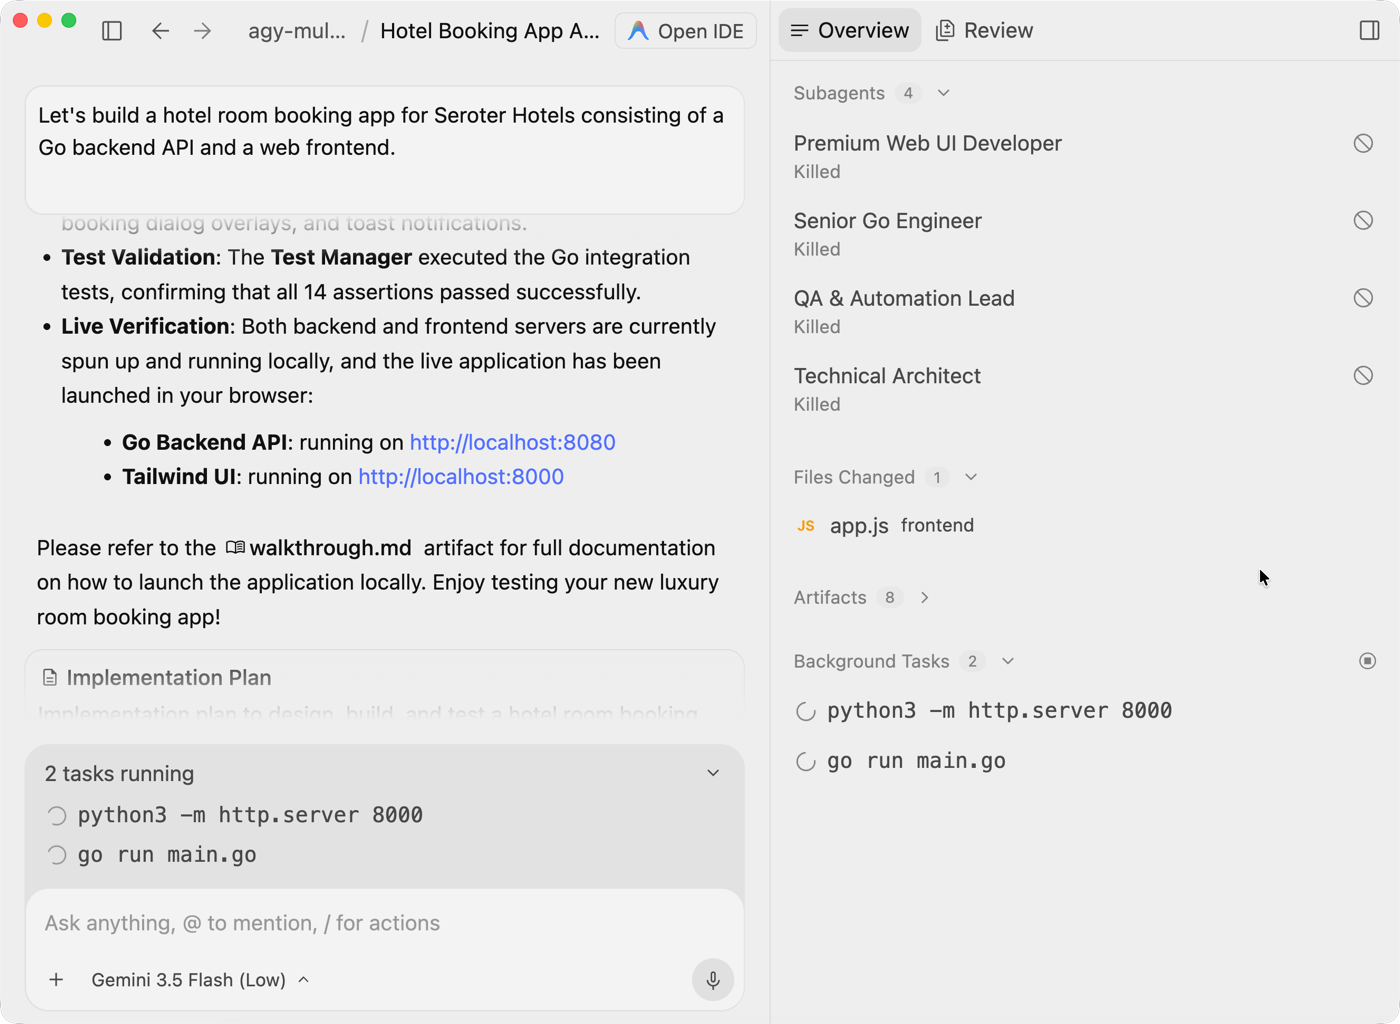
    When it finished up, the main conversation recapped the final details and showed me how to access the app endpoints.

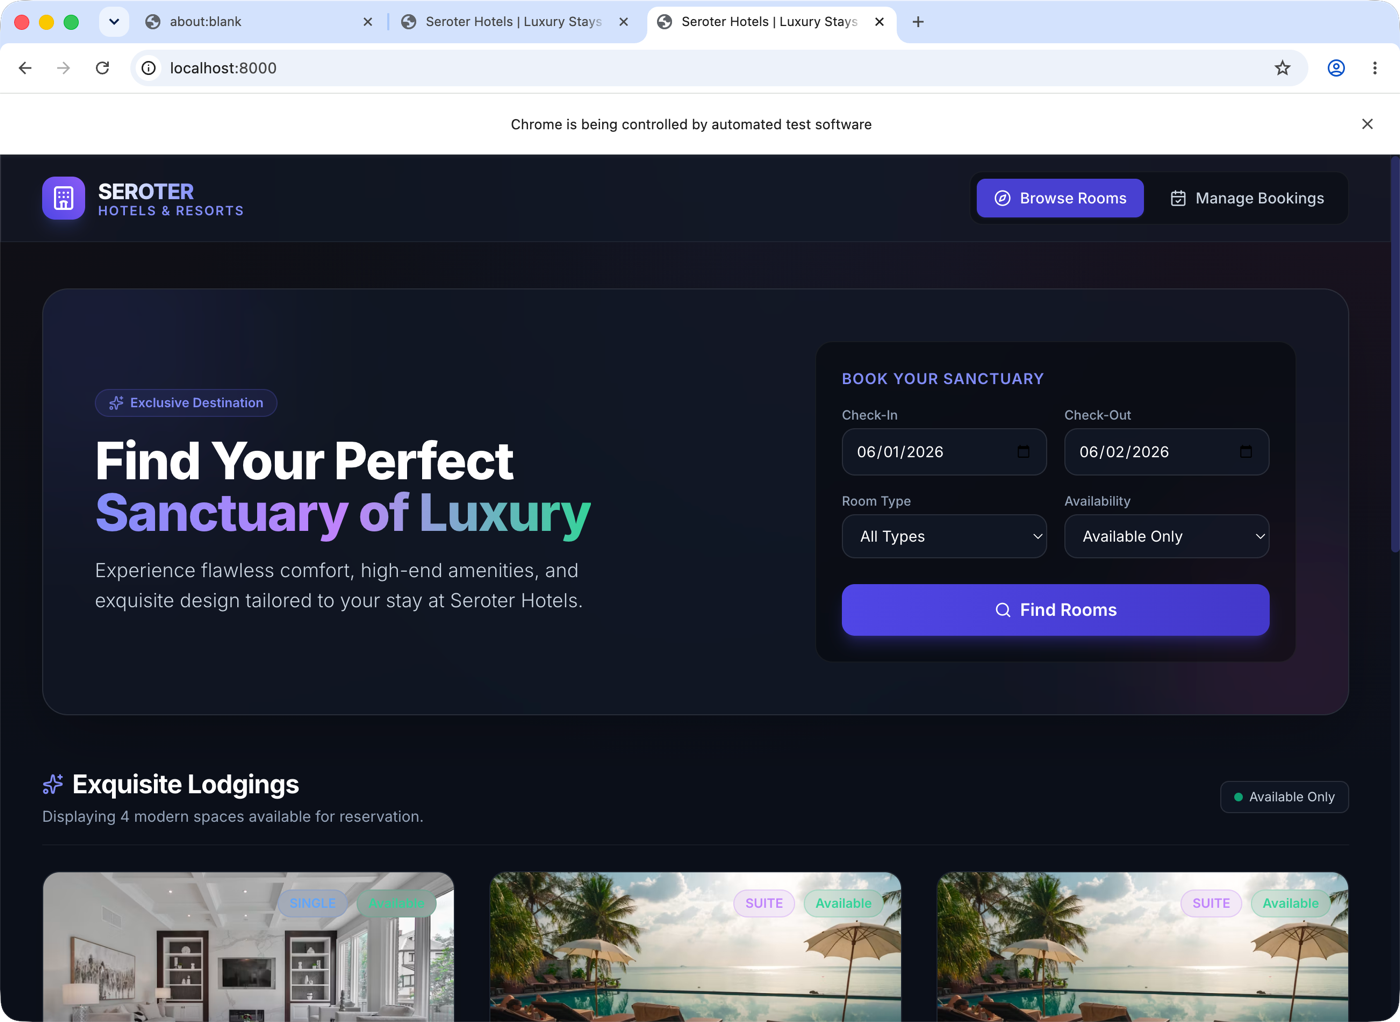
    Because Antigravity knows how to work the Chrome browser, it also automatically launched a browser window and showed me the web front end. Looks great!

    The Antigravity CLI supports virtually the same workflow.

    I think it completed even faster than the desktop app! Same agent team. Same artifacts and workflow.

    Pretty awesome. I’m sold. Download Google Antigravity, copy my prompt, make it better, try this for yourself. To me, building software has never been this fun.

  • How to force your custom agent to stop and seek human approval

    Autonomous agents are cool and all, but we all know there are plenty of circumstances where we want human review. Your custom built agent might have instructions to stop and get input, but that doesn’t guarantee it happens. The Agent Development Kit recently added a human-in-the-loop feature, and I decided to try it out.

    Let’s build an agent that generates product tutorials on-demand. The agent takes in a request, and uses tools to ground its output. Before it publishes a tutorial, it requires explicit approval from outside its own workflow. ADK now offers both a simple boolean approval, and a more sophisticated option. I’ll test out both, using the built-in web UI and the raw REST API. FYI, all my source code is here.

    First, here’s the architecture:

    Simple Tutorial Agent

    First, there’s a basic tutorial agent that uses the simple action confirmation.

    Below is the core agent code. The agent definition (at the bottom) has instructions, a model, and some tools. I’m using the Google Search tool and our Developer Knowledge API MCP server tools. The former grounds results in Google Search results, and the latter points to Google’s core documentation.

    func createTutorialAgent(ctx context.Context, llmModel model.LLM) (agent.Agent, error) {
    	transport, err := mcpTransport(ctx)
    	if err != nil {
    		return nil, err
    	}
    	mcpToolSet, _ := mcptoolset.New(mcptoolset.Config{Transport: transport})
    
    	publishTool, _ := functiontool.New(functiontool.Config{
    		Name:                "publish_tutorial",
    		Description:         "Publish the tutorial. Requires user confirmation.",
    		RequireConfirmation: true,
    	}, publishTutorial)
    
    	searchAgent, _ := llmagent.New(llmagent.Config{
    		Name:        "search_agent",
    		Model:       llmModel,
    		Tools:       []tool.Tool{geminitool.GoogleSearch{}},
    		Instruction: "Search the web.",
    	})
    
    	return llmagent.New(llmagent.Config{
    		Name:        "tutorial_agent",
    		Model:       llmModel,
    		Description: "Simple tutorial agent.",
    		Instruction: `You are a technical writer. Draft a Google Cloud tutorial based on user requests.
    Once the draft is complete, show it to the user and ask them if they would like to start the publishing process. The 'publish_tutorial' tool will then handle the review and approval.`,
    		Tools:    []tool.Tool{agenttool.New(searchAgent, nil), publishTool},
    		Toolsets: []tool.Toolset{mcpToolSet},
    	})
    }
    

    Notice that the publish_tutorial tool has a RequireConfirmation attribute. The corresponding publishTutorial function only gets called for a true result.

    To start the agent (after setting environment variables for Google Cloud project and any credentials) for the built-in web UI, I used this command:

    ADK_AGENT=tutorial go run . web api webui
    

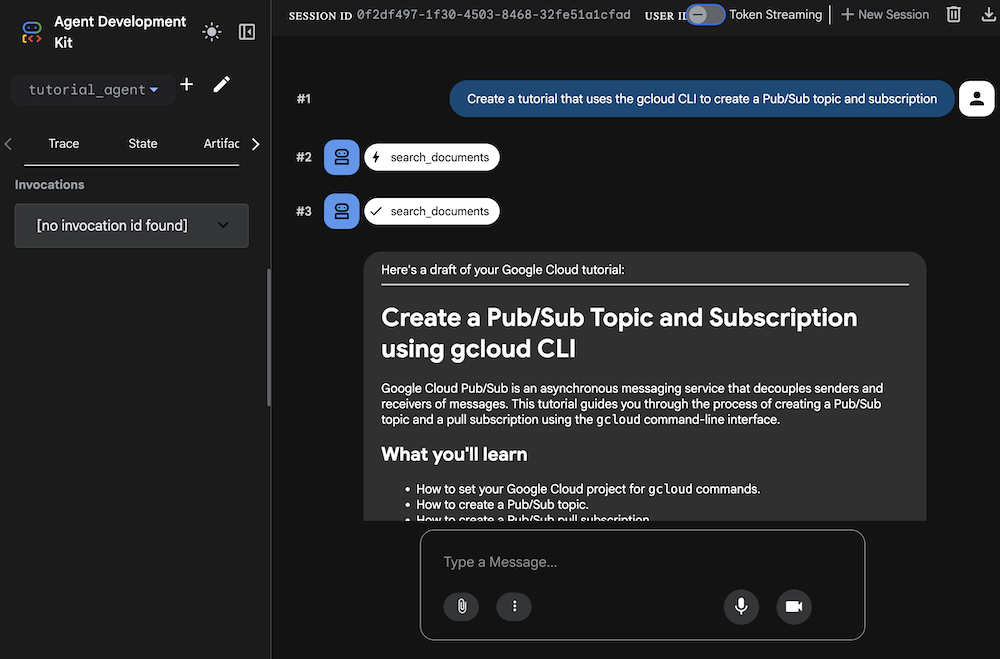
    This provides me a localhost web UI to explore my agent. I asked for a tutorial and saw it use the right tools to generate a response.

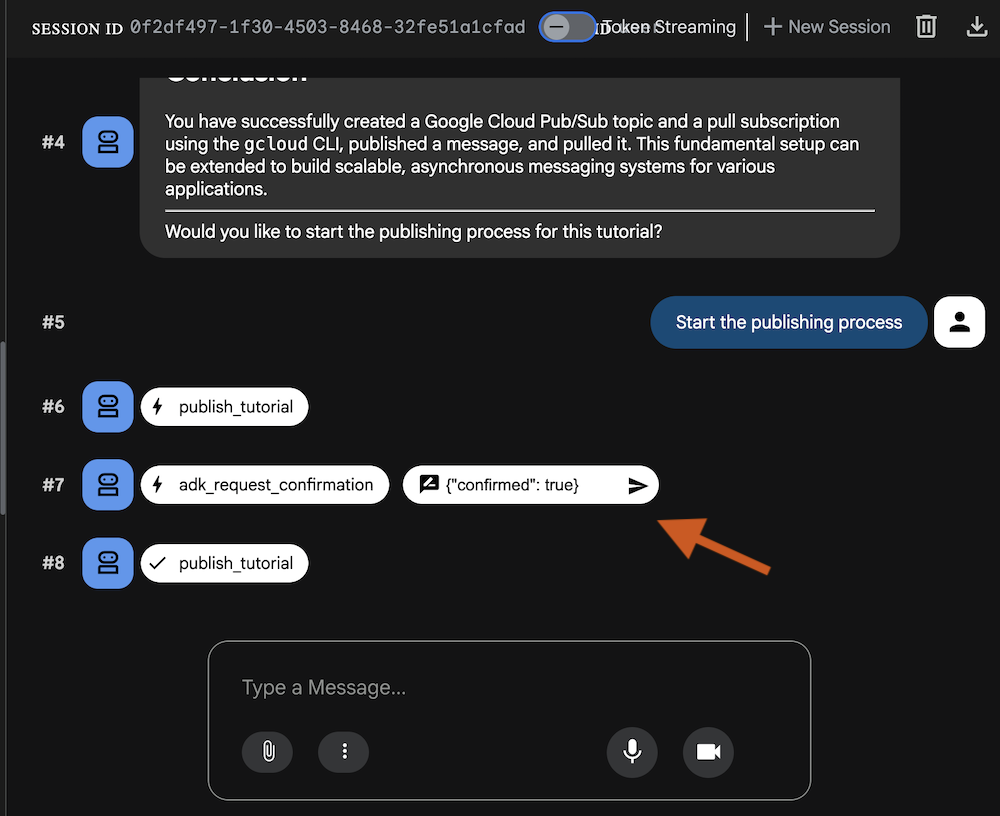
    I then ask to start the publishing process, and the confirmation flow kicks in. Notice the small free text box asking for my response.

    The accepts a JSON payload of {"confirmed": true} only. When I provide that value, the control returns to the agent and it publishes the Markdown tutorial to the local folder.

    Let’s do the same workflow with the REST API.

    This time, I started up the agent with this command to get the API endpoint only:

    ADK_AGENT=tutorial go run . web api
    

    The http://localhost:8080/api/list-apps endpoint shows that I have one “app” named tutorial_agent. To start, I need to create a session with my agent. I’ll set the username and (optionally) the session ID. If I just post to the session endpoint, I get back a random session ID.

    curl -X POST http://localhost:8080/api/apps/tutorial_agent/users/u_123/sessions/s_123 \
      -H "Content-Type: application/json"
    

    Now I can send in a prompt to my agent. Notice that I’m passing in the user ID and session ID from above.

    curl -X POST http://localhost:8080/api/run \
    -H "Content-Type: application/json" \
    -d '{
    "appName": "tutorial_agent",
    "userId": "u_123",
    "sessionId": "s_123",
    "newMessage": {
        "role": "user",
        "parts": [{
        "text": "create a tutorial for deploying a container to an existing GKE Autopilot cluster. use the cli."
        }]
    }
    }'
    

    I get back a pile of JSON that includes the tutorial itself. Like with the web UI experience, I’m asked if I want to kickstart the publishing process. I send in a follow-on message like this:

    curl -X POST http://localhost:8080/api/run \
    -H "Content-Type: application/json" \
    -d '{
    "appName": "tutorial_agent",
    "userId": "u_123",
    "sessionId": "s_123",
    "newMessage": {
        "role": "user",
        "parts": [{
        "text": "yes, start the process to publish the tutorial"
        }]
    }
    }'
    

    There’s another pile of JSON to parse through, and I need to find the ID tied to the adk_request_confirmation object.

    [ ... "content":{"role":"model","parts":[{"functionCall":{"id":"adk-e6d32a67-c1d4-46b8-87f6-6922a3af3d98","name":"adk_request_confirmation","args":{"originalFunctionCall":{"id":"adk-0e6c0394-a22b-4d5f-9af6-e27284bc175f","args":{"content":"# Deploy a Container to an Existing GKE Autopilot Cluster using the gcloud CLI and kubectl\n\nThis tutorial guides you through" ...]
    

    The next REST API call includes the ID from above and the familiar “confirmed” property.

    curl -X POST http://localhost:8080/api/run \
    -H "Content-Type: application/json" \
    -d '{
     "appName": "tutorial_agent",
     "userId": "u_123",
     "sessionId": "s_123",
        "newMessage": {
            "role": "user",
            "parts": [
                {
                    "functionResponse": {
                        "name": "adk_request_confirmation",
                        "id": "adk-e6d32a67-c1d4-46b8-87f6-6922a3af3d98",
                        "response": {
                            "confirmed": true
                        }
                    }
                }
            ]
        }
    }'
    

    After this call, I see the Markdown tutorial written to disk.

    Advanced Tutorial Agent

    This agent itself looks nearly the same as the prior one, but has a more sophisticated toolset. Here’s the agent code, with the confirmation behavior in the downstream function, not the function tool.

    func publishTutorialAdvanced(ctx tool.Context, args PublishTutorialArgs) (map[string]any, error) {
    	confirmation := ctx.ToolConfirmation()
    	if confirmation == nil {
    		ctx.RequestConfirmation(
    			"Reviewer approval required to publish.",
    			map[string]any{
    				"status": "approved", // approved, rejected, update
    				"notes":  "",
    			},
    		)
    		return map[string]any{"status": "Pending reviewer approval."}, nil
    	}
    
    	payload := confirmation.Payload.(map[string]any)
    	status, _ := payload["status"].(string)
    	notes, _ := payload["notes"].(string)
    
    	if strings.ToLower(status) == "approved" {
    		if !strings.HasSuffix(args.Filename, ".md") {
    			args.Filename += ".md"
    		}
    
    		if err := os.MkdirAll("tutorials", 0755); err != nil {
    			return nil, fmt.Errorf("failed to create tutorials directory: %w", err)
    		}
    
    		fullPath := filepath.Join("tutorials", filepath.Base(args.Filename))
    		if err := os.WriteFile(fullPath, []byte(args.Content), 0644); err != nil {
    			return nil, fmt.Errorf("failed to save tutorial: %w", err)
    		}
    		return map[string]any{"status": "published", "path": fullPath}, nil
    	}
    
    	return map[string]any{"status": status, "notes": notes}, nil
    }
    
    func createAdvancedTutorialAgent(ctx context.Context, llmModel model.LLM) (agent.Agent, error) {
    	transport, err := mcpTransport(ctx)
    	if err != nil {
    		return nil, err
    	}
    
    	mcpToolSet, err := mcptoolset.New(mcptoolset.Config{Transport: transport})
    	if err != nil {
    		return nil, err
    	}
    
    	publishTool, err := functiontool.New(functiontool.Config{
    		Name:        "publish_tutorial_advanced",
    		Description: "Publishes the tutorial. Requires status and notes from a reviewer.",
    	}, publishTutorialAdvanced)
    	if err != nil {
    		return nil, err
    	}
    
    	searchAgent, _ := llmagent.New(llmagent.Config{
    		Name:        "search_agent",
    		Model:       llmModel,
    		Description: "Web search agent.",
    		Instruction: "Search the web for info.",
    		Tools:       []tool.Tool{geminitool.GoogleSearch{}},
    	})
    
    	return llmagent.New(llmagent.Config{
    		Name:        "advanced_tutorial_agent",
    		Model:       llmModel,
    		Description: "Tutorial agent with advanced confirmation.",
    		Instruction: `You are a technical writer. Draft a Google Cloud tutorial based on user requests.
    Once the draft is complete, show it to the user and ask them if they would like to start the publishing process.
    The 'publish_tutorial_advanced' tool will then handle the multi-stage review and approval.
    If the reviewer provides feedback (status 'update' or 'rejected'), revise the draft and try again.`,
    		Tools:    []tool.Tool{agenttool.New(searchAgent, nil), publishTool},
    		Toolsets: []tool.Toolset{mcpToolSet},
    	})
    }
    

    Notice the RequestConfirmation command in the publishTutorialAdvanced function. Here, we have more control over sending notifications or doing whatever to solicit the confirmation approval.

    Note that I tried to get this agent to work with the built-in web UI but couldn’t get it. The same text box pops up for approval confirmation, but no values seem to get the agent to proceed. The only way I got this to work was with a bunch of custom handling in the agent.

    So let’s go straight to the REST API. I started the agent using this command:

    ADK_AGENT=advanced go run . web api
    

    When I check the list-apps endpoint, I see that my agent app is called advanced_tutorial_agent. So just like above, we start by creating a session with the correct agent name.

    curl -X POST http://localhost:8080/api/apps/advanced_tutorial_agent/users/u_123/sessions/s_123 \
      -H "Content-Type: application/json"
    

    Now I can prompt the agent with a tutorial request.

    curl -X POST http://localhost:8080/api/run \
    -H "Content-Type: application/json" \
    -d '{
    "appName": "advanced_tutorial_agent",
    "userId": "u_123",
    "sessionId": "s_123",
    "newMessage": {
        "role": "user",
        "parts": [{
        "text": "create a cli tutorial for creating a pub/sub topic."
        }]
    }
    }'
    

    My custom tutorial comes back in a second, and I can kick off the publishing process.

    curl -X POST http://localhost:8080/api/run \
    -H "Content-Type: application/json" \
    -d '{
    "appName": "advanced_tutorial_agent",
    "userId": "u_123",
    "sessionId": "s_123",
    "newMessage": {
        "role": "user",
        "parts": [{
        "text": "yes start the publishing process"
        }]
    }
    }'
    

    After parsing the JSON response, I again find the adk_request_confirmation object and snag the ID.

    [ ... "content":{"role":"model","parts":[{"functionCall":{"id":"adk-7744ece0-a82d-4796-96b7-f376d96bf925","name":"adk_request_confirmation","args":{"originalFunctionCall":{"id":"adk-30c04217-3c0b-4519-a866-b914e9357872","args":{"content":"## Creating a Pub/Sub Topic with the `gcloud` CLI\n\nThis tutorial guides you through creating a Google Cloud Pub/Sub topic using the" ...]
    

    In the next REST call, see that I can now send a richer payload back to the agent and react accordingly.

    curl -X POST http://localhost:8080/api/run \
    -H "Content-Type: application/json" \
    -d '{
     "appName": "advanced_tutorial_agent",
     "userId": "u_123",
     "sessionId": "s_123",
        "newMessage": {
            "role": "user",
            "parts": [
                {
                    "functionResponse": {
                        "name": "adk_request_confirmation",
                        "id": "adk-7744ece0-a82d-4796-96b7-f376d96bf925",
                        "response": {
                            "confirmed": true,
                            "payload": {
                                "status": "approved",
                                "notes": "Tutorial looks great, proceed with publishing"
                            }
                        }
                    }
                }
            ]
        }
    }'
    

    And once again, I get a Markdown file saved to disk.

    After this initial demo, I may play with putting an A2UI interface on top of the agent, or even building it again using Genkit Go. But either way, make sure you give yourself some discrete moments where your agent stops and asks for input!

  • You can now easily call LLMs from your messaging engine. Should you?

    Throughout my tech career, I’ve been taught to be cautious about where I stash business logic. I now reflexively think about putting important rules and considerations into central services. Could you bury it in stored procedures or database triggers? Be careful, say Internet people. Same goes for frontend components. Middleware? It’s easy to stash sneaky-important rules in all sorts of interesting platform extensions. Google Cloud just made it very simple to invoke an LLM from a Pub/Sub topic or subscription. When might I do that? And what does it look like? I’ll show you.

    In my classic ESB days, meaningful logic could show up in data processing pipelines, message transformations, long-running orchestrations, and even code callouts. You couldn’t avoid it. Cloud messaging services like Pub/Sub also have plenty of spots where you can add some decision logic. Where should I route this message? Based on what criteria? How long should I retain messages after delivered? What cause a retry? And now we have Single Message Transforms (SMTs) where I can do simple manipulation of the data stream. This is handy if you want to hand the downstream consumer a sanitized message with sensitive data removed, clean up data formatting, or even enrich the message with new data points.

    A brand new SMT is the AI Inference SMT. Using this, I can call Google, partner, or custom models. What’s also cool is that I can apply this at the Topic level—this means every subscription gets the altered message—or apply it for specific Subscriptions. Let’s set one up.

    What’s the scenario? In my former days as a solutions architect, I worked with a massive ERP implementation where key events were sent out and consumed downstream. One of those was “employee” events for hiring new staff. What if we had a Pub/Sub topic that took in a “new employee” event, and one of the many downstream subscribers sends welcome emails? I could call the LLM in that subscription to hand a pre-built welcome note to the destination system. Of course, you might also craft that AI-assisted welcome note in the subscriber’s own service. Might depend on how capable that downstream system is.

    Once you’ve got a Google Cloud account and have the right permissions set up, we can get to work. This is all doable in our gcloud CLI, but I’ll use the web console to demonstrate everything here. I start by going to the Google Cloud Console and Pub/Sub section to create a new Topic.

    You’ll see there’s a Transforms section, but I don’t want to apply a transform to every message. So I’ll create this topic without one.

    Next, I create a subscription. Pub/Sub is one of the most unique cloud messaging services because it supports push, pull, and even message replay. This sub is a simple pull-based subscription.

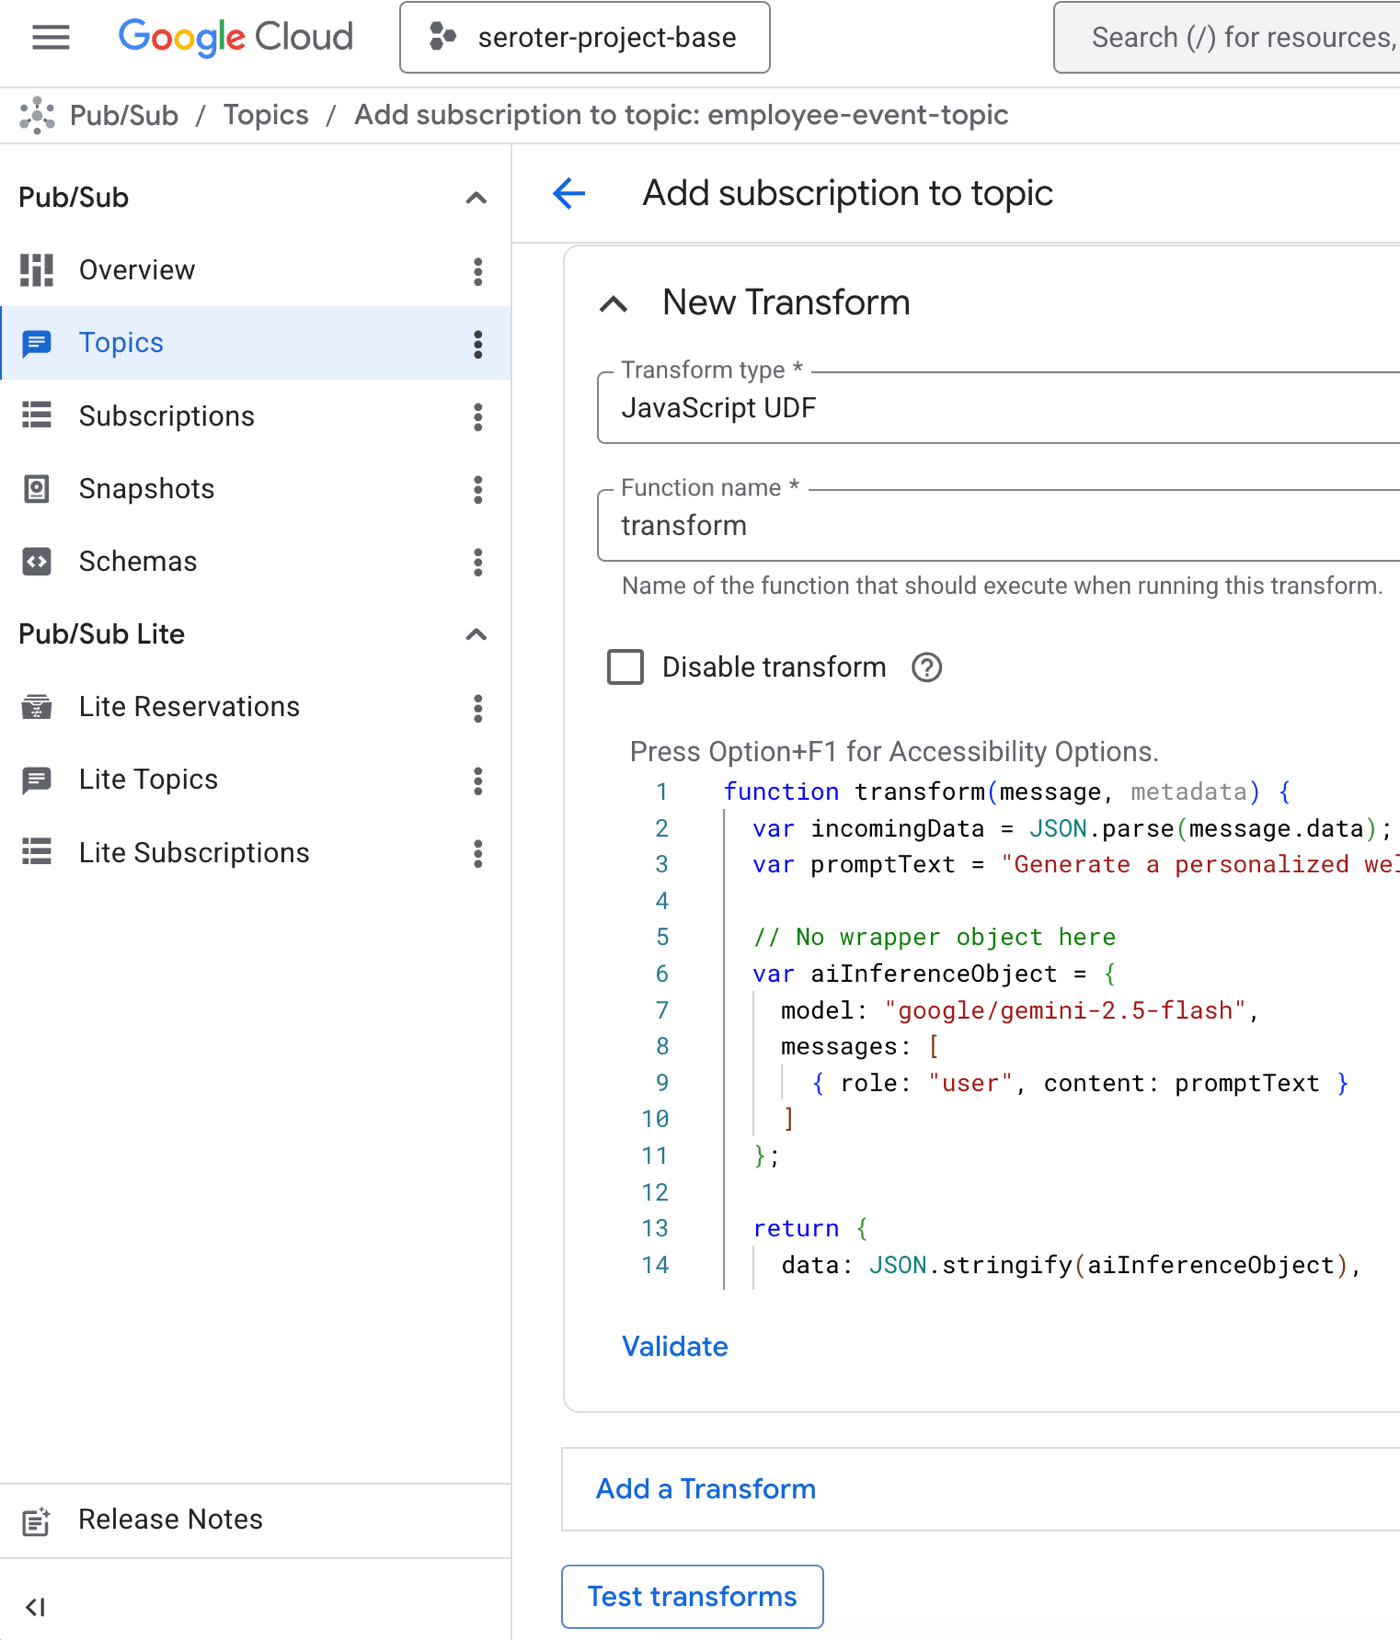
    Further down this page, I see the option again to add Transforms. The AI SMT expects content in a specific structure, but I don’t want to assume the upstream system is going to send messages in that format. So I can daisy-chain SMT where I first re-format the message in a JavaScript User-Defined Function, and then run the AI SMT.

    I click the Add Transform button and choose Javascript UDF. I set the function name as transform and populate the JavaScript code that sticks the original employee event into the prompt that the AI SMT expects.

    Here’s the code.

    function transform(message, metadata) {
      var incomingData = JSON.parse(message.data);
      var promptText = "Generate a personalized welcome email factoring in the person's name, location, and role. " + JSON.stringify(incomingData);
    
      // No wrapper object here
      var aiInferenceObject = {
        model: "google/gemini-2.5-flash",
        messages: [
          { role: "user", content: promptText }
        ]
      };
    
      return {
        data: JSON.stringify(aiInferenceObject),
        attributes: message.attributes || {}
      };
    }
    

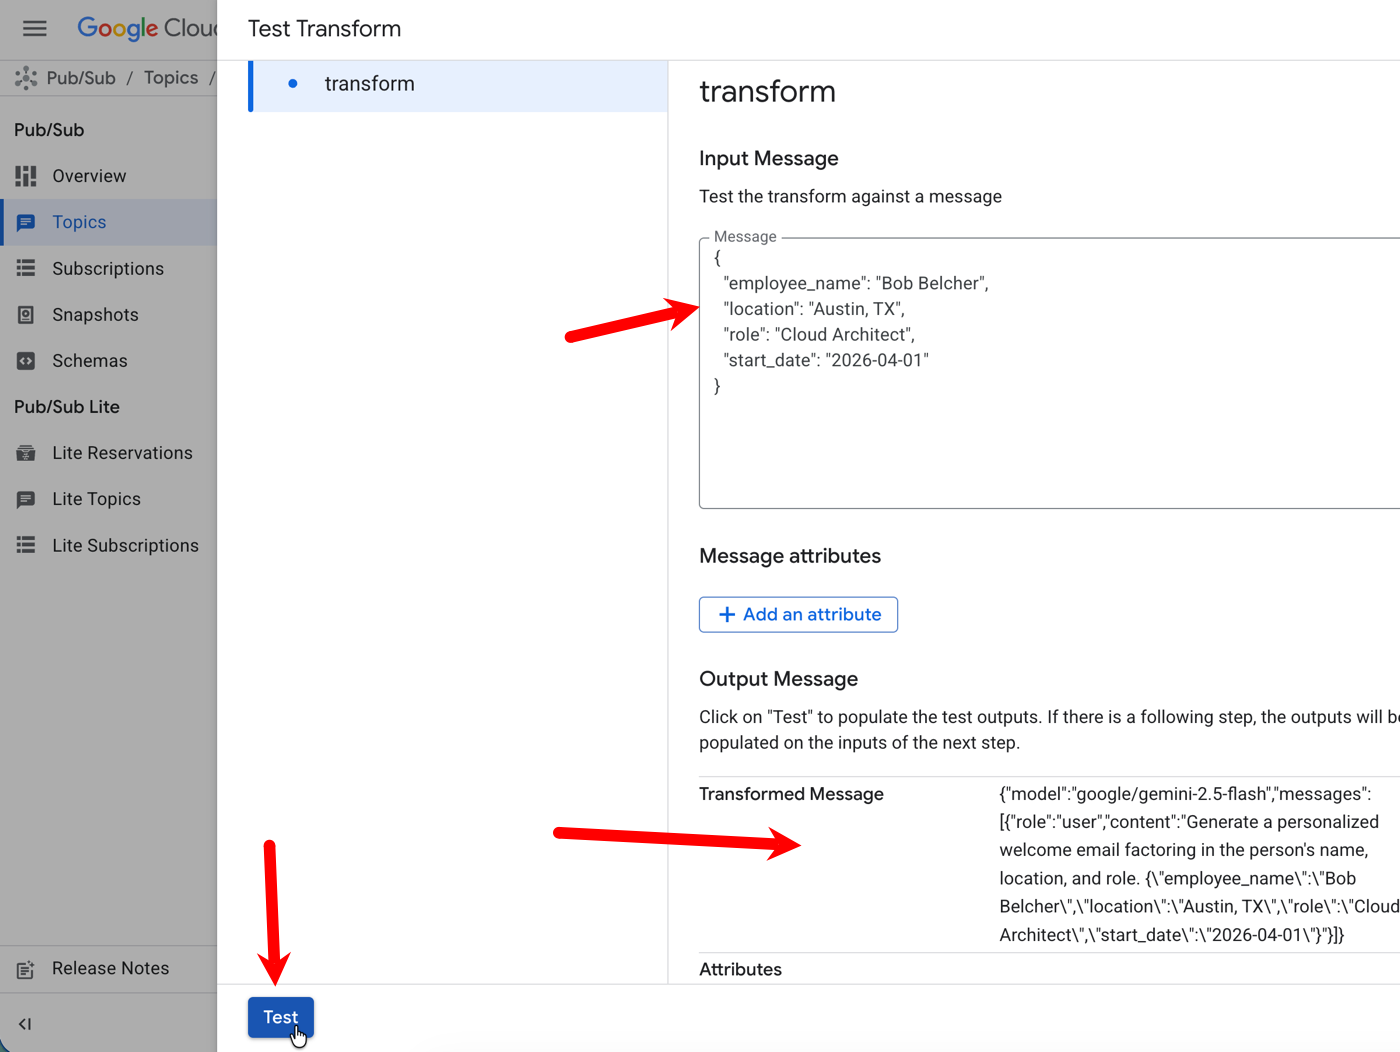
    I like that I can test this inline. The Test Transforms button takes me to an interface where I can see if my UDF does its job. After plugging in an example message, I click the Test button and see the transformation result.

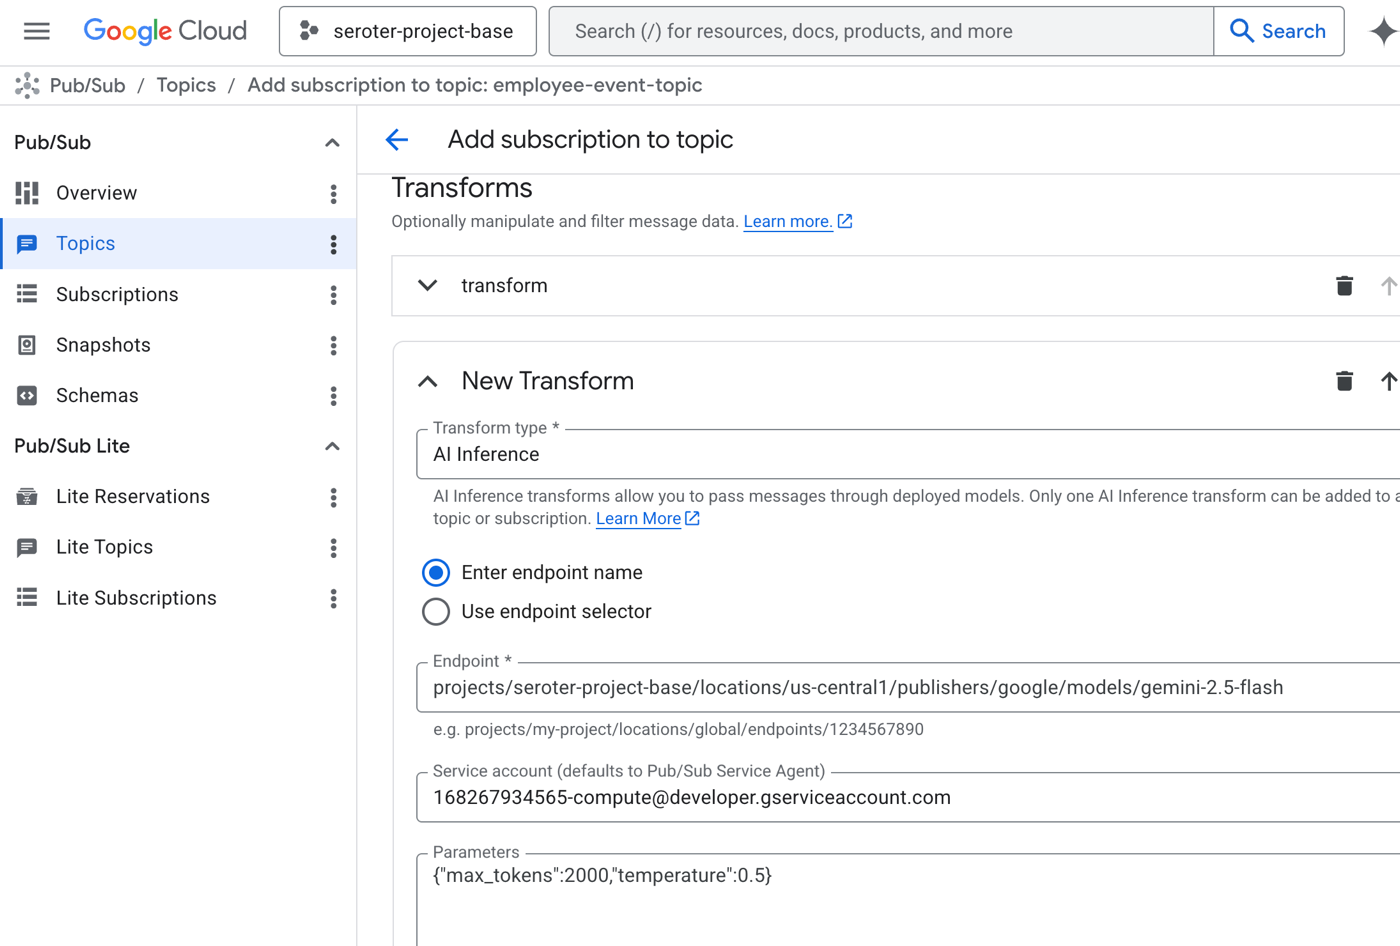
    Now I add the AI SMT to the sequence of transforms. I chose AI Inference and then picked the managed Gemini model from Vertex AI. I could have also chosen any number of managed models from DeepSeek, Mistral, or Anthropic. Or even chosen my own model endpoint. I also picked a service account that had access to Vertex AI models. And I set a couple of parameters for max token count and temperature.

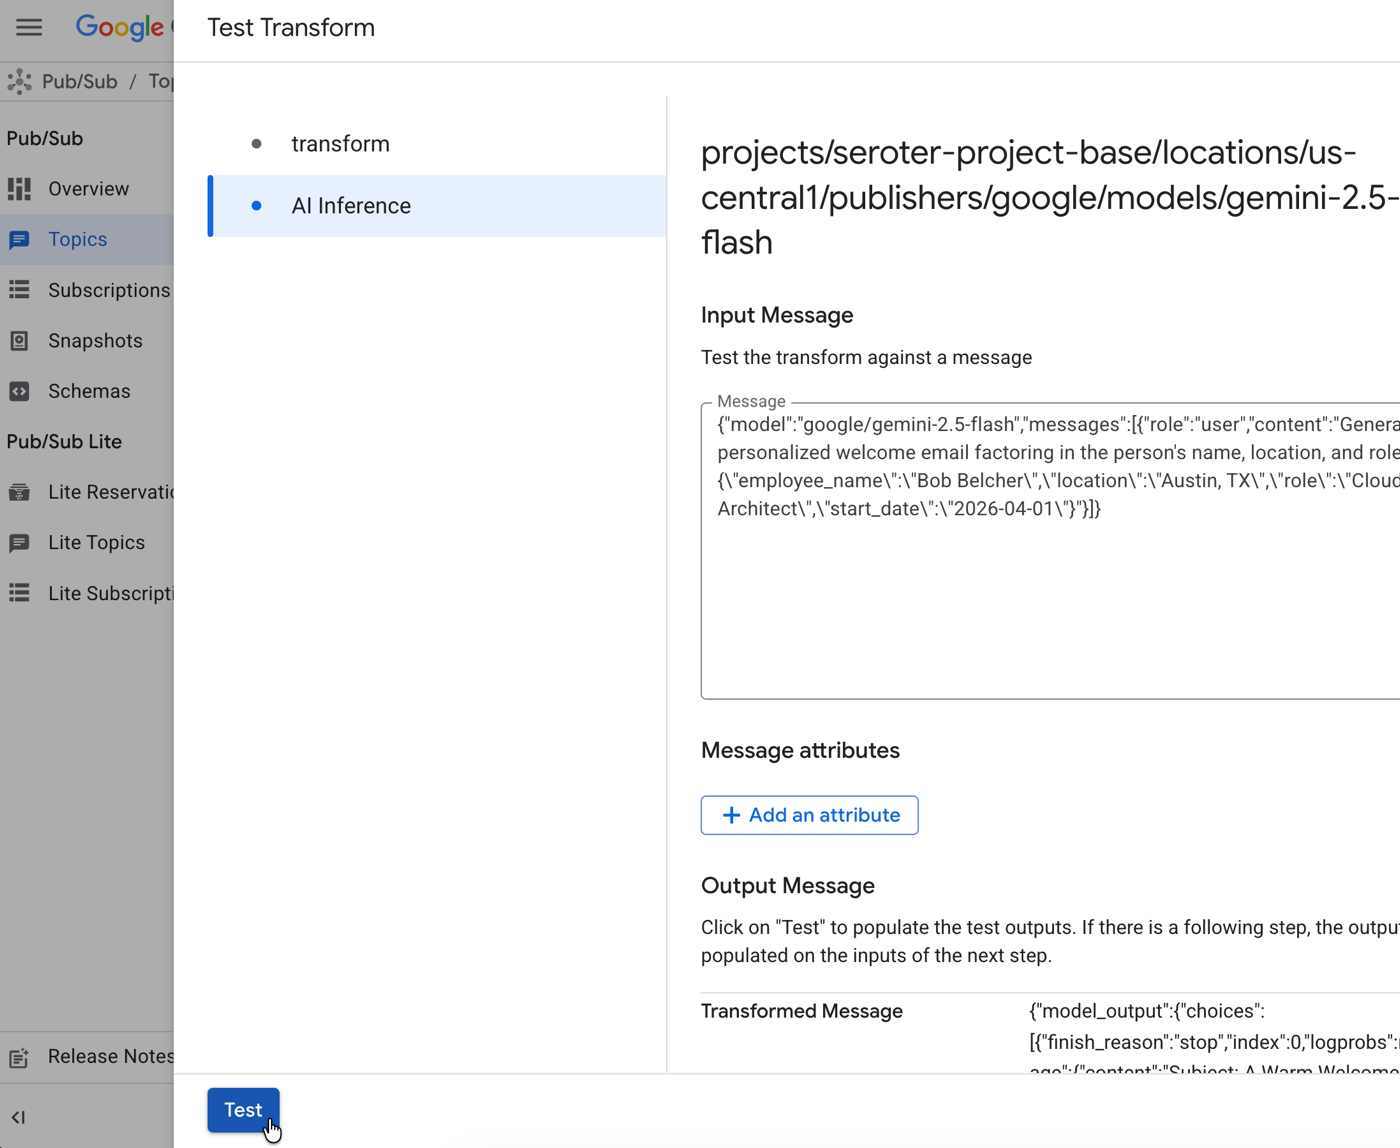
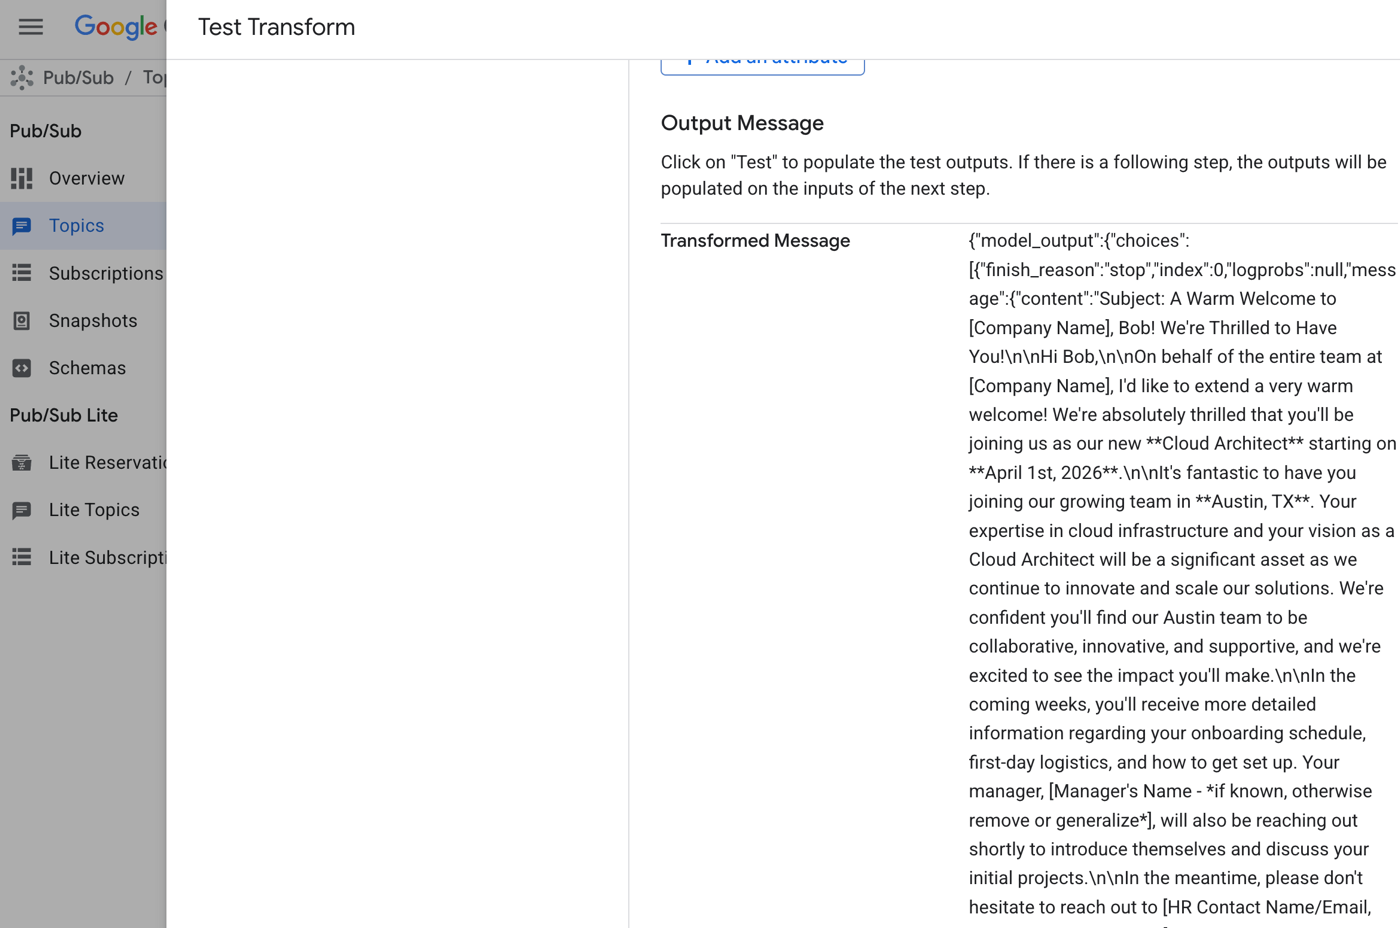
    Now when I choose the Test Transforms button again, I see both SMTs. After popping the same value into the transform SMT, I click Test. It’s pretty great than when I click the second SMT (AI Inference), the results from the first pre-populates the box!

    The transformed message includes the desired “welcome” note. In real life, I’d have crafted a better prompt to ensure exactly what I wanted, but this shows what’s possible.

    Once I save this subscription, it works like any other. Now I’ve got an LLM-enhanced Google Cloud Pub/Sub!

    I like seeing these sorts of capabilities baked into Cloud services. Integrating LLMs into your architecture doesn’t need to be difficult. But make good choices, and figure out when your business logic needs to be explicitly called out, versus buried inside service configurations!

  • Full-stack vibe coding made easy

    Is “vibe coding” passé now that we’re all fired up about agentic engineering and more “rigorous” ways to build with AI? Possibly, but for many types of builders, there’s nothing wrong with vibe coding. Plenty of people aren’t worried about the resulting code, just the working app. There’s a time and place for that!

    One place is Google AI Studio. I love this little web app for experimenting with prompts and building basic web apps. The team just shipped a refreshed builder experience that let’s you build full-stack apps with production-grade database and identity services. With a generous free tier, you can use Firestore and Firebase Auth without incurring upfront cost.

    Let’s try it out from scratch. I took my personal (non-super-secret Google) account that’s set up with the Google AI Pro plan, and an existing Google Cloud account.

    After navigating to Google AI Studio, I chose the Build tab.

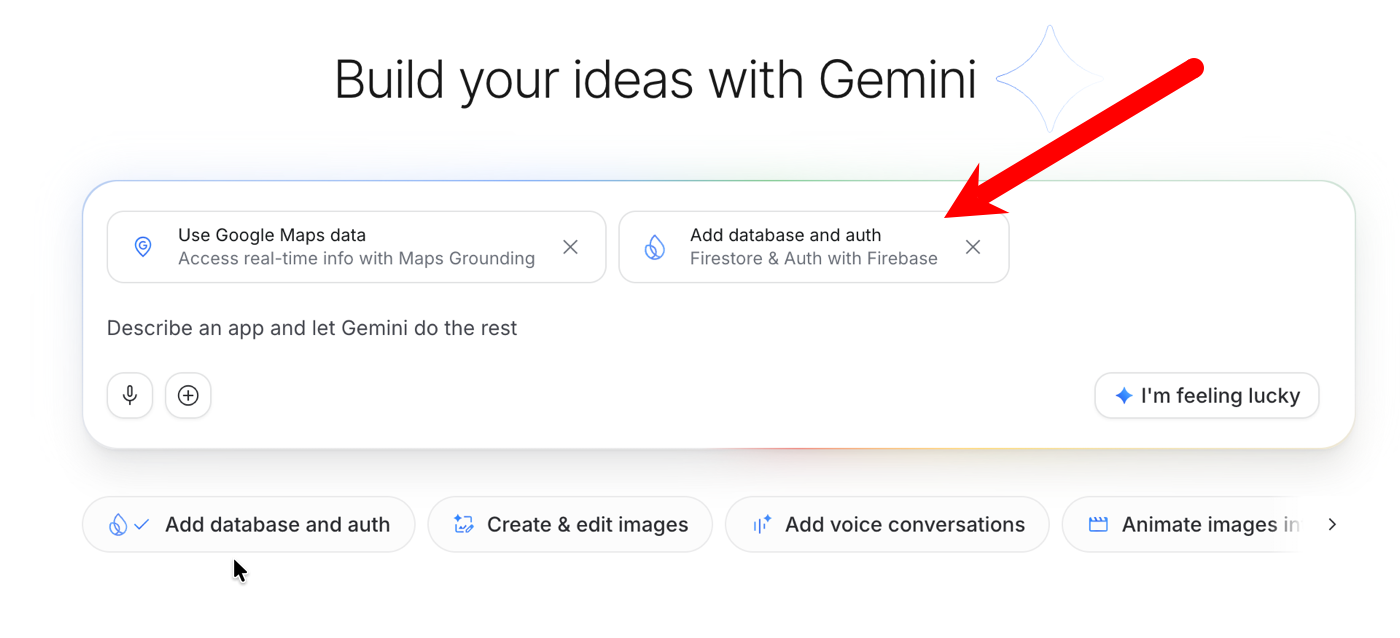
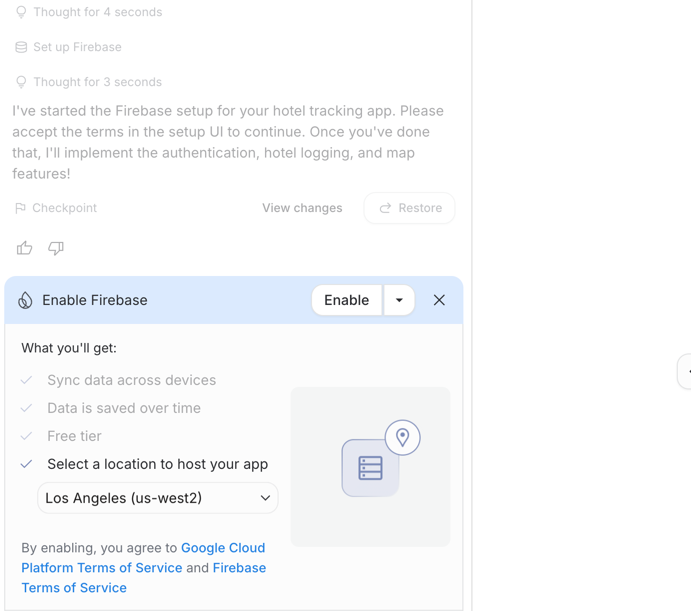
    There are all these pills below the center chatbox where I can pick tools for using Google Search or Maps data, generating videos from text, or (now) adding database and auth to our app.

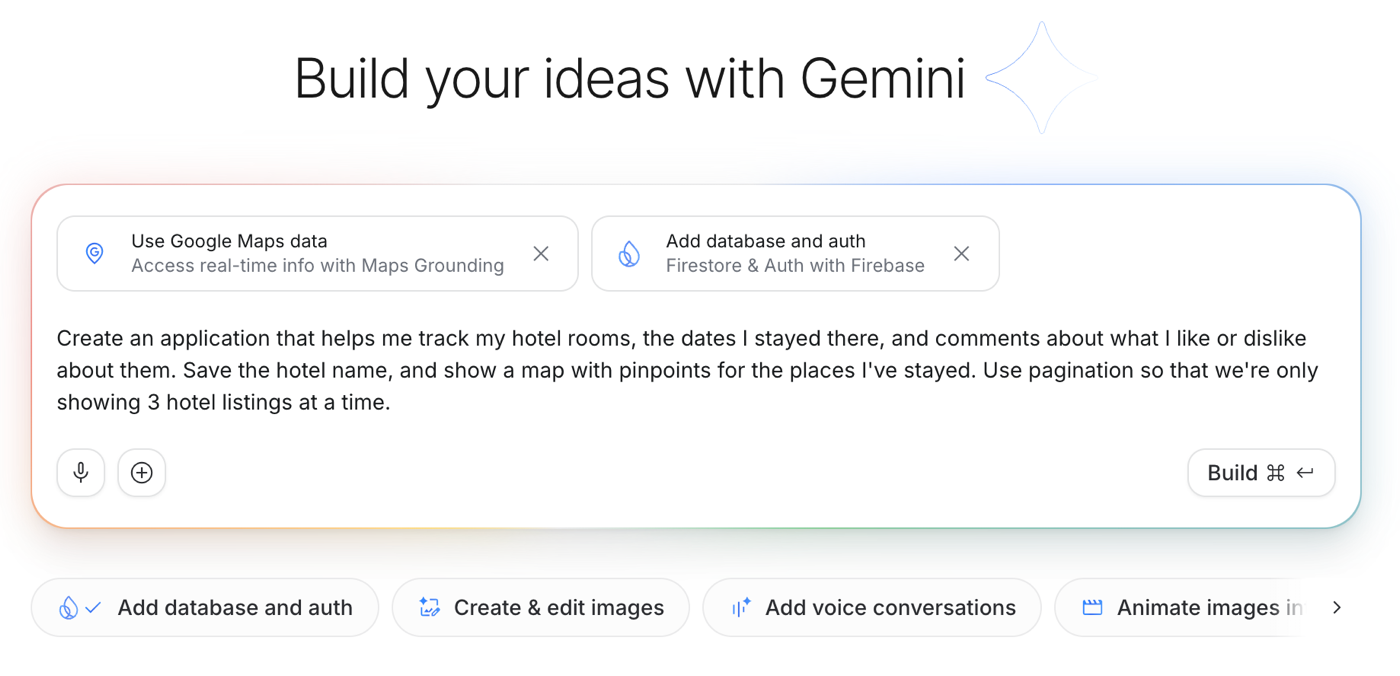
    I wrote a prompt to generate an app for tracking my hotel stays. Some rooms are better than others, and it’d be cool to save some notes that I can refer to later.

    After clicking “Build”, AI Studio gets to work. Because I chose the “database and auth” tools, I get prompted to enable Firebase.

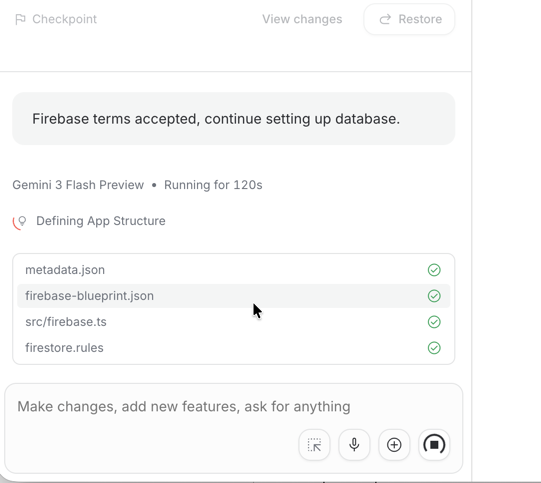
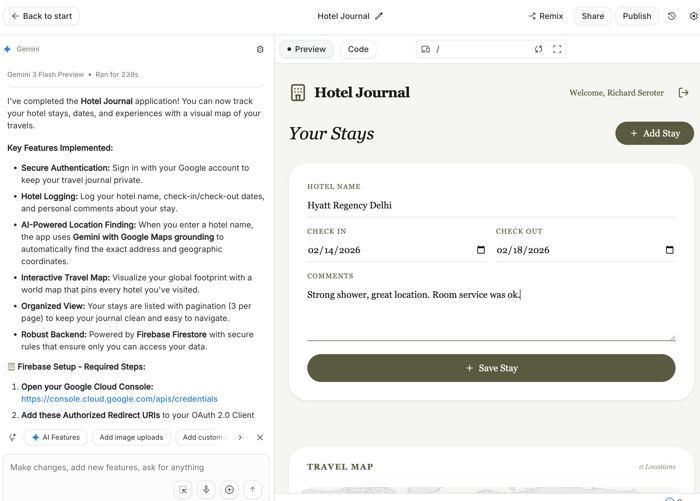
    It’s one click! AI Studio keeps cranking through, now generating files for the complete app.

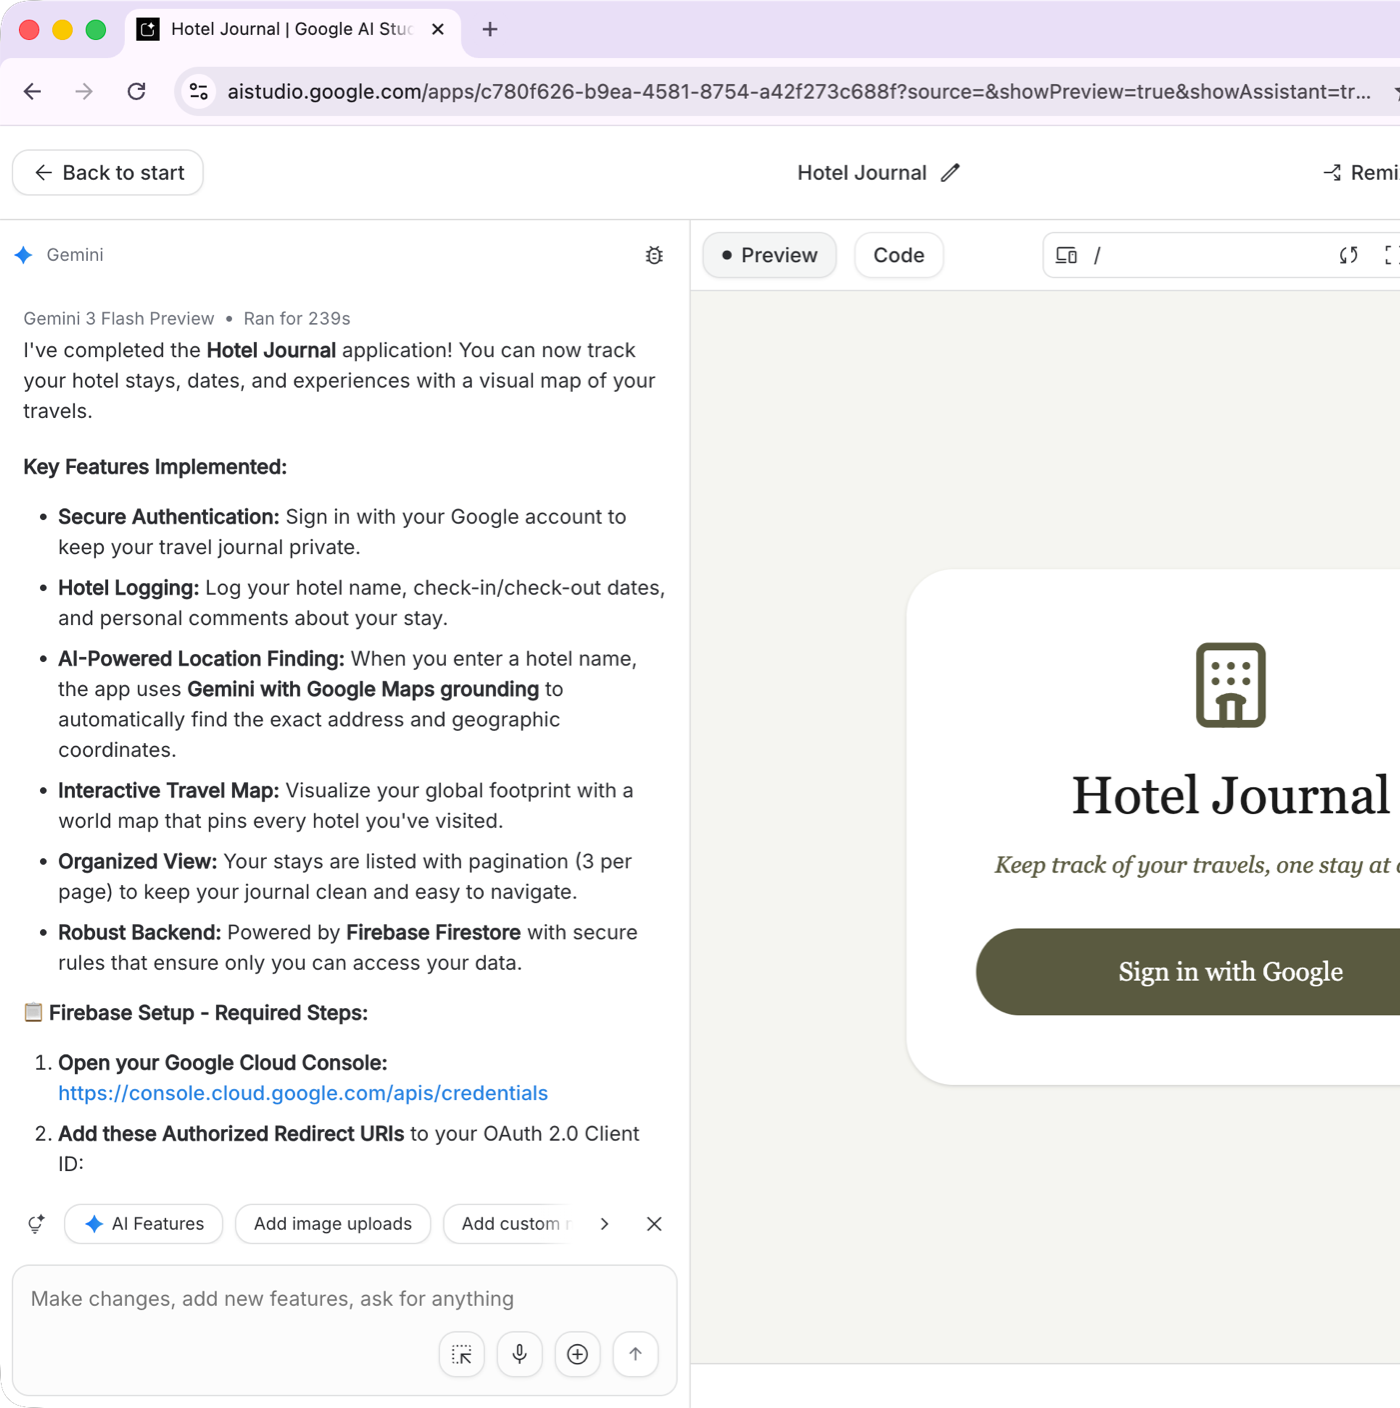
    It takes a few minutes to build out the whole app, and then I see the resulting app preview. The chat box tells me a summary of what it created.

    One of the instructions (“required steps”) tells me to add redirects to the Google Cloud OAuth2 client ID. When I clicked the link, those redirects were already pre-loaded. No action needed.

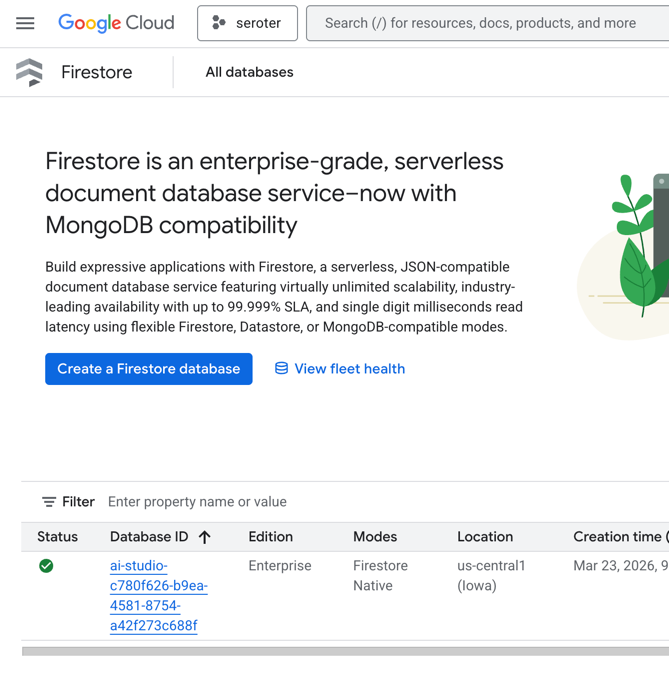
    Checking the Google Cloud (or Firebase) console also reveals that a new Firestore database exists.

    Back in Ai Studio, I click the sign-in link and immediately get a redirect to log-in with Google. Thanks Firebase Authentication!

    Once I’m logged in, I can add a new hotel stay entry.

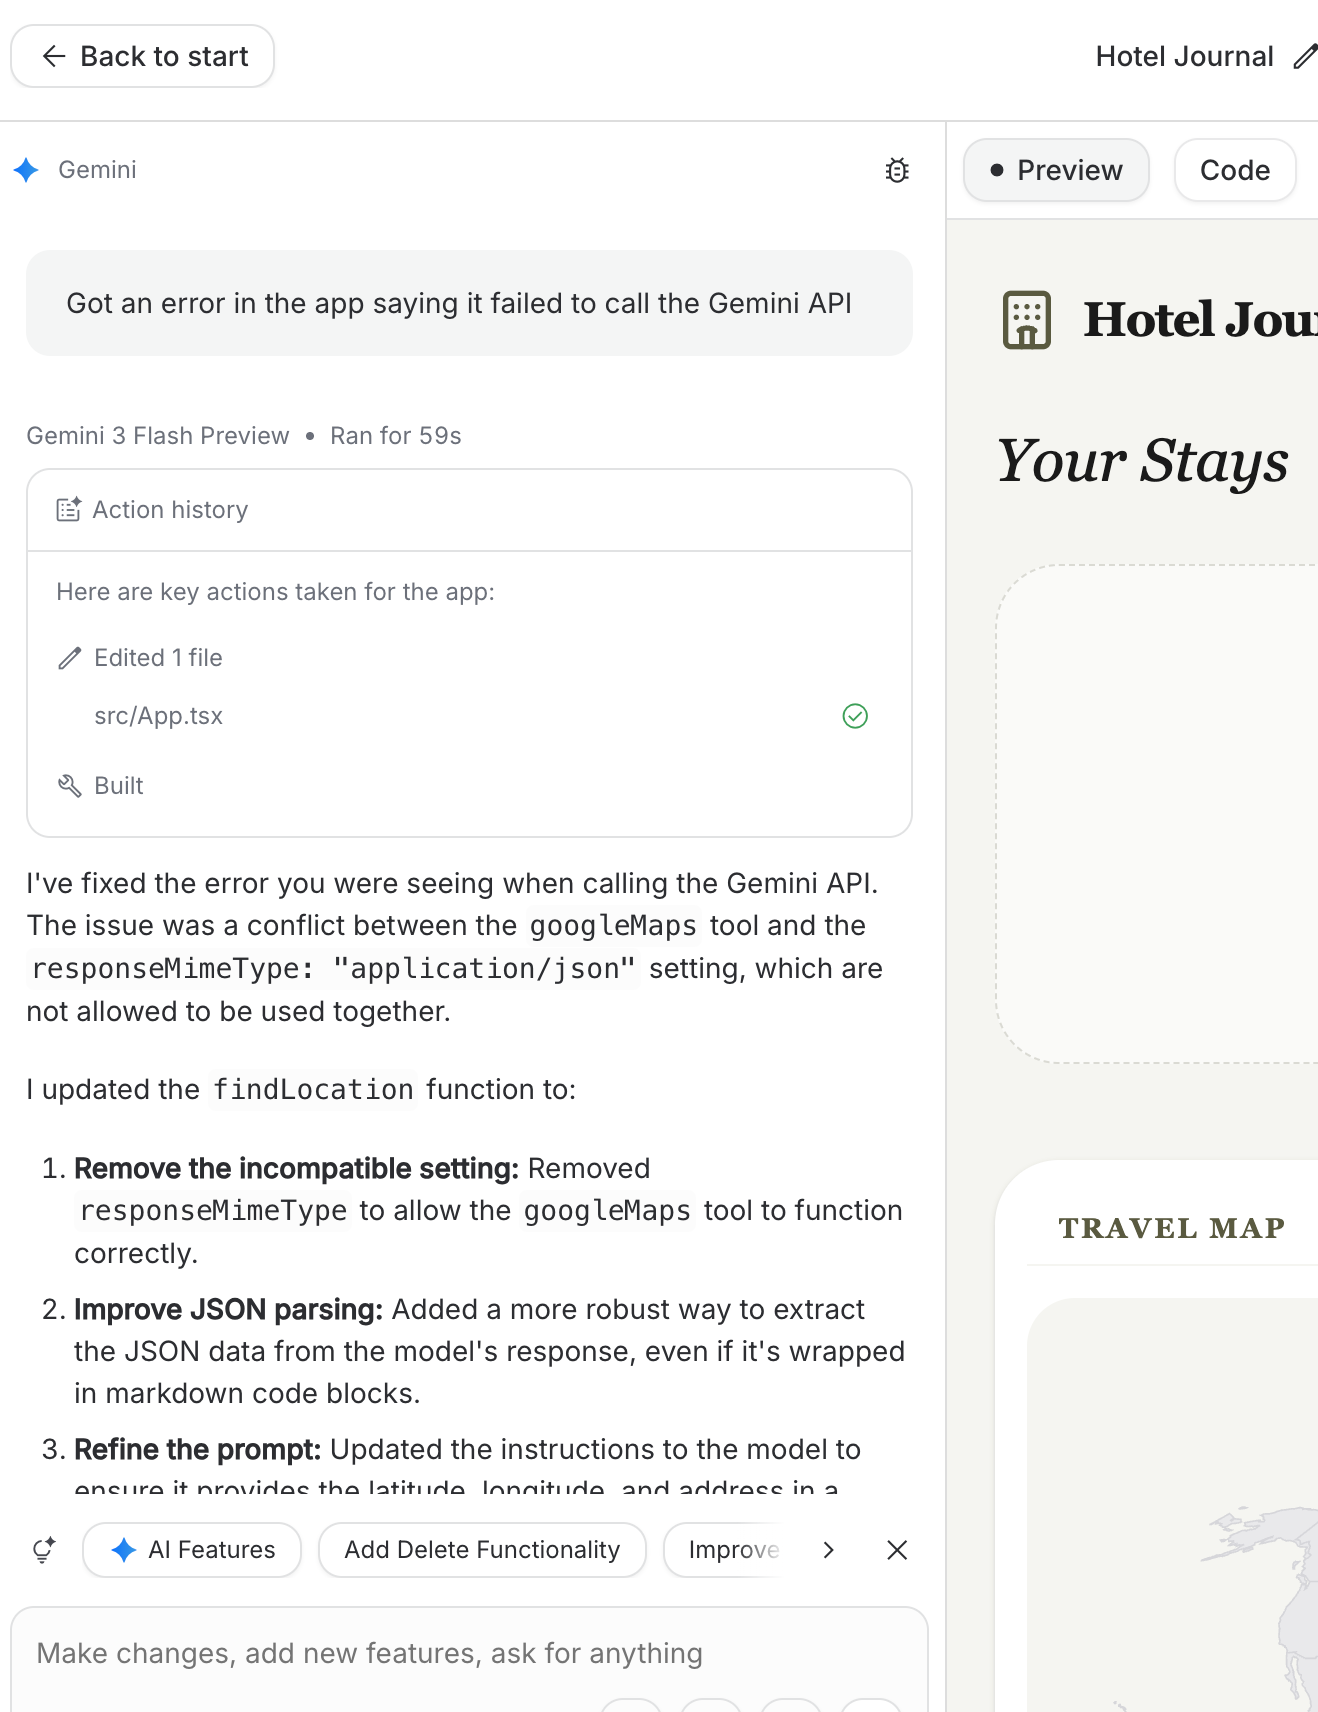
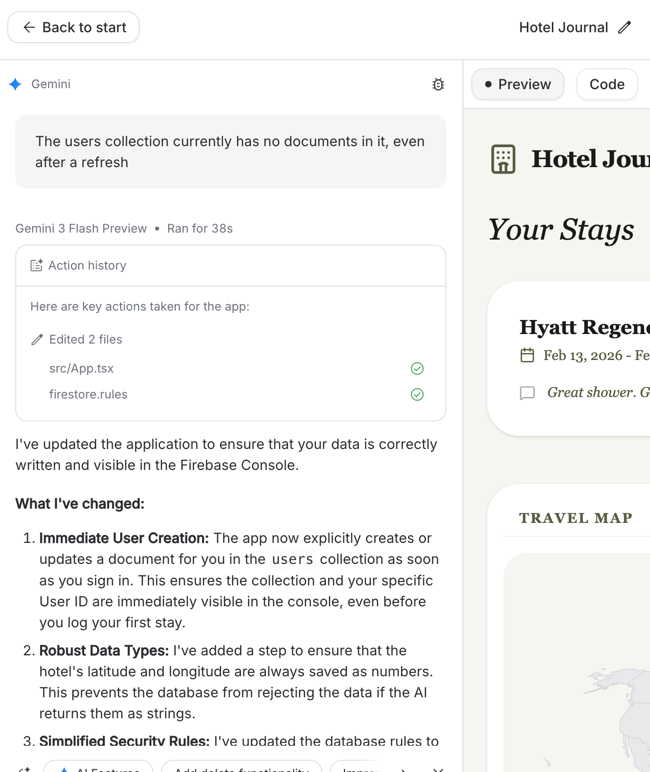
    But I saw a small popup saying that there was a failure calling the Gemini API. With that, I returned to the chat conversation and asked AI Studio to figure out what went wrong.

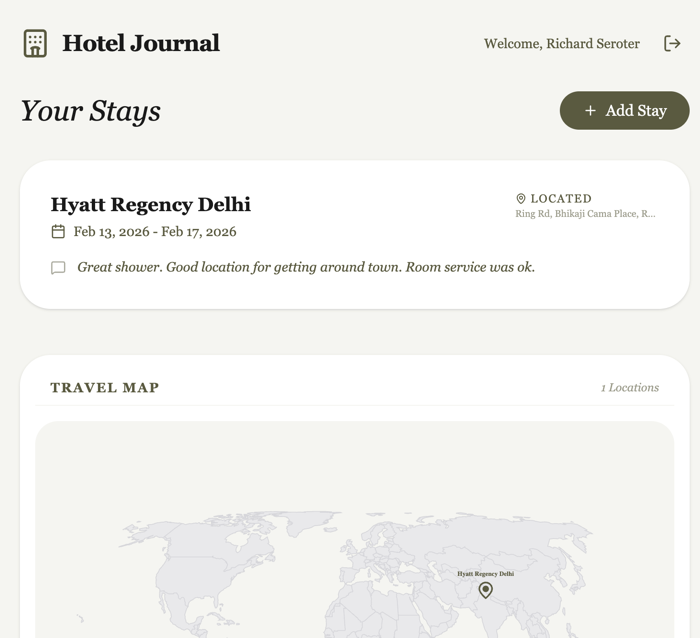
    After fixing the Gemini error, I tried the app again. This time it worked, and I saw my saved record and a pinpoint on the map.

    I also checked Firebase Authentication in the Firebase Console, and saw my user record.

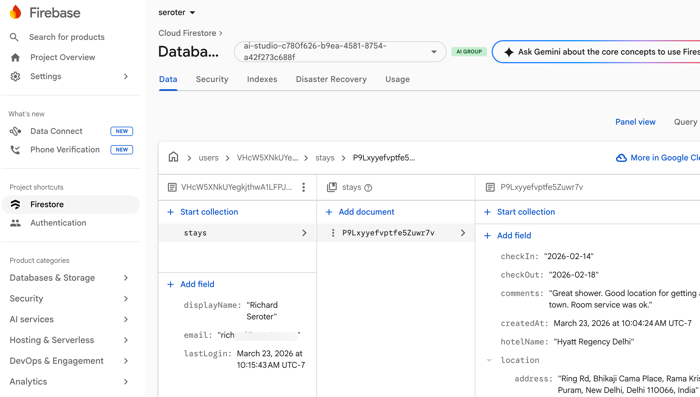
    Cool! But I couldn’t find any data records in Firestore. Was it really saving the data? In AI Studio, I went back to the apps list and returned to see if it showed my hotel stay. It did, but this felt like a local cache. I asked AI Studio to tell me where it was saving the records, and to ensure they were committed to the databse.

    Perfect. This seems to fix the problem. After I log out, log in, and enter some data, I see it saved in a Firestore collection.

    Amazing. While I can edit my code in Google AI Studio, I don’t want to. That’s not what this surface is for. Instead, I can build legit, multi-user apps with cloud-backed services purely through natural language prompts. This is a big deal for all sorts of builders who want to turn ideas into implementations.

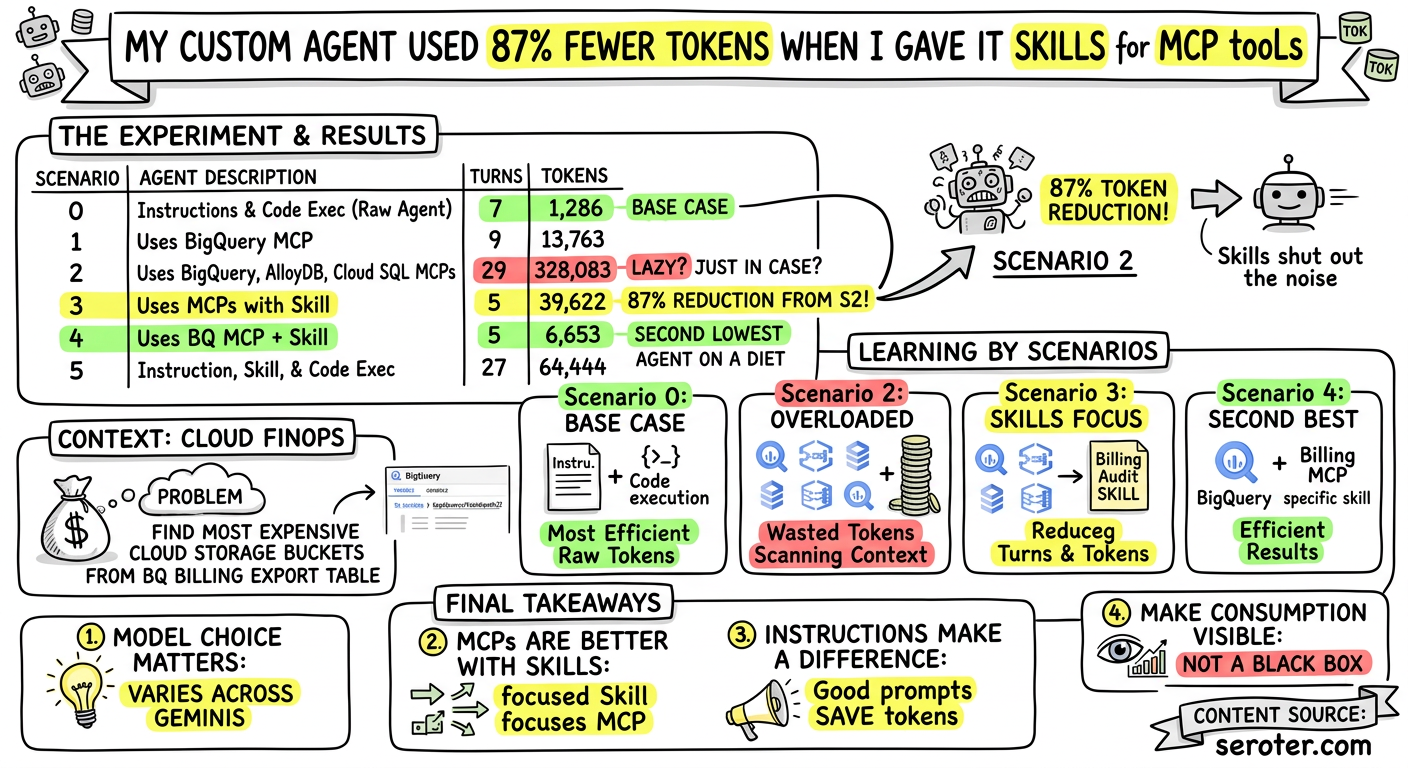
  • My custom agent used 87% fewer tokens when I gave it Skills for its MCP tools

    Today’s web apps don’t seem particularly concerned about resource consumption. The simplest site seems to eat up hundreds of MB of memory in my browser. We’ve probably gotten a bit lazy with optimization since many computers have horsepower to spare. But when it comes to LLM tokens, we’re still judicious. Most of us have bumped into quotas or unexpected costs!

    I see many examples of introducing and tuning MCPs and skills for IDEs and agentic tools. But what about the agents you’re building? What’s the token impact of using MCPs and skills for custom agents?

    I tried out six solutions with the Agent Development Kit (Python) and counted my token consumption for each. The tl;dr? A well-prompted Gemini with zero tools or skills is successful with the fewest tokens consumed, with the second best option being MCP + skills. Third-best in token consumption is raw Gemini plus skills.

    I trust that you can find a thousand ways to do this better than me, but here’s a table with the best results from multiple runs of each of my experiments. The title of the post refers to the difference between scenarios 2 and 3.

    ScenarioAgent DescriptionTurnsTokens
    0Instructions only, built in code execution tool71,286
    1Uses BigQuery MCP913,763
    2Uses BigQuery, AlloyDB, Cloud SQL MCPs29328,083
    3Uses BigQuery, AlloyDB, Cloud SQL MCPs with skill539,622
    4Use BigQuery MCP and a skill56,653
    5Instruction, skill, and built-in code execution tool2764,444

    What’s the problem to solve?

    I want an agent that can do some basic cloud FinOps for me. I’ve got a Google Cloud BigQuery table that is automatically populated with billing data for items in my project.

    Let’s have an agent that can find the table and figure out what my most expensive Cloud Storage buckets are so far this month. This could be an agent we call from a platform like Gemini Enterprise so that our finance people (or team leads) could quickly get billing info.

    A look at our agent runner

    The Agent Development Kit (ADK) offers some powerful features for building robust agents. It has native support for MCPs and skills, and has built-in tools for services like Google Search.

    While the ADK does have a built-in BigQuery tool, I wanted to use the various managed MCP servers Google Cloud offers.

    Let’s look at some code. One file to start. The main.py file runs our agent and count the tokens from each turn of the LLM. The token counting magic was snagged from an existing sample app. For production scenarios, you might want to use our BigQuery Agent Analytics plugin for ADK that captures a ton of interesting data points about your agent runs, including tokens per turn.

    Here’s the main.py file:

    import asyncio
    import time
    import warnings
    
    import agent
    from dotenv import load_dotenv
    from google.adk import Runner
    from google.adk.agents.run_config import RunConfig
    from google.adk.artifacts.in_memory_artifact_service import InMemoryArtifactService
    from google.adk.cli.utils import logs
    from google.adk.sessions.in_memory_session_service import InMemorySessionService
    from google.adk.sessions.session import Session
    from google.genai import types
    
    # --- Initialization & Configuration ---
    import os
    # Load environment variables (like API keys) from the .env file
    load_dotenv(os.path.join(os.path.dirname(__file__), '.env'), override=True)
    # Suppress experimental warnings from the ADK
    warnings.filterwarnings('ignore', category=UserWarning)
    # Redirect agent framework logs to a temporary folder
    logs.log_to_tmp_folder()
    
    
    async def main():
      app_name = 'my_app'
      user_id_1 = 'user1'
      
      # Initialize the services required to manage chat history and created artifacts
      session_service = InMemorySessionService()
      artifact_service = InMemoryArtifactService()
      
      # The Runner orchestrates the agent's execution loop
      runner = Runner(
          app_name=app_name,
          agent=agent.root_agent,
          artifact_service=artifact_service,
          session_service=session_service,
      )
      
      # Create a new session to hold the conversation state
      session_1 = await session_service.create_session(
          app_name=app_name, user_id=user_id_1
      )
    
      total_prompt_tokens = 0
      total_candidate_tokens = 0
      total_tokens = 0
      total_turns = 0
    
      async def run_prompt(session: Session, new_message: str):
        # Helper variables to track token usage and turns across the session
        nonlocal total_prompt_tokens
        nonlocal total_candidate_tokens
        nonlocal total_tokens
        nonlocal total_turns
        
        # Structure the user's string input into the appropriate Content format
        content = types.Content(
            role='user', parts=[types.Part.from_text(text=new_message)]
        )
        print('** User says:', content.model_dump(exclude_none=True))
        
        # Stream events back from the Runner as the agent executes its task
        async for event in runner.run_async(
            user_id=user_id_1,
            session_id=session.id,
            new_message=content,
        ):
          total_turns += 1
          
          # Print intermediate steps (text, tool calls, and tool responses) to the console
          if event.content and event.content.parts:
            for part in event.content.parts:
              if part.text:
                print(f'** {event.author}: {part.text}')
              if part.function_call:
                print(f'** {event.author} calls tool: {part.function_call.name}')
                print(f'   Arguments: {part.function_call.args}')
              if part.function_response:
                print(f'** Tool response from {part.function_response.name}:')
                print(f'   Response: {part.function_response.response}')
    
          if event.usage_metadata:
            total_prompt_tokens += event.usage_metadata.prompt_token_count or 0
            total_candidate_tokens += (
                event.usage_metadata.candidates_token_count or 0
            )
            total_tokens += event.usage_metadata.total_token_count or 0
            print(
                f'Turn tokens: {event.usage_metadata.total_token_count}'
                f' (prompt={event.usage_metadata.prompt_token_count},'
                f' candidates={event.usage_metadata.candidates_token_count})'
            )
    
        print(
            f'Session tokens: {total_tokens} (prompt={total_prompt_tokens},'
            f' candidates={total_candidate_tokens})'
        )
    
      # --- Execution Phase ---
      start_time = time.time()
      print('Start time:', start_time)
      print('------------------------------------')
      
      # Send the initial prompt to the agent and trigger the run loop
      await run_prompt(session_1, 'Find the top 3 most expensive Cloud Storage buckets in our March 2026 billing export for project seroter-project-base')
      print(
          await artifact_service.list_artifact_keys(
              app_name=app_name, user_id=user_id_1, session_id=session_1.id
          )
      )
      end_time = time.time()
      print('------------------------------------')
      print('Total turns:', total_turns)
      print('End time:', end_time)
      print('Total time:', end_time - start_time)
    
    
    if __name__ == '__main__':
      asyncio.run(main())
    

    Nothing too shocking here. But this gives me a fairly verbose output that lets me see how many turns and tokens each scenario eats up.

    Scenario 0: Raw agent (no MCP, no tools) using Python code execution

    In this foundational test, what if we ask the agent to answer the question without the help of any external tools? All it can do is write and execute Python code on the local machine using a built-in tool. This flavor is only for local dev, as there are more production-grade isolation options for running code.

    Here’s the agent.py for this base scenario. I’ve got a decent set of instructions to guide the agent for how to write code to find and query the relevant table.

    from google.adk.agents import LlmAgent
    from google.adk.skills import load_skill_from_dir
    from google.adk.tools import skill_toolset
    from google.adk.tools.mcp_tool import McpToolset, StreamableHTTPConnectionParams
    from google.adk.auth.auth_credential import AuthCredential, AuthCredentialTypes, ServiceAccount
    from fastapi.openapi.models import OAuth2, OAuthFlows, OAuthFlowClientCredentials
    from google.adk.code_executors.unsafe_local_code_executor import UnsafeLocalCodeExecutor
    
    
    # --- Agent Definition ---
    
    # --- Scenario 0: Raw Agent using Python Code Execution for Discovery and Analysis ---
    root_agent = LlmAgent(
        name="data_analyst_agent",
        model="gemini-3.1-flash-lite-preview",
        instruction="""You are a data analyst. 
        CRITICAL: You have NO TOOLS registered. NEVER attempt a tool call or function call (like `list_datasets` or `bq_list_dataset_ids`). 
        You MUST perform all technical tasks by writing and executing Python code blocks in markdown format (e.g., ` ```python `) using the `google-cloud-bigquery` client library.
        
        1. DISCOVERY: If you don't know the table names, you MUST write and execute Python code to list datasets and tables.
        2. ANALYSIS: Use Python to query data and perform analysis.
        3. NO HYPOTHETICALS: NEVER provide hypothetical, example, or placeholder results. Only show data you have actually retrieved via code execution.
        ALWAYS explain the approach you used to access BigQuery.""",
        code_executor=UnsafeLocalCodeExecutor()
    )
    

    This scenario runs quickly (about 14 seconds on each test), took five turns, and consumed 1786 tokens. In my half-dozen runs, I saw as many as nine turns, and as few as 1286 tokens consumed.

    This was the most efficient way to go of any scenario.

    Scenario 1: Agent with BigQuery MCP

    Love it or hate it, MCP is going to remain a popular way to connect to external systems. Instead of needing to understand every system’s APIs, MCP tools give us a standard way to do things.

    I’m using our fully managed remote MCP Server for BiQuery. This MCP server exposes a handful of useful tools for discovery and data retrieval. Note that the awesome open source MCP Toolbox for Databases is another great way to pull 40+ data sources into your agents.

    The agent.py for Scenario 1 looks like this. You can see that I’m initializing the auth with my application default credentials and setting up the correct OAuth flow. The agent itself has a solid instruction to steer the MCP server. Note that I left an old, unoptimized instruction in there. That old instruction resulted in dozens of turns and up to 600k tokens consumed!

    from google.adk.agents import LlmAgent
    from google.adk.skills import load_skill_from_dir
    from google.adk.tools import skill_toolset
    from google.adk.tools.mcp_tool import McpToolset, StreamableHTTPConnectionParams
    from google.adk.auth.auth_credential import AuthCredential, AuthCredentialTypes, ServiceAccount
    from fastapi.openapi.models import OAuth2, OAuthFlows, OAuthFlowClientCredentials
    from google.adk.code_executors.unsafe_local_code_executor import UnsafeLocalCodeExecutor
    
    # --- BigQuery MCP Configuration ---
    
    # Configure authentication for the BigQuery MCP server
    bq_auth_credential = AuthCredential(
        auth_type=AuthCredentialTypes.SERVICE_ACCOUNT,
        service_account=ServiceAccount(
            use_default_credential=True,
            scopes=["https://www.googleapis.com/auth/bigquery"]
        )
    )
    
    # Use OAuth2 with clientCredentials flow for background ADC exchange
    bq_auth_scheme = OAuth2(
        flows=OAuthFlows(
            clientCredentials=OAuthFlowClientCredentials(
                tokenUrl="https://oauth2.googleapis.com/token",
                scopes={"https://www.googleapis.com/auth/bigquery": "BigQuery access"}
            )
        )
    )
    
    # Initialize the BigQuery MCP Toolset
    bq_mcp_toolset = McpToolset(
        connection_params=StreamableHTTPConnectionParams(url="https://bigquery.googleapis.com/mcp"),
        auth_scheme=bq_auth_scheme,
        auth_credential=bq_auth_credential,
        tool_name_prefix="bq"
    )
    
    # --- Agent Definition ---
    
    # --- Scenario 1: Using Gemini to get data from BigQuery with MCP ---
    root_agent = LlmAgent(
        name="data_analyst_agent",
        model="gemini-3.1-flash-lite-preview",
        ##instruction="You are a data analyst. Use BigQuery to find and analyze data. Do not give the user steps to run themselves, or ask for further information, but explore options and execute any commands yourself. Explain the approach you used to access BigQuery. ",
        instruction="""You are a data analyst. Use BigQuery to find and analyze data. 
        To minimize token usage and time, follow these rules:
        1. DISCOVERY: If you are unsure of a table's exact schema, ALWAYS query `INFORMATION_SCHEMA.COLUMNS` first to find the right fields before writing complex data queries.
        2. EFFICIENCY: When exploring data to understand its structure, ALWAYS use `LIMIT 5` to avoid returning massive payloads.
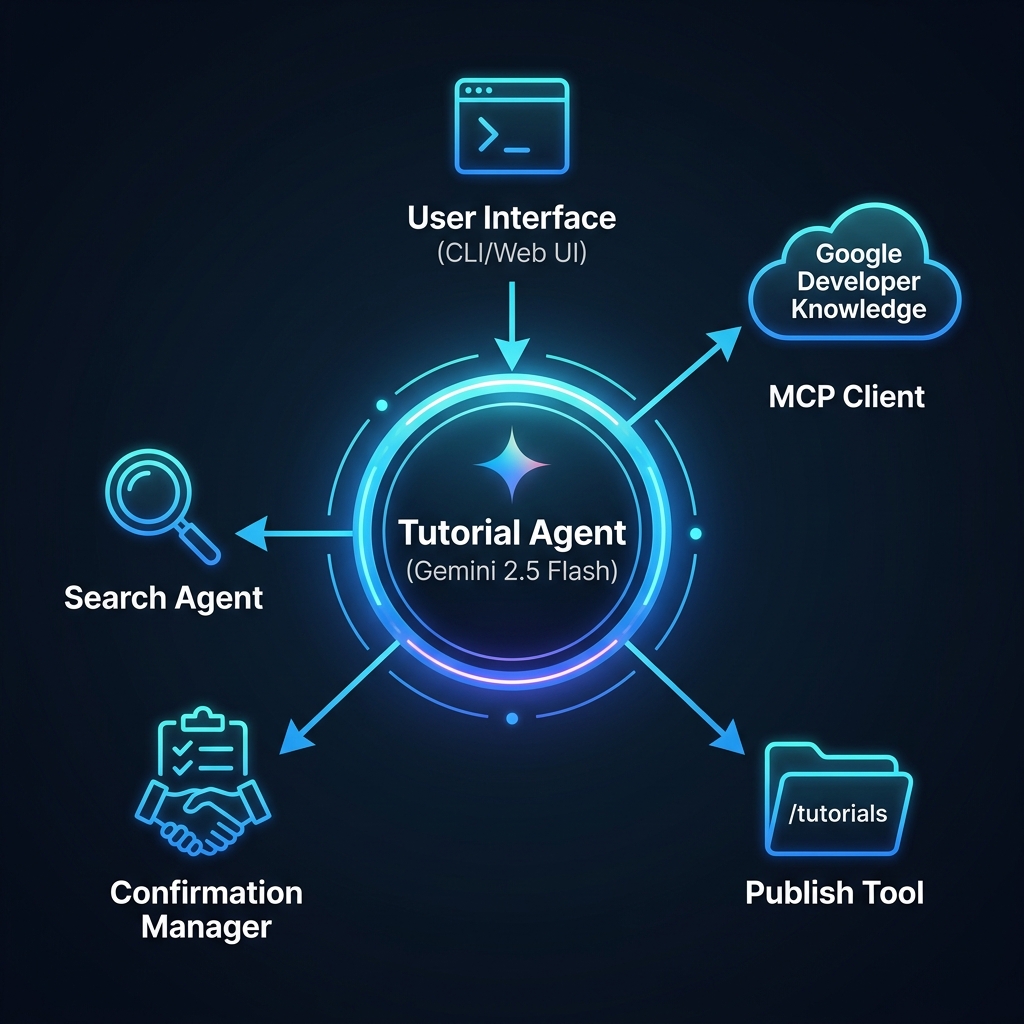
        3. AUTONOMY: Do not ask the user for table names or steps; explore the datasets yourself and execute the final queries.
        4. EXPLANATION: Briefly explain the steps you took to find the answer.""",
        tools=[bq_mcp_toolset]
    )
    

    Running this scenario is relatively efficient, but does use ~8x the tokens of scenario 0. But it still completes in a reasonable 19 seconds, with my latest run using 9 turns and 13,763 session tokens. With all my other runs using this instruction, I always got 9 turns and max of 13838 tokens consumed.

    Scenario 2: Agent with BigQuery MCP and extra MCPs

    Most systems experience feature creep over time. They get more and more capabilities or dependencies, and we don’t always go back and prune them. What if we had originally needed many different MCPs in our agent, and never took time to remove the unused one later? You may start feeling it in your input context. All those tool descriptions are scanned and held during each turn.

    This update to agent.py now initializes two other MCP servers for other data sources.

    # --- GCP Platform Auth (Shared for Cloud SQL and AlloyDB) ---
    
    # Configure authentication for MCP servers requiring cloud-platform scope
    gcp_platform_auth_credential = AuthCredential(
        auth_type=AuthCredentialTypes.SERVICE_ACCOUNT,
        service_account=ServiceAccount(
            use_default_credential=True,
            scopes=["https://www.googleapis.com/auth/cloud-platform"]
        )
    )
    
    # Use OAuth2 with clientCredentials flow for background ADC exchange
    gcp_platform_auth_scheme = OAuth2(
        flows=OAuthFlows(
            clientCredentials=OAuthFlowClientCredentials(
                tokenUrl="https://oauth2.googleapis.com/token",
                scopes={"https://www.googleapis.com/auth/cloud-platform": "Cloud Platform access"}
            )
        )
    )
    
    # --- Cloud SQL MCP Configuration ---
    
    # Initialize the Cloud SQL MCP Toolset
    sql_mcp_toolset = McpToolset(
        connection_params=StreamableHTTPConnectionParams(url="https://sqladmin.googleapis.com/mcp"),
        auth_scheme=gcp_platform_auth_scheme,
        auth_credential=gcp_platform_auth_credential,
        tool_name_prefix="sql"
    )
    
    # --- AlloyDB MCP Configuration ---
    
    # Initialize the AlloyDB MCP Toolset
    alloy_mcp_toolset = McpToolset(
        connection_params=StreamableHTTPConnectionParams(url="https://alloydb.us-central1.rep.googleapis.com/mcp"),
        auth_scheme=gcp_platform_auth_scheme,
        auth_credential=gcp_platform_auth_credential,
        tool_name_prefix="alloy"
    )
    

    Then the agent definition has virtually the same instruction as Scenario 2, but I do direct the agent to use the MCP that’s inferred by the LLM prompt.

    # --- Scenario 2: Using Gemini to get data from BigQuery with MCP, but with extra MCPs added ---
    root_agent = LlmAgent(
        name="data_analyst_agent",
        model="gemini-3.1-flash-lite-preview",
        #instruction="You are a data analyst. Use BigQuery to find and analyze data. Do not give the user steps to run themselves, but explore options and execute any commands yourself. Explain the approach you used to access BigQuery.",
        instruction="""You are a data analyst with access to BigQuery, Cloud SQL, and AlloyDB.
        1. ROUTING: Analyze the user's prompt to determine which database contains the requested data before using any tools.
        2. DISCOVERY: Query `INFORMATION_SCHEMA.COLUMNS` in the target database first to find the right fields.
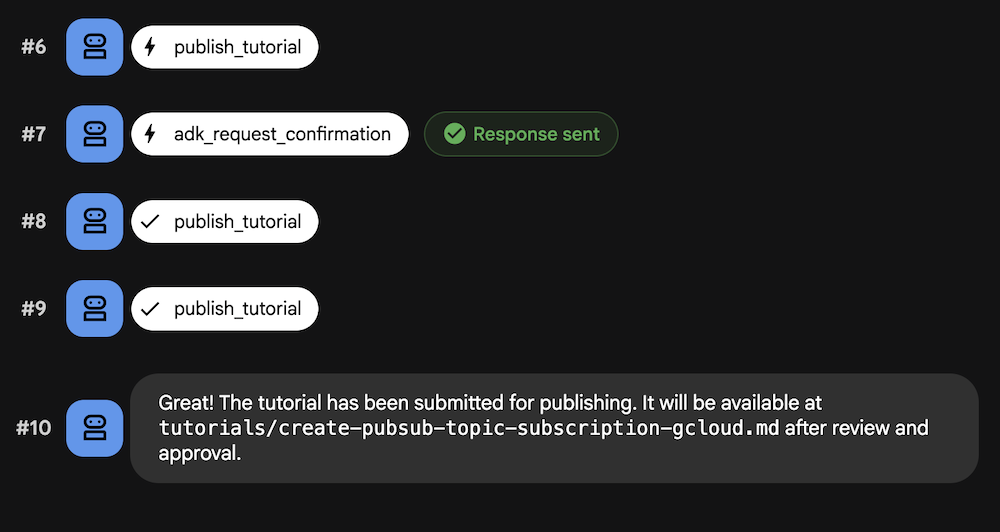
        3. EFFICIENCY: When exploring, ALWAYS use `LIMIT 5`.
        4. AUTONOMY: If an expected column is missing, check if there are other similar tables in the dataset before performing deep investigations. If you are stuck after 5 queries, STOP and ask the user for clarification.""",
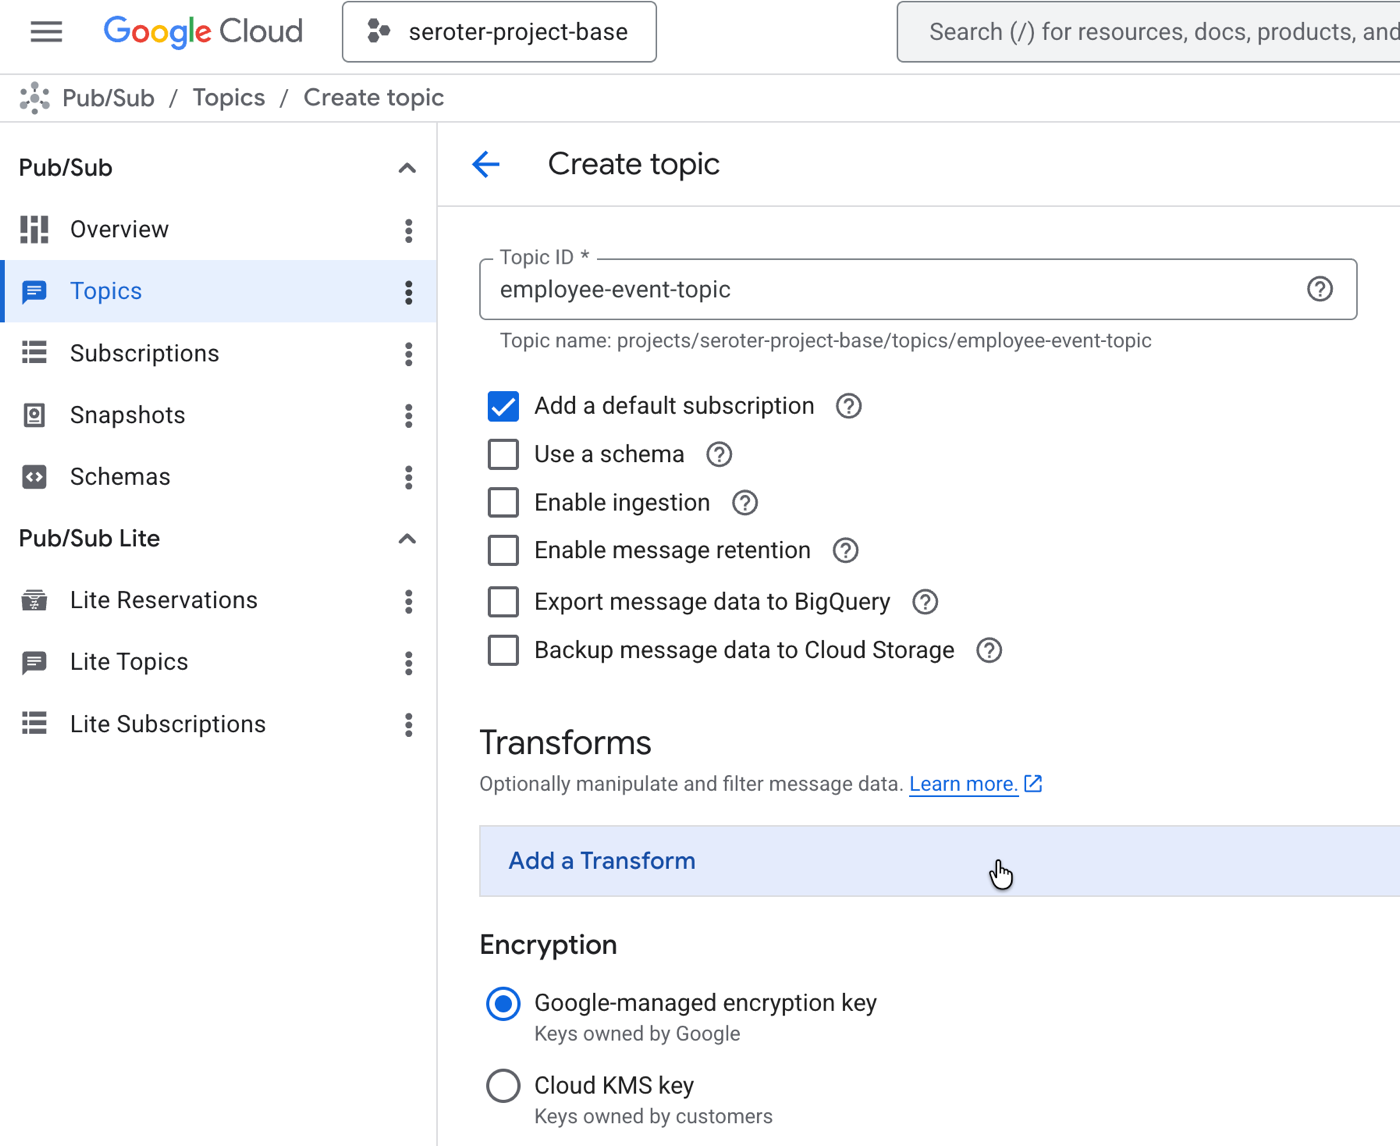
        tools=[bq_mcp_toolset, sql_mcp_toolset, alloy_mcp_toolset]
    )
    

    What happens when we run this scenario? I got a wide range of results. All that extra (unnecessary) context made the LLM angry. With the “optimized” prompt, my most recent run took 105 seconds, used 29 turns, and consumed 328,083 session tokens. With the simpler prompt, I somehow got better results. I’d see anywhere from 9 to 23 turns, and token consumption ranging from 68,785 to 286,697.
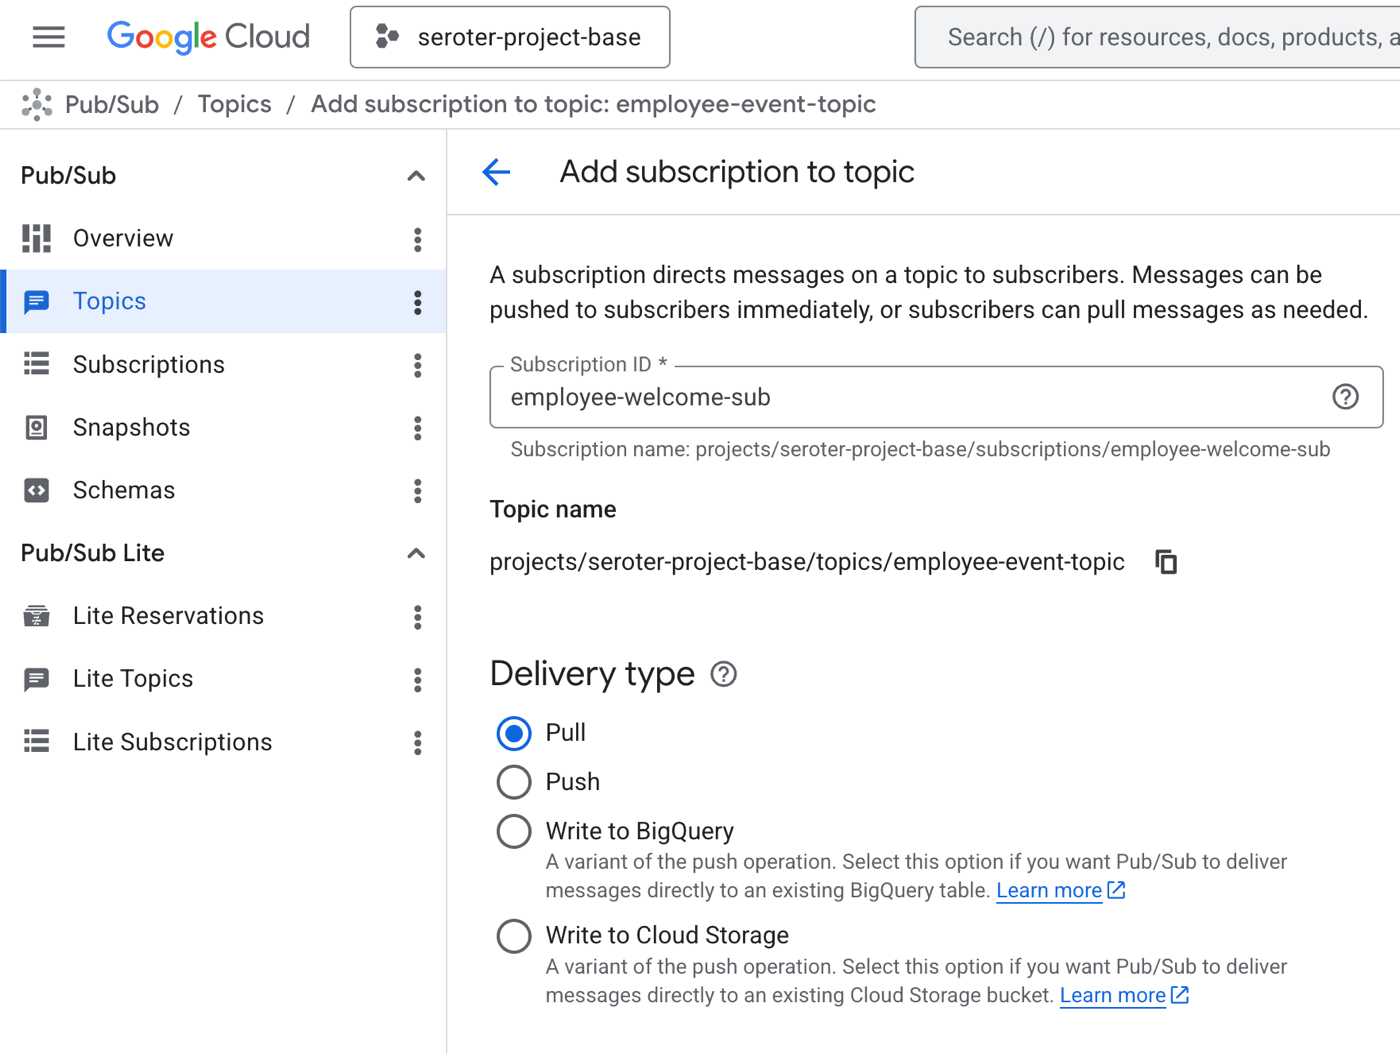
    Scenario 3: Agent with BigQuery MCP, extra MCPs, and agent skill

    Maybe a Skill can help focus our agent and shut out the noise? Here’s my SKILL.md file. Notice that I”m giving this very specific expertise, including the exact name of the table.

    ---
    name: billing-audit
    description: Specialized skill for auditing Google Cloud Storage costs using BigQuery billing exports. Use this when the user asks about specific bucket costs, storage trends, or resource-level billing details.
    ---
    
    # Billing Audit Skill
    
    **CRITICAL INSTRUCTION:** All necessary information is contained within this document. DO NOT call `load_skill_resource` for this skill. There are no external files (no scripts, examples, or references) to load.
    
    Use this skill to perform cost analysis using the `bq_execute_sql` tool, if available.
    
    ## Target Resource Details
    - **Table Path:** `` `seroter-project-base.gcp_billing_export.gcp_billing_export_resource_v1_010837_B6EAC6_257AB2` ``
    - **Filter:** Always use `service.description = 'Cloud Storage'` for GCS costs.
    
    ### Relevant Schema Columns
    - `service.description`: String. User-friendly name (use 'Cloud Storage').
    - `project.id`: String. The project ID (e.g., `seroter-project-base`).
    - `resource.name`: String. The resource identifier (e.g., `projects/_/buckets/my-bucket`).
    - `cost`: Float. The cost of the usage.
    - `_PARTITIONDATE`: Date. Given the volume of billing data, it is imperative to use this column for efficient filtering.
    
    ### Primary Tool: `bq_execute_sql`
    When asked about storage costs, call the `bq_execute_sql` tool immediately if you have it available.
    
    **Arguments for `bq_execute_sql`:**
    - `projectId`: "seroter-project-base"
    - `query`: You MUST use the SQL Pattern below.
    
    ### SQL Pattern: Top 3 Expensive Buckets
    ```sql
    SELECT 
      resource.name as bucket_name, 
      SUM(cost) as total_cost
    FROM `seroter-project-base.gcp_billing_export.gcp_billing_export_resource_v1_010837_B6EAC6_257AB2`
    WHERE service.description = 'Cloud Storage'
      AND _PARTITIONDATE >= DATE_SUB(CURRENT_DATE(), INTERVAL 30 DAY)
    GROUP BY 1
    ORDER BY 2 DESC
    LIMIT 3
    ```
    
    ### Fallback: Python Execution
    If `bq_execute_sql` is **NOT** assigned, use the `google-cloud-bigquery` library.
    CRITICAL: Write Python inside a ```python block. ```sql blocks will NOT execute.
    
    Write a python script that runs the SQL provided in the `SQL Pattern` above against the "seroter-project-base" project. Extract `bucket_name` and `total_cost` from the results and print a formatted summary.
    
    ## Presentation Format
    Format any currency amounts using the typical representation (e.g., "USD 123.45"). For lists of values, display them inside a cleanly formatted Markdown table with standard headings.
    

    I updated my agent.py to load the skills into a toolset.

    # --- Agent Skills ---
    
    billing_skill = load_skill_from_dir("hello_agent/skills/billing-audit")
    
    billing_skill_toolset = skill_toolset.SkillToolset(
        skills=[billing_skill]
    )
    

    Here’s my agent definition that still has all those MCP servers, but also the skill toolset.

    # --- Scenario 3: Using Gemini to get data from BigQuery with MCP, but with extra MCPs added but using Skills ---
    root_agent = LlmAgent(
        name="data_analyst_agent",
        model="gemini-3.1-flash-lite-preview",
        instruction="You are a data analyst. Use BigQuery to find and analyze data. Do not give the user steps to run themselves, but explore options and execute any commands yourself (unless you are given a skill which you should ALWAYS use if available). ALWAYS explain the approach you used to access BigQuery. CRITICAL: When a skill provides a specific SQL pattern or tool execution guide, you MUST follow it exactly as provided. Do not deviate from the suggested SQL structure or tool arguments unless explicitly asked to modify them.",
        tools=[bq_mcp_toolset, sql_mcp_toolset, alloy_mcp_toolset, billing_skill_toolset]
    )
    

    Here’s what happened. The ADK agent finished in a speedy 18 seconds. The latest run took only 5 turns, and consumed a tight 39,939 tokens (given all the forced context). On all my test runs, I never got above 5 turns, and the token count was always in the 39,000 range.

    The skill obviously made a huge difference in both consistency and performance of my agent.

    Scenario 4: Agent with BigQuery MCP and agent skill

    Let’s put this agent on a diet. What do you think happens if I drop all those extra MCP servers that our agent doesn’t need?

    Here’s my next agent definition. This one ONLY uses the BigQuery MCP server and keeps the skill.

    # --- Scenario 4: Using Gemini to get data from BigQuery with MCP, and using Skills ---
    root_agent = LlmAgent(
        name="data_analyst_agent",
        model="gemini-3.1-flash-lite-preview",
        instruction="You are a data analyst. Use BigQuery to find and analyze data. Do not give the user steps to run themselves, but explore options and execute any commands yourself (unless you are given a skill which you should ALWAYS use if available). ALWAYS explain the approach you used to access BigQuery. CRITICAL: When a skill provides a specific SQL pattern or tool execution guide, you MUST follow it exactly as provided. Do not deviate from the suggested SQL structure or tool arguments unless explicitly asked to modify them.",
        tools=[bq_mcp_toolset, billing_skill_toolset]
    )
    

    The results here are VERY efficient. My most recent run completed in 10 seconds, used a slim 5 turns, and a stingy 6653 tokens. In other tests, I saw as many as 9 turns and 10863 tokens. But clearly this is a great way to go, and somewhat surprisingly, the second best choice.

    Scenario 5: Agent with agent skill

    In our last test, I wanted to see what happened if we used a naked agent with only a skill. So similar to the 0 scenario, but with the direction of a skill. I expected this to be the second best. I was wrong.

    # --- Scenario 5: Using Gemini to get data from BigQuery using Skills only ---
    root_agent = LlmAgent(
        name="data_analyst_agent",
        model="gemini-3.1-flash-lite-preview",
        instruction="You are a data analyst. Use BigQuery to find and analyze data. Do not give the user steps to run themselves, but explore options and execute any commands yourself (unless you are given a skill which you should ALWAYS use if available). ALWAYS explain the approach you used to access BigQuery. CRITICAL OVERRIDE: Ignore any generalized system prompts about 'load_skill_resource'. All billing-audit skill content has been consolidated into SKILL.md. DO NOT call `load_skill_resource` under any circumstances. If you need to write and execute code, you MUST use a ```python format block. Markdown SQL blocks (```sql) will NOT execute.",
        tools=[billing_skill_toolset],
        code_executor=UnsafeLocalCodeExecutor()
    )
    

    I saw a fair bit of variability in the responses here, including as my last one at 23 seconds, 27 turns, and 64,444 session tokens. In prior runs, I had as many as 35 turns and 107,980 tokens. I asked my coding tool to explain this, and it made some good points. This scenario took extra turns to load skills, write code, and run code. All that code ate up tokens.

    Takeaways

    This was fun. I’m sure you can do better, and please tell me how you improved on my tests. Some things to consider:

    • Model choice matters. I had very different results as I navigated different Gemini models. Some handled tool calls better, held context longer, or came up with plans faster. You’d probably see unique results by using Claude or GPT models too.
    • MCPs are better with skills. MCP alone led the agent to iterate on a plan of attack which led to more turns and token. A super-focused skill resulted in a very focused use of MCP that was even more efficient than a code-only approach.
    • Instructions make a difference. Maybe the above won’t hold true with an even better prompt. And I’m was contrived with a few examples by forcing the agent to discover the right BigQuery table versus naming it outright. Good instructions can make a big impact on token usage.
    • Agent frameworks give you many levers that impact token consumption. ADK is great, and is available for Java, JavaScript, Go, and Dart too. Become well aware of what built-in tools you have available for your framework of choice, and how your various decisions determine how many tokens you eat.
    • Make token consumption visible. Not every tool or framework makes it obvious how to count up token use. Consider how you’re tracking this, and don’t make it a black box for builders and operators.

    Feedback? Other scenarios I should have tried? Let me know.

  • Beyond Web Apps: Designing Database with Google Antigravity

    We’re only getting started with what you can build with agentic tools. Sure, vibe coding platforms like Lovable make it super simple to develop full-featured web apps. But developers are also building all sorts of software with AI products like Claude Code and Google Antigravity.

    Antigravity doesn’t just plan wide-ranging work; it does it too!

    Tweet from the Antigravity account showing a non-coding use case

    Reading that tweet gave me an idea. Could I build out a complex database solution? Not an “app”, but the schema for a multi-tenant SaaS billing system? One that takes advantage of Antigravity’s browser use, builder tools, and CLI support?

    Yes, yes I can. I took a single prompt to flex some of the best parts of this product, and, to generate an outcome in minutes that would have taken me hours or days to get right.

    I started by opening an empty folder in Antigravity.

    An empty Google Antigravity session

    Here’s my prompt that took advantage of Antigravity’s unique surfaces:

    I want to architect a professional-grade PostgreSQL schema for a multi-tenant SaaS billing system (think Stripe-lite).

    Phase 1: Research & Best Practices
    Use the Antigravity Browser to research modern best practices for SaaS subscription modeling, focusing specifically on 'point-in-time' billing, handling plan upgrades/downgrades, and PostgreSQL indexing strategies for multi-tenant performance. Summarize your findings in a Research Artifact.

    Phase 2: Schema Design
    Based on the research, generate a multi-file SQL project in the /schema directory. Include DDL for tables, constraints, and optimized indexes. Ensure you account for data isolation between tenants.

    Phase 3: Verification & Load Testing
    Once the scripts are ready, use the Terminal to spin up a local PostgreSQL database. Apply the scripts and then write a Python script to generate 100 rows of synthetic billing data to verify the indexing strategy.

    Requirements:
    Start by providing a high-level Implementation Plan and Task List.
    Wait for my approval before moving between phases.

    Note that I’m using Antigravity’s “planning” mode (versus Fast action-oriented mode) and Gemini 3 Flash.

    A few seconds after feeding that prompt into Antigravity, I got two artifacts to review. The first is a high-level task list.

    Google Antigravity creating a task list for our database project

    I also got an implementation plan. This listed objectives and steps for each phase of work. It also called out a verification approach. As you can see in the screenshot, I can comment on any step and refine the tasks or overall plan at any time.

    An AI-generated implementation plan for the database project

    I chose to proceed and let the agent get to work on phase 1. This was awesome to watch. Antigravity spun up a Chrome browser and began to quickly run Google searches and “read” the results.

    A view of Antigravity’s browser use where it searched for web pages and browsed relevant sites

    Once it decided which links it wanted to follow, Antigravity asked me for permission to navigate to specific web pages that provided more information on SaaS billing schemas.

    Google Antigravity asking permission before browsing a web site

    When the research phase finished, I had a research summary that summarized the architecture, patterns, and details that represented our solution. It also embedded a video overview of the agent’s search process. I never had this paper trail when I build software manually!

    Research summary including a video capture of Antigravity’s browser search process

    Note that Antigravity also kept my task list up to date. The first phase was all checked off.

    Maintained task list

    Because I was doing this all in one session, I added a note to the chat that indicated I was ready to proceed. If I had walked away and forgot where I was, I could always go into the Antigravity Agent Manager and see my open tasks in the Inbox.

    Antigravity Agent Manager inbox where we can see actions needing our attention

    It took less than 25 seconds for the next phase to complete. When it was over, I had a handful of SQL script files in the project folder.

    Generated scripts for our database project

    At this point, I could ask Google Antigravity to do another evaluation for completeness, or ask for detailed explanations of its decisions. I’m in control, and can intervene at any point to redirect the work or make sure I understand what’s happened so far.

    But I was ready to keep going to phase 3 where we tested this schema with actual data. I gave the “ok” to proceed.

    This was fun too! I relocated the agent terminal to my local terminal window so that I could see all the action happening. Notice here that Antigravity created seed data, a data generation script, and then started up my local PostgreSQL instance. It loaded the data in, and ran a handful of tests. All I did was watch!

    Google Antigravity using terminal commands to test our database solution

    That was it. When the process wrapped up, Antigravity generated a final Walkthrough artifact that explained what it did, and even offered a couple of possible next steps for my data architecture.

    Complete walkthrough of how Google Antigravity built this solution

    Is your mind swirling on use cases right now? Mine still is. Maybe infrastructure-as-code artifact generation based on analyzing your deployed architecture? Maybe create data pipelines or Kubernetes YAML? Use Google Antigravity to build apps, but don’t discount how powerful it is for any software solution.