It’s unusually hot and humid in San Diego, but that didn’t deter us from being outside this weekend. But, during some air-conditioned indoor time, I wrote up a blog post. You can count on it being outdated in like three weeks as the next new thing comes along.
[blog] Beyond Vibe-Coding. Your prototype might actually turn into something. Here are some lessons from one such case.
[blog] Top AI Trends Every Developer Should Know in 2026. None of these are earth-shattering (if you’ve been paying close attention to the industry), but I liked this roundup and it’s a good look at what matters right now.
[blog] Understanding the Linux Kernel: Network Subsystem. I joke in customer meetings that this is exactly the sort of knowledge I’m now happy to forget. Higher abstractions have let me ignore it. But, it’s pretty cool to dip back down again and re-engage with it.
[blog] You have to beat the models at something. Right now, you’re better at LLMs in your familiarity of the tech details in the system in which you work, and at clear communication regarding that system.
I’m not proud of it, but I’ve been drunk on agent skills. It’s time to reset. It’s easy to fall into skills bloat as you accrue different ones for every possible scenario. Doing software engineering? Coding in Go? Performing security analysis? Add a skill! Nowadays, any of us can do basically anything. Maybe not well, but with agent skills, we get just enough confidence to try it. But we’re blowing tokens and confusing our agents with all this extra context. Plus, you only really need skills when there’s a specific (temporary?) gap in the LLM’s knowledge. Let’s be smarter. Can we do just-in-time discovery and lazy-loading of skills for our coding sessions?
Case 1: Preload skills globally or in your project
As a baseline, many of us default to installing skills ahead of time. It’s easy to grab skill files manually, or use something like the skills CLI to install into global or project directories.
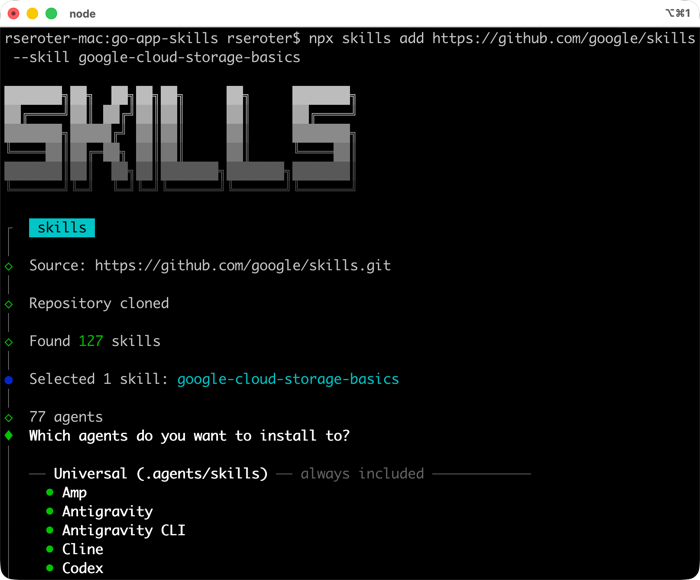
For instance, before starting my coding session, I could find and install a skill for working with Google Cloud Storage.
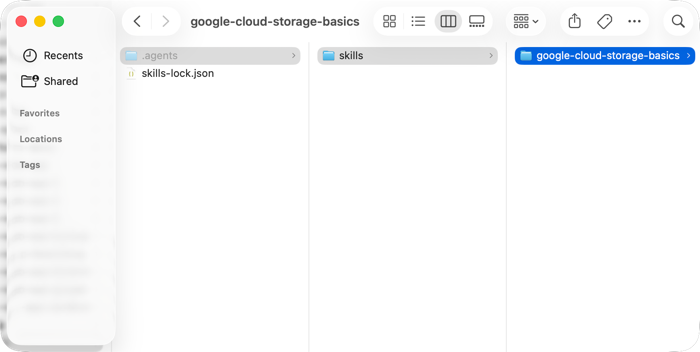
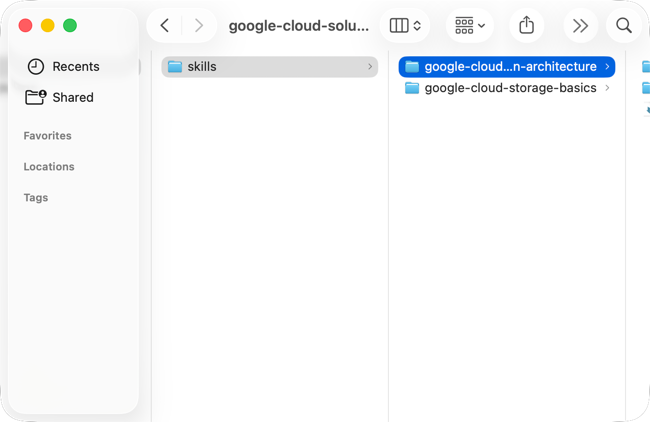
If I choose to install into my local project directory (instead of globally), I end up with these new files on disk.
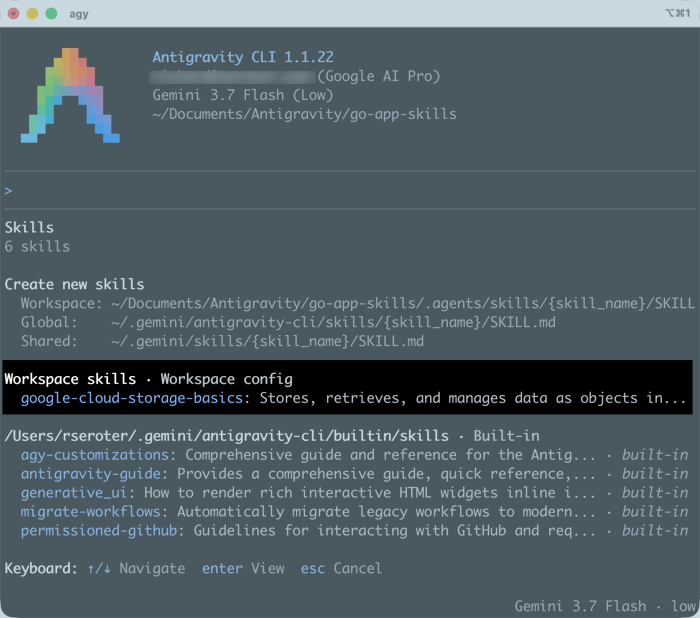
I’m using Google Antigravity here, but you’d expect to see this skill show up in whatever agentic tool you have. Both my Antigravity desktop app and CLI show this pre-existing skill.
To be sure, this is a perfectly valid way to work. But the front matter of EVERY skill comes into play in all your agentic coding turns. That gets hefty over time. You could choose to just pre-load or copy the “right” skills into your project before each session. But that assumes you know where you’re heading before every session. I sure don’t! Let’s look at more dynamic scenarios.
Case 2: Find known skills during a session and use them
Let’s consider a case where I know where the desired skills live on the internet, but I only want to grab them if I really need them.
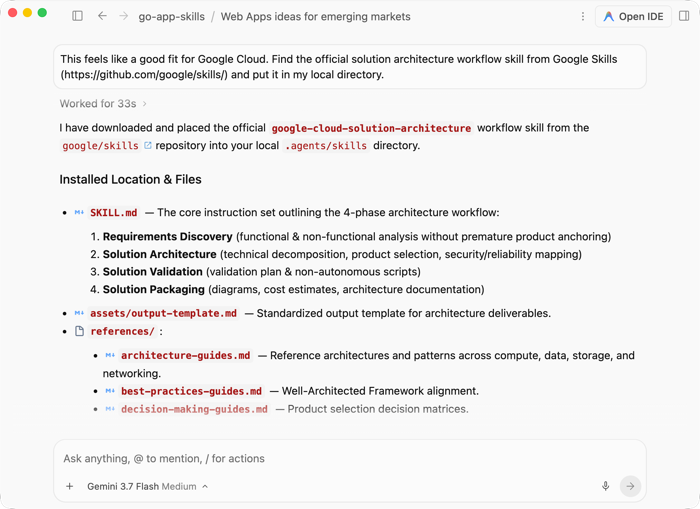
For example, maybe I use all sorts of clouds and pick the right one for the problem at hand. In my current coding session, I’m thinking through web app ideas, and landed on a fun concept for a fast-turnaround marketplace. Its bursty use and global footprint are great for Google Cloud. I need good guidance for picking the right architecture, so I asked Google Antigravity to find the right Google Skill to help out, and store it locally.
When this finished a few moments later, I had another skill in my local project directory.
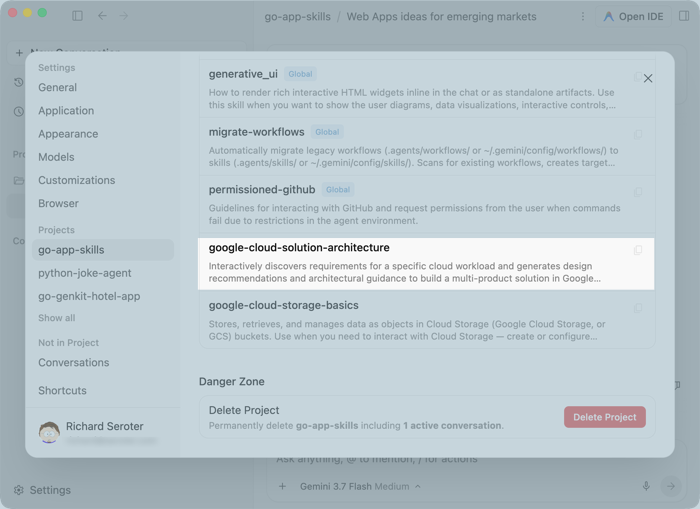
Most importantly, this skill is automatically active in this coding session. I can see that in Antigravity’s list of active skills.
My current session got better as I discovered and loaded agents on-the-fly. And these skills stay with this project and aren’t just part of the LLM (or coding session’s) temporary memory.
Case 3: Search for skills during a session and use them
The above case assumed that I knew the location of the skill I wanted. You need to be careful about loading random skills, but what if you wanted to search without knowing ahead of time where the most suitable skill was at?
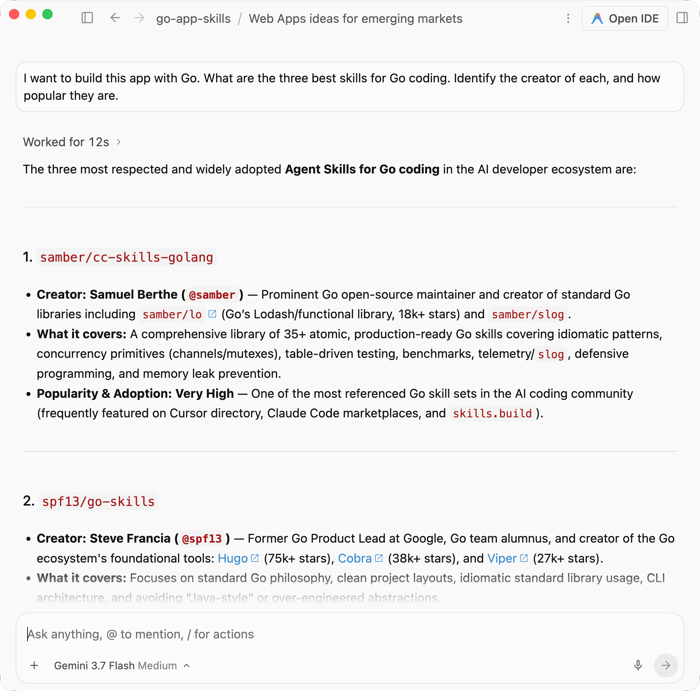
I continued my coding session by asking for the best skills for Go developers.
I know Steve (the creator of the 2nd of the 3 provided options) so I told Antigravity to load Steve’s skills. Sure enough, I got a handful of terrific Go skills installed into my project.
You don’t have to know skills or sources you want ahead of time. You can search for them during a session and keep going without ever breaking flow.
Case 4: Use a seed skill that grabs the “right” skill for the scenario
I’ve seen more of this pattern lately. You know you will need a set of related skills, but don’t know which ones, or when. A seed skill is your entry point that pulls the right skill at the right time. Addy’s Osmani’s agent skills do something like this. The “meta skill” routes you to the right skill for your situation. But it does require you to install all the skills (I believe).
Could you create a seed skill that acts as a lightweight entrypoint, and then just-in-time downloads the “right” skill from a pre-defined list? Sure you can.
Specifically, I want a skill that knows about all of the Google Cloud databases, but only retrieves the corresponding skill if our session demands it.
I used Antigravity to build it (in a different session) and here’s the gist (minus the scripts and references it also created).
---
name: gcp-database-seed-skill
description: >-
  Dynamic seed skill for Google Cloud database solutions. Use this skill when the user is designing,
  choosing, provisioning, migrating, or optimizing databases on Google Cloud (Cloud SQL for MySQL/PostgreSQL/SQL Server,
  AlloyDB for PostgreSQL, Cloud Spanner, Firestore, or Bigtable), or when well-architected cloud database guidance is needed.
  Automatically routes, downloads, and installs specialized skills from google/skills on demand.
---

# Google Cloud Database & Architecture Advisor (Seed Skill)

This seed skill provides a lightweight, progressive entrypoint for all database workloads on Google Cloud. Instead of loading bulky documentation upfront, it assesses workload requirements, recommends the optimal database solution, and dynamically downloads and installs specialized skills from the official [google/skills](https://github.com/google/skills) repository into your local workspace.

---

## Workflow & Step-by-Step Procedure

When invoked on a database-related prompt, follow this 4-step workflow:

```mermaid
flowchart LR
    Step1[1. Assess Workload] --> Step2[2. Determine Database & WAF Needs]
    Step2 --> Step3[3. Download & Install Skill]
    Step3 --> Step4[4. Execute Guided Solution]
```

### Step 1: Assess Workload Requirements
Evaluate the user's requirements against key architectural dimensions:
1. **Engine Compatibility**: Does the workload require MySQL, PostgreSQL, SQL Server, or open-standard ANSI SQL?
2. **Scalability & Scale**: Single-instance vertical scaling vs. distributed multi-node horizontal sharding?
3. **Availability & DR**: Regional HA (99.95% - 99.99%) vs. Global Multi-Region zero downtime (99.999%)?
4. **Workload Characteristics**: Standard OLTP vs. High-throughput HTAP with columnar queries vs. Vector/AI search vs. NoSQL?
5. **Migration vs. New Build**: Existing application lift-and-shift vs. greenfield cloud-native design?

> 📖 Consult the detailed [Database Decision Matrix](./references/database_decision_matrix.md) for complete comparison tables.

---

### Step 2: Select the Target Skills

Map the workload to the primary database skill and check for relevant **Well-Architected Framework** pillars:

#### A. Database Engine Selection
*   **Cloud SQL (`cloud-sql-basics` / `cloud-sql-mysql` / `cloud-sql-postgresql` / `cloud-sql-sqlserver`)**:
    *   *Select when:* Straightforward relational databases (MySQL, PostgreSQL, SQL Server), standard web apps, migration-friendly lift-and-shift via Database Migration Service (DMS).
*   **AlloyDB for PostgreSQL (`alloydb-basics` / `alloydb`)**:
    *   *Select when:* Demanding enterprise PostgreSQL workloads, up to 4x transactional performance, up to 100x faster analytical/HTAP queries with columnar engine, or in-database vector search (Vertex AI / ScaNN integration).
*   **Cloud Spanner (`spanner`)**:
    *   *Select when:* Mission-critical global databases, massive scale exceeding single-instance limits, synchronous multi-region replication, horizontal scaling, and 99.999% availability with zero downtime.
*   **Discovery / Undecided (`cloud-databases-onboarding`)**:
    *   *Select when:* User is unsure or needs interactive discovery across relational, NoSQL (Firestore, Bigtable), and analytical stores.

#### B. Well-Architected Framework Triggers
Check if cross-cutting architectural pillars should be retrieved:
*   **Reliability & HA:** Mentions of 99.999% SLA, DR, RTO/RPO, regional failover → Fetch `well-architected-reliability`.
*   **Security & IAM:** Questions about Private IP, PSA, CMEK encryption, or IAM DB auth → Fetch `google-cloud-recipe-auth`.
*   **Performance & Tuning:** Connection pooling, read replicas, latency optimization → Fetch `google-cloud-solution-architecture`.
*   **Cost Optimization:** Committed Use Discounts (CUDs), rightsizing, auto-pause → Fetch `google-cloud-solution-architecture`.

> 📖 Consult [Well-Architected Triggers](./references/well_architected_triggers.md) for full trigger criteria.

---

### Step 3: Download and Install the Specialized Skill

Execute the bundled installer helper to fetch the required skill(s) directly from `google/skills` into the workspace's `.agents/skills/` directory:

```bash
# Example: Install Cloud SQL basics
python3 scripts/install_gcp_skill.py --skill cloud-sql-basics

# Example: Install AlloyDB basics
python3 scripts/install_gcp_skill.py --skill alloydb-basics

# Example: Install Cloud Spanner
python3 scripts/install_gcp_skill.py --skill spanner

# Example: Install Well-Architected Reliability
python3 scripts/install_gcp_skill.py --skill well-architected-reliability

# Example: Install all core database skills
python3 scripts/install_gcp_skill.py --all-databases
```

*Alternative using npm/npx:*
```bash
npx skills add google/skills
```

---

### Step 4: Proceed with Implementation

Once the skill is installed into `.agents/skills/`, it is immediately available for subsequent operations.
1. Reference the newly installed `SKILL.md` in `.agents/skills/<skill-name>/`.
2. Provide concrete `gcloud` commands, Terraform/IaC snippets, or client library examples tailored to the user's selected database.
3. Verify connectivity (e.g. Cloud SQL Auth Proxy, IAM authentication, VPC Private Service Access).

---

## Reference Guides

*   [Database Decision Matrix](./references/database_decision_matrix.md): Deep-dive comparison between Cloud SQL, AlloyDB, Spanner, Firestore, and Bigtable.
*   [Well-Architected Framework Triggers](./references/well_architected_triggers.md): Detailed rules for triggering security, reliability, performance, cost, and operational pillars.
*   [Known Skills Catalog](./references/known_skills_catalog.md): Complete list of remote paths and metadata in `google/skills`.
*   [Prompt Routing Scenarios & Examples](./examples/prompt_routing_scenarios.md): Real-world examples of user requests and the exact skills retrieved.
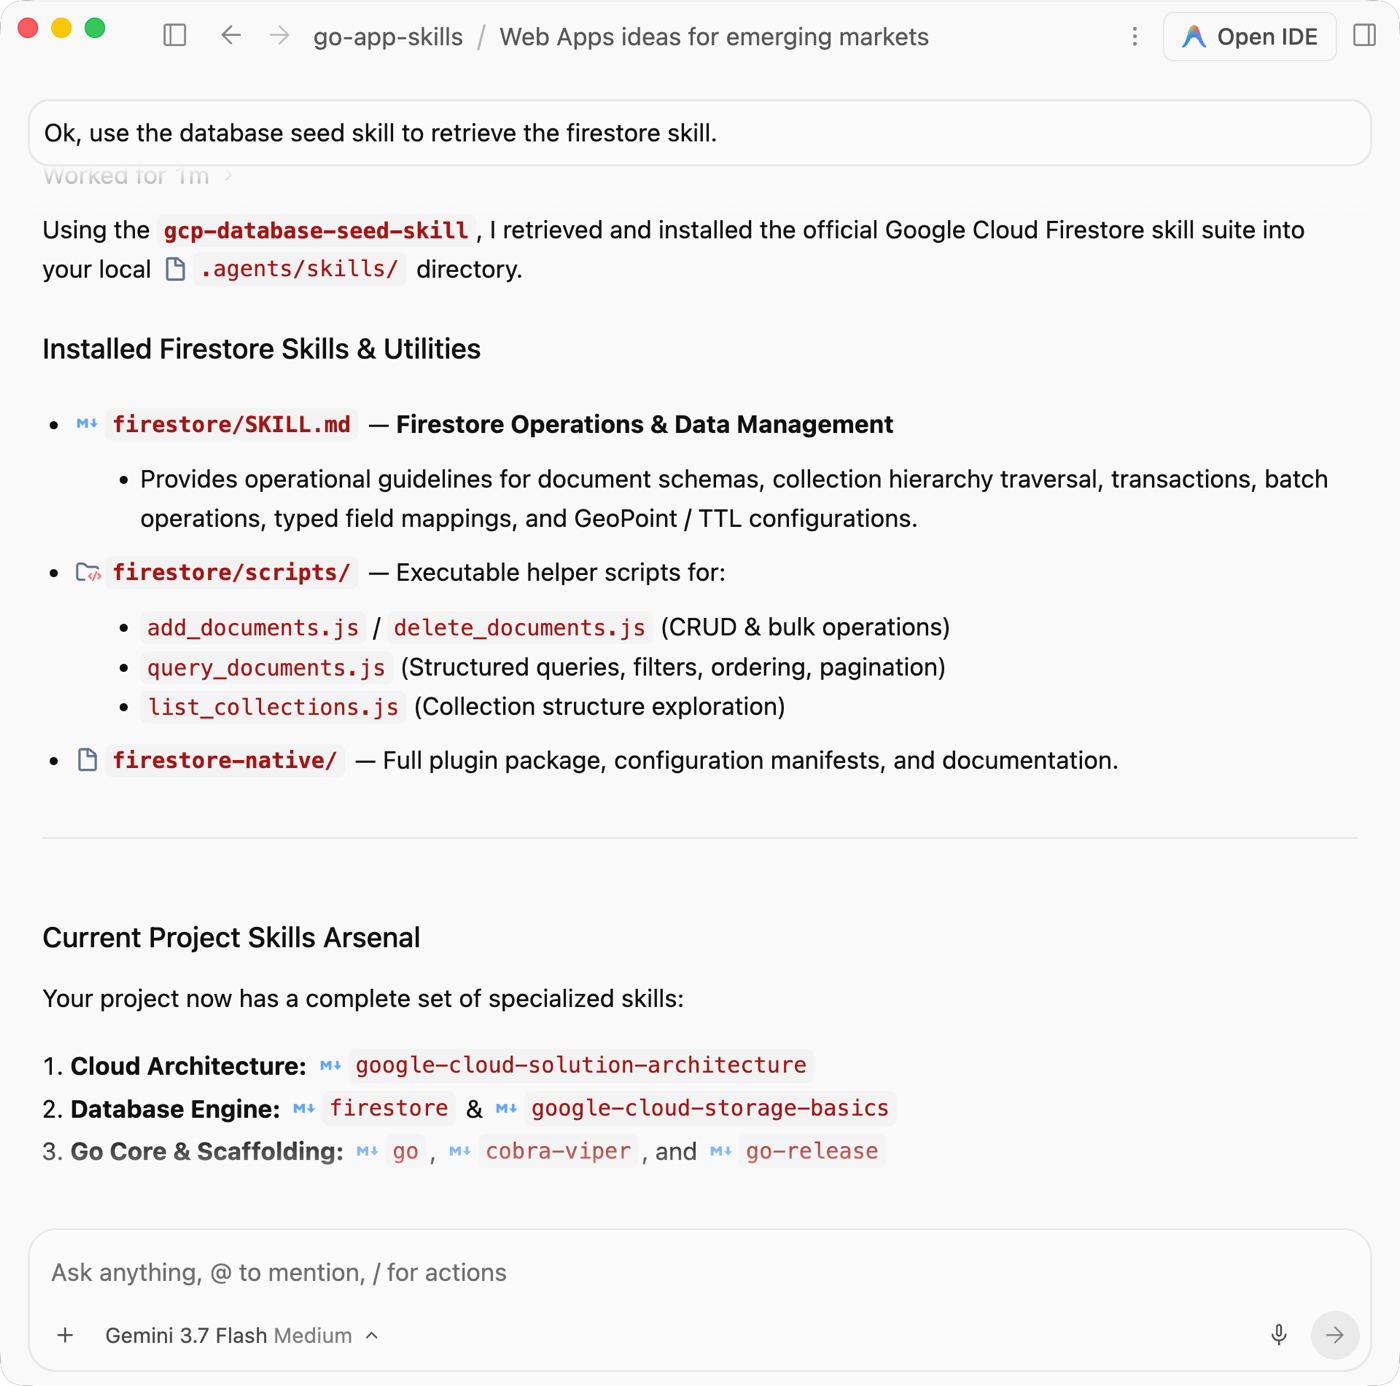
After adding this seed skill to my current coding session, I started up a database conversation regarding my app idea. We landed on Firestore as the best choice, so I asked the seed skill to retrieve only the Firestore skill.
Here, I didn’t need to download or pre-load all the possible Google Cloud database skills. There’s a lot of them. I only got the one I needed for this particular coding session. Seems cleaner?
A word about MCPs
If your skills make use of remote or local MCP servers, circumstances are different. While MCP now supports a stateless interaction pattern, most existing MCP servers don’t. When your coding session starts, there’s a handshake that happens. This means that if you introduce a new MCP during a session (in your mcp_config.json), you likely have to fork your current session, or start a new one. My tests showed this to be the case most of the time, but your mileage may vary.
I mention this because you could see skills that make heavy use of managed MCPs. That’s cool, but downloading those skills on the fly might mean they only partially work because your coding harness can’t “see” the referenced MCP server. Just be cautious!
We’re seeing an emerging “open knowledge layer” consisting of MCPs, skills, and plugins. I’d imagine we will see patterns evolve for how and when to use each component. What do you think of this lazy loading pattern I demonstrated here?
Happy Friday. I’m at inbox zero, and hoping for a fun weekend with the family. And might write a blog post if the stars align.
[blog] Teamwork: When AI Becomes a Research Partner. This is outstanding. I liked the deep dive into the patterns this tool applies to agent teams. And the results are impressive.
[blog] Dynamic capacity management for AI infrastructure. Now isn’t the time to commit to a ton of fixed infrastructure. Who knows what you’ll need in six months, let alone two years. Here’s a good post on embracing a more fluid foundation.
[blog] Simplify your resilience testing strategy with Fault Injection Testing. How you feeling about your disaster recovery plans? Tested them in a while? What about when you’ve got many workloads in a public cloud? Here’s a new way to simulate meaningful failures to see how your automated resilience handles it.
[blog] Friday Forward – Expert Silence. We’re all wrong—yes, even “experts”—all the time. It’s completely normal. But be smart enough to acknowledge new facts when more information comes in.
[blog] Unlock Antigravity 2.0: Logins, Plans, Cost, and Quota. Getting started with new tools can be intimidating, especially when you have a handful of initial choices to make. Alexis breaks this down in a very understandable way.
One theme that emerged from today’s reading list? “Are you ready for AI.” Is your data ready? Your APIs? Your backlog? User experience? Your people? If you say “yes” to all of those, you’re a unicorn and I’m very impressed.
[blog] Piloting the world’s first double-blind AI evaluations. At this point, I assume that models are trained to create great “pelican on a bicycle” images given how much that little test is talked about online. You need a way to eval where models haven’t already seen the test questions. Here it is.
[blog] The Backlog Was a Coping Mechanism. Good post. I was taught “now, next, or never” for incoming requests and to avoid a bloated backlog that we’d never get to. Some of those considerations change further, as Allen identifies here.
[blog] Generic Methods. Go developers have very strong emotions about this one. Many love, a few hate. It’s ok. I’m happy that devs push us to keep Go straightforward to write and read.
[blog] Deploy personal AI agents with Cloud Run instances. This fills a specific need. You’ve got an always-on component, but want a fully managed runtime. These new instances are ideal for OpenClaw, Hermes, or whatever continuous and stateful workload you got.
[blog] Five monetization trends from global pricing leaders. Is your favorite tool seemingly switching up its pricing model more often? You’re not imagining things. Here’s what happening in the world of software pricing.
[blog] How Flutter stays ahead of iOS releases. If you build a product on top of a platform, you have to figure out how to be ready for each major platform release.
I’m in Sunnyvale at Google Cloud HQ today and tomorrow. On the flight up, I finally got my generative UI service working properly in Gemini Enterprise. There are few things more satisfying that having an idea and then seeing it come to life with software.
[article] Can “Predictable Delivery” be measured? Interesting question. Two teams could have wildly different output per sprint, but have the same throughput over time.
[article] The AI-Native SDLC playbook. Fascinating writeup from Anthropic where they explore the SLDC stages with AI-lens. Same “work” but done very differently.
[blog] Deploy your App Engine apps to Cloud Run in a single command. When people find a stack they like, it’s hard to get them to switch! 15+ years after launching it, we still have a hearty customer base. This post shows the one-line command to switch over to the more modern Cloud Run.
[article] Not every problem needs an AI agent. Blasphemy, I know. Valid points here, but I also wonder if the box the author puts AI into will quickly dissolve.
Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:
In between meetings, I had a chance to refresh some demos ahead of a customer presentation this week. And, to iterate for a while (too long) getting a generative UI agent to give me a custom interface in Gemini Enterprise. I’m glad my coding harness doesn’t get frustrated as quickly as I do.
[article] 20 Lessons From 20+ Years in Tech. Really good. We need to be reminded of these lessons, and be more intentional about how we go about our professional lives.
[blog] The Case for Software Craftsmanship in the Era of Vibes. Sure does. Regardless of what you may see, “software” isn’t solved just because of AI. There’s a lot that goes into system design, product thinking, and building high quality software that matters.
[blog] Three Clouds, Three Native Agents. A telling effort. William looks at coordinating agents across the three major hyperscalers.
[blog] How to Evaluate Live & Voice Agents in ADK. I’m sure there are solutions out there, but I haven’t seen them. This is a great way to test live/voice agents and prove they follow the desired path.
Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:
I ended up with some open time today to build, which felt good. Maybe some more this weekend, but the weather might be too nice to stay inside. Good thing I now have Antigravity Remote Control 🙂
[blog] Antigravity Anywhere with Remote Control. So awesome. Now I can access my machines running Antigravity from anywhere. It’s got full awareness of my projects and local context, and I can do most anything from the web interface.
[article] This post will save you tokens. I would behave differently if I was paying for all my tokens right now. Including following some of this advice.
[blog] Good writing is obvious, not original. Just write clearly; that’ll stand out more than trying to for originality at every moment. And share things that are obvious to you, but maybe not others.
[blog] Bringing Primary Constructors to Dart. Yes, new language features matter, even in the AI-writes-all-the-code era. Easier readability is still important.
[blog] Inside Android Skills – Built for deprecation. I’ve got strong opinions loosely held regarding skills. Useful, yes. But a new type of durable documentation? I don’t think so. I’m more aligned with this post’s POV.
I’m adding things to my “you should try this technology” list much faster than I’m getting through it. At some point I’m going to declare bankruptcy and start over. Tomorrow’s looking like a clean “no meeting day” so I stand a chance to get through two of my top ones. Stay tuned.
[blog] Practical Loop Engineering. Educational post on the type of agent loops, and how Addy applies them in his own work.
[blog] Add telemetry and observability to your AI agents. Does it really make a big difference to give your agent a memory? Jason built a reference system to test it out and see how behaviors diverge over time.
[article] Is Your Organizational Culture Too Nice? You know what this looks like. Bland feedback. Everyone gets great performance reviews. Everyone gets a voice. Stop that. Care deeply about others, while aiming for candid, results-focused kindness instead.