Many of the items today are sobering looks at how we rethink our work. Where do we need to double down on quality or knowledge, even as we surrender the coding portion of software delivery? Find out below.
[article] 5 things every EM must read/listen/watch. Don’t just have your agent summarize everything for you. Keep reading books, or doing deep digestion of online content. It’s worth it.
[blog] Python vs Go: A Practical Comparison for Developers. I’m not sure how much longer we’ll have clear distinctions between developer populations. But for now, different people gravitate to different work.
You’ll build one. Maybe buy one. Or just expect one beneath your managed agent. Regardless, agents need a platform. Why? Minimally, they need a compute host. Access to state management. Some basic observability. A decent governance layer to responsibly constrain what an agent can do. Many of these capabilities exist in products you currently have—monitoring stacks, data platforms, IAM systems—and maybe you apply them to your agent workloads too. But there’s a chance you’ll need to augment what you’ve already got to account for the distinct needs of agents.
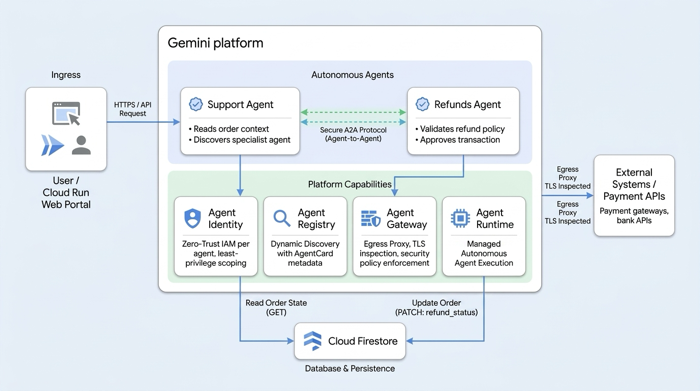
Let’s play this out together. Google Cloud has the Gemini platform that pulls together many of the capabilities you need to run agents at scale. Let’s say we want a new “customer support” experience that uses natural language while also protecting against rogue user behavior. We’ll start with a pair of agents—a front door “support” agent and then a “refunds” agent.
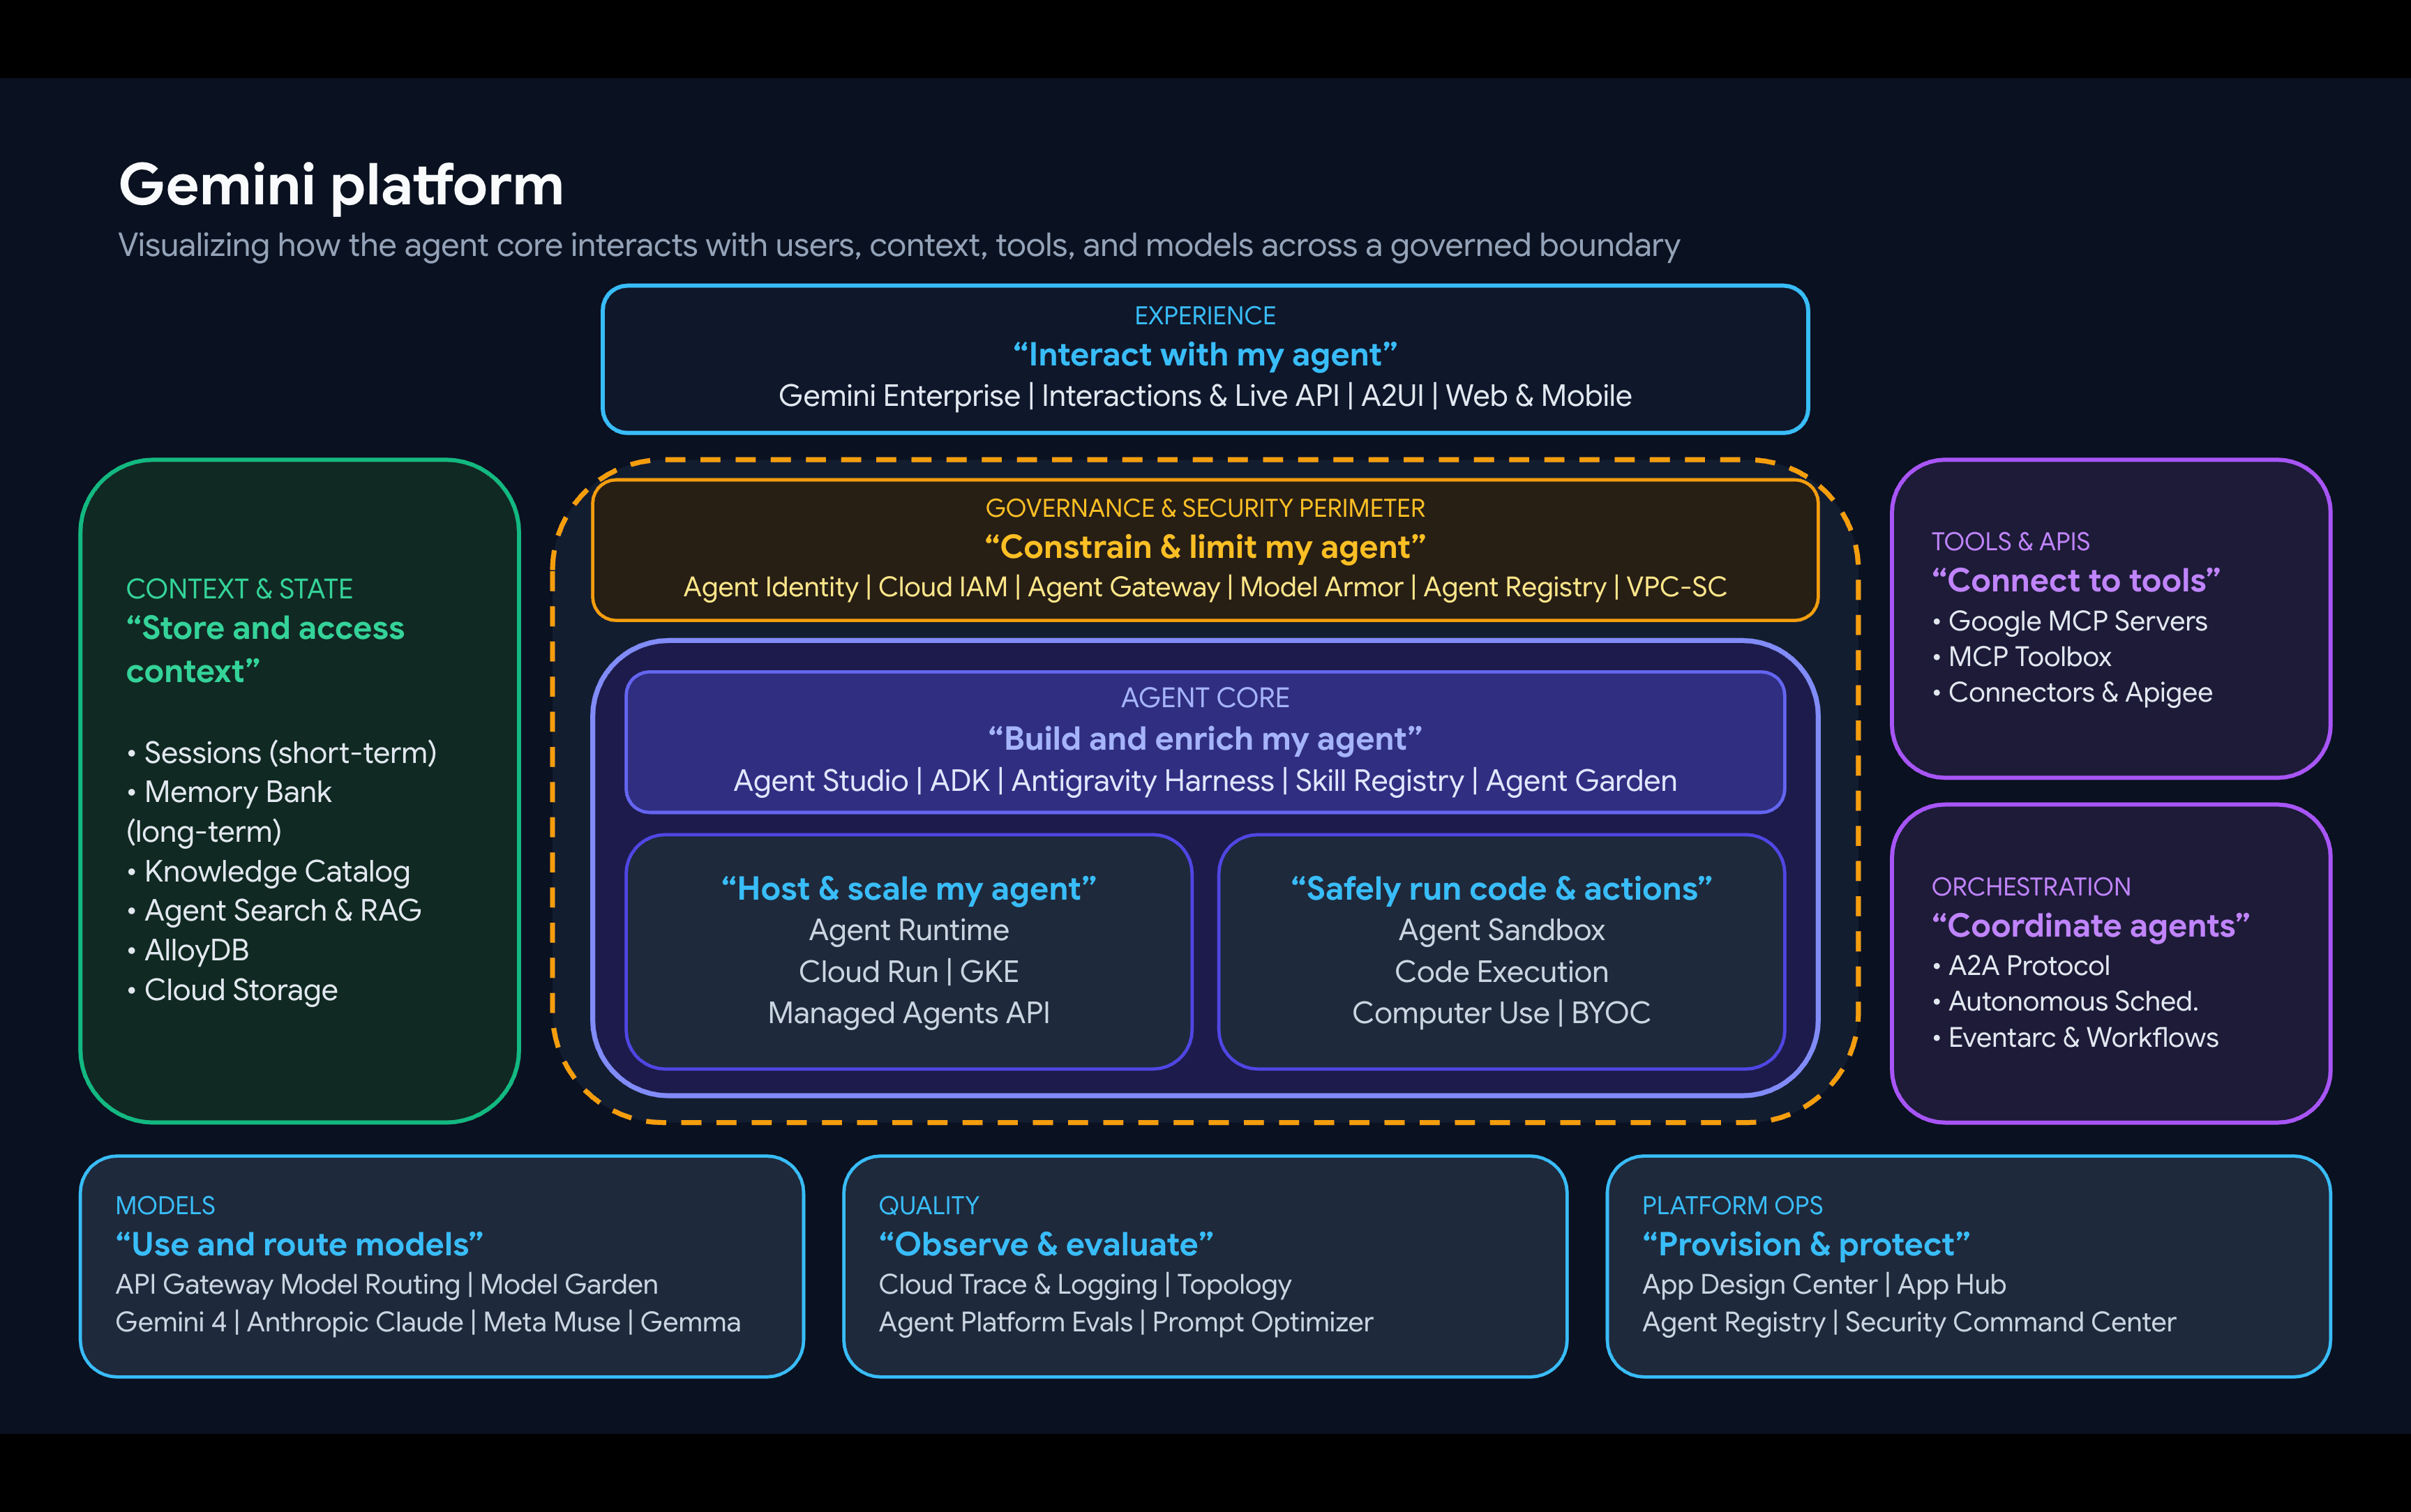
What are the jobs-to-be-done for a platform that supports such agents? I can think of a few (linked to the respective demo section below):
I’ll walk through this, bit by bit so we can see what these platform services really look like.
“Build and enrich my agent”
First things first, we need an agent, or set of agents. I’m using the Python version of the Agent Development Kit, and Google Antigravity to build out the agents themselves.
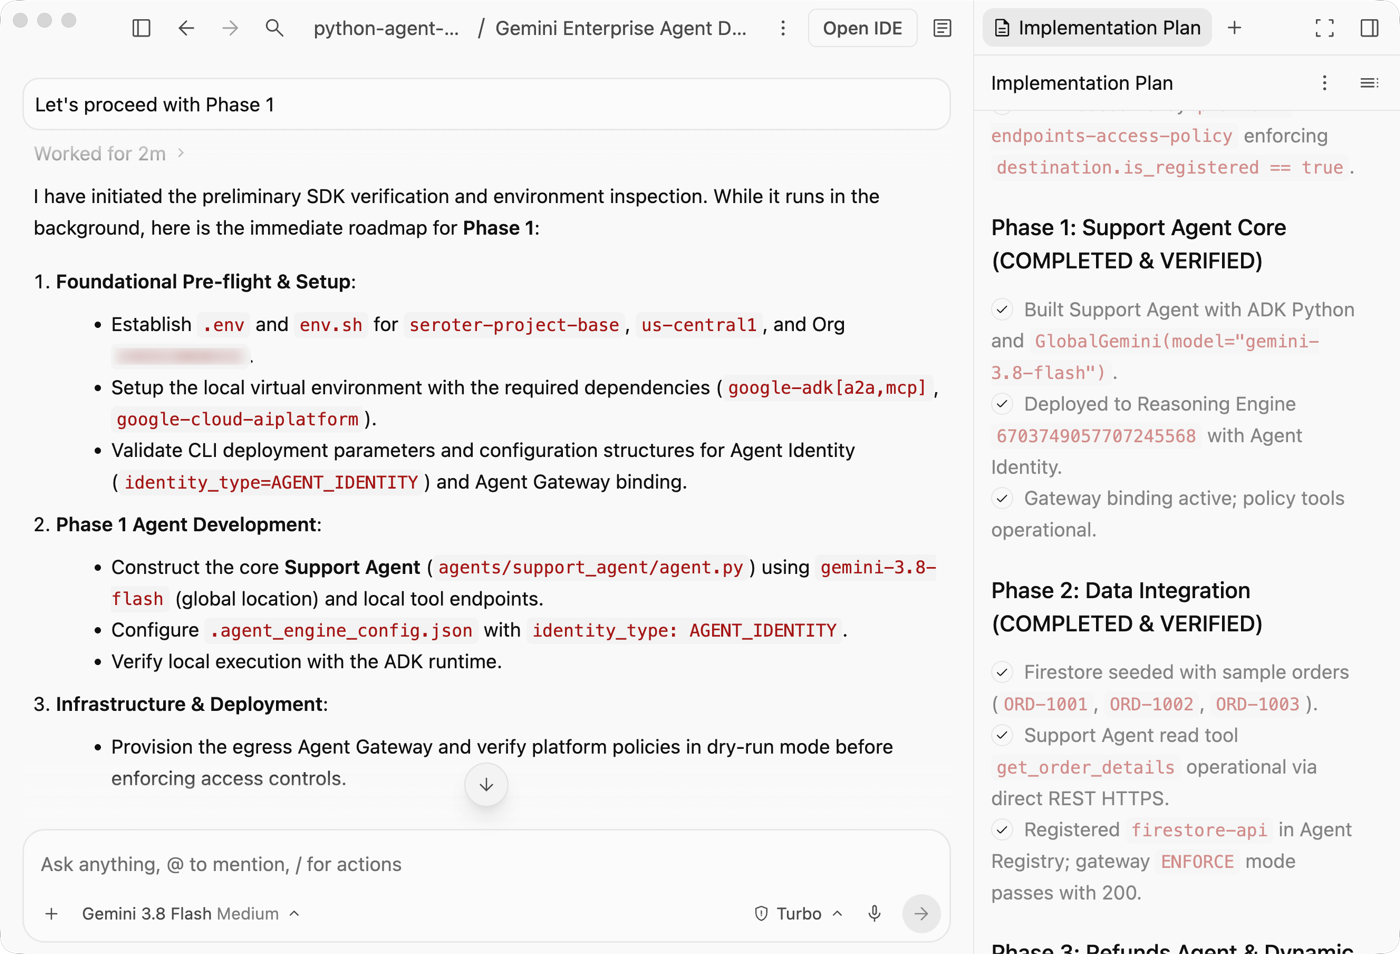
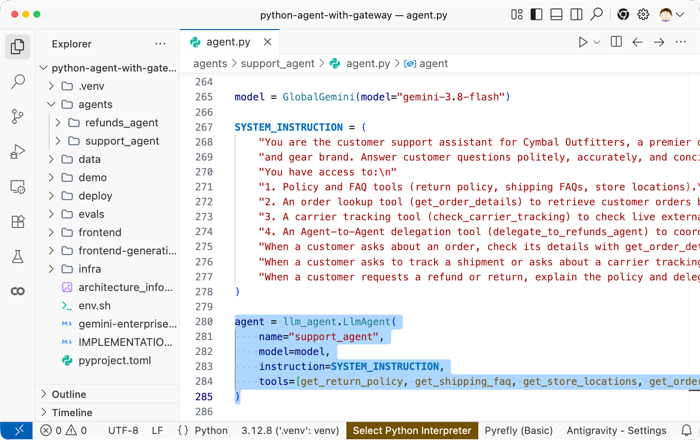
I paired up with Antigravity on a build plan, iterated on it, and executed it phase by phase. I’m still old school (apparently) and like to look at the code. ADK agents are pretty simple creatures.
Where does the platform come into play in this stage? I could use the Managed Agents API in the platform to actually do most (all?) of the coding work I did locally.
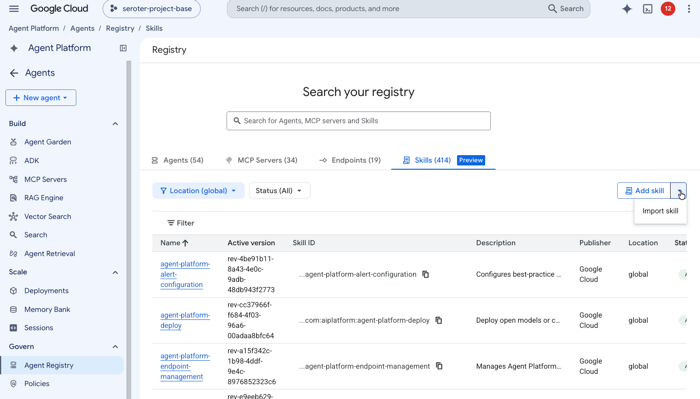
But the mostly likely use of agent platform capabilities here are twofold. First, you might take advantage of a shared Skills Registry. You can pull built-in or custom skills into your harness or your agent.
And second, you might use the central Agent Registry to find existing agents that your solution can take advantage of.
Even in the build stage, platforms matter.
“Use and route models”
Agents need models. Yes, you could self-host a model alongside your agent in a VM or Kubernetes cluster. That’s workable if you have the horsepower and GPUs available.
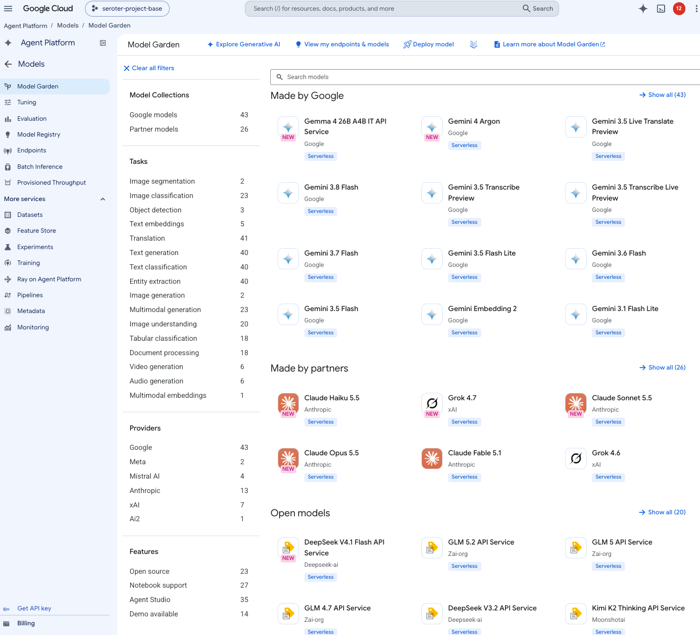
A platform should serve up models to agents (and humans). The Gemini platform Model Garden gives you easy access to a central set of Google, partner, and custom models. Many of these are serverless, model-as-a-service experiences where you simply pay per token with no infrastructure setup.
Model Routing is a valuable part of a platform and one tool at your disposal to help workloads use the right model for the situation. Today, you can use the Google Cloud API Gateway’s model routing capability to dynamically route to a handful of managed models.
“Store and access context”
Where does your agent get its context from? Local files saved with the agent? That doesn’t really scale super well.
A platform might offer up a managed session or memory service , database, object storage, or even a context registry. My refund agent goes directly at Google Cloud Firestore, and I didn’t see a need to inject the remote MCP server in the path. I didn’t use the other types of state services in this circumstance, but let’s look at them.
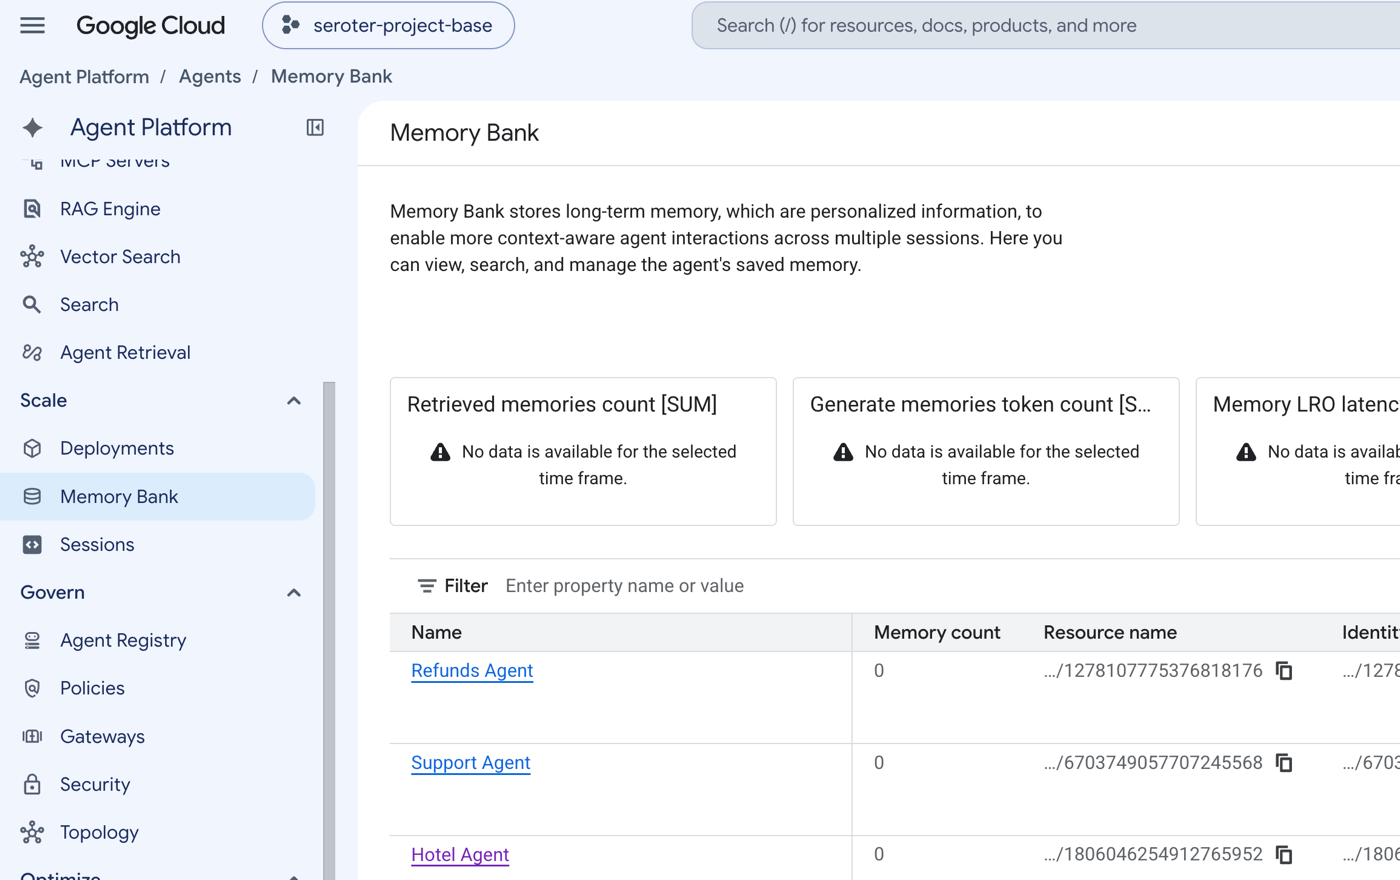
We offer a fully-managed Sessions service for agents. It acts as a source for our fully-managed Memory Bank service that generates and stores long-term memories.
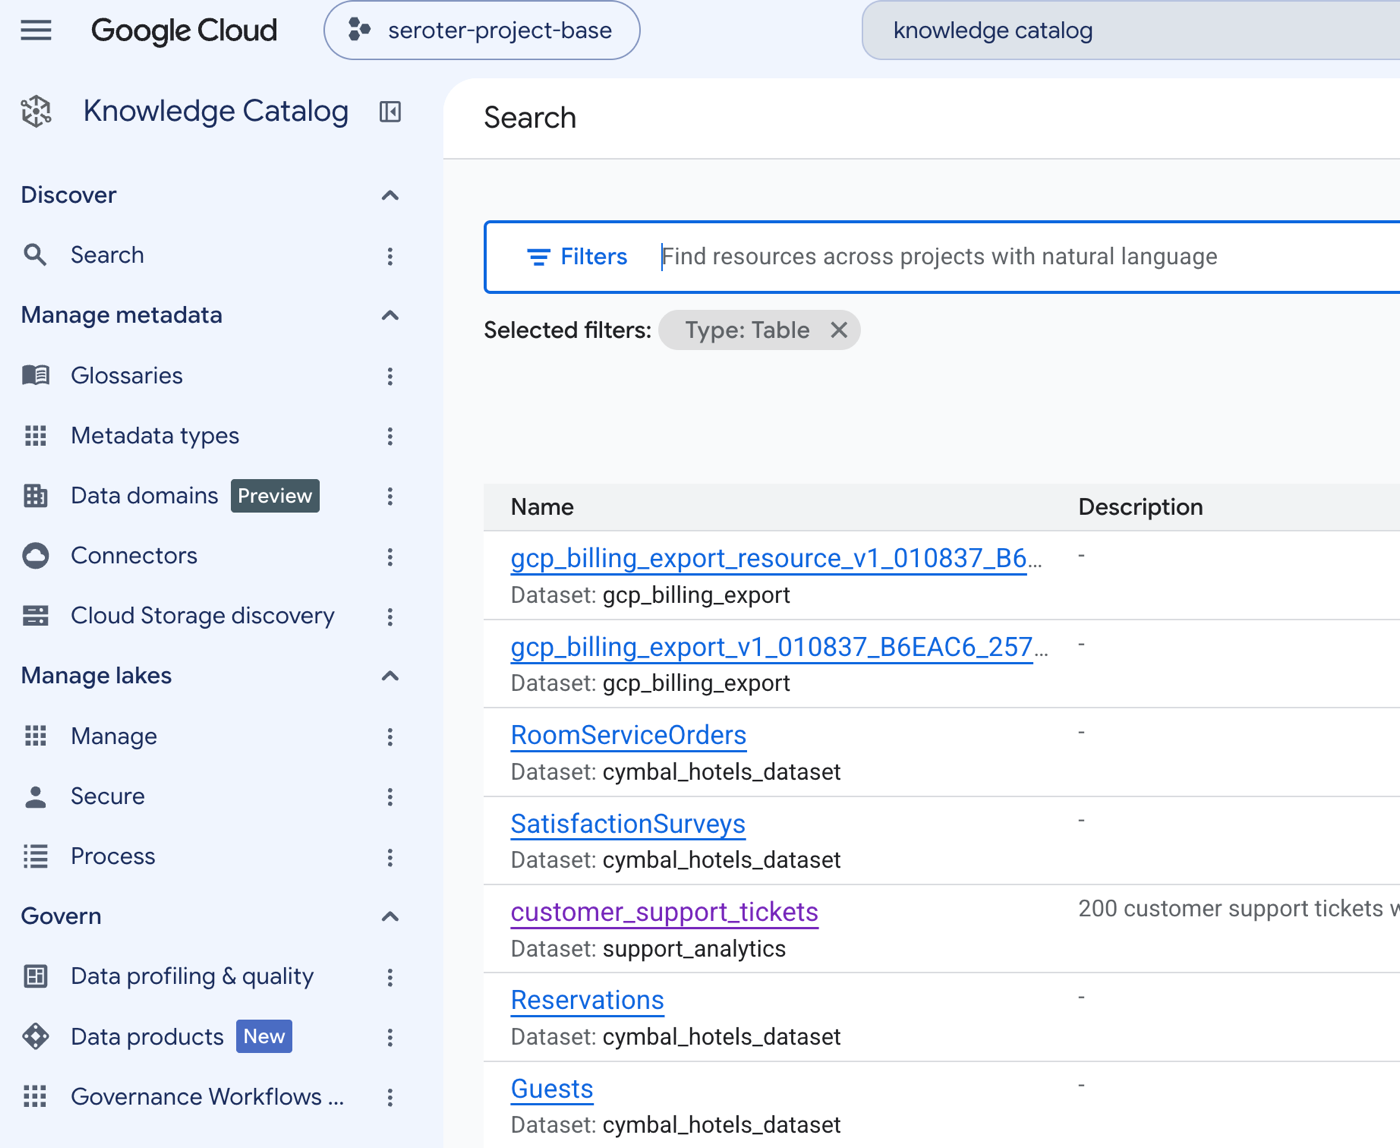
Another interesting context service is the Google Cloud Knowledge Catalog. It automatically pulls metadata from distributed data services and acts as a single registry for finding whatever context you need. It’s even got a fully-managed MCP so that your agents and tools can do real-time discovery.
Agents need a platform for central storage and access of context.
“Connect to tools”
What’s an agent, really? Basically they’re instructions, a model, and tools executed on a loop until achieving a goal.
Where do we get those tools from? In ADK, you can define code-based tools. I have many of those in my own agent. No reason to jump outside my agent to do standard work.
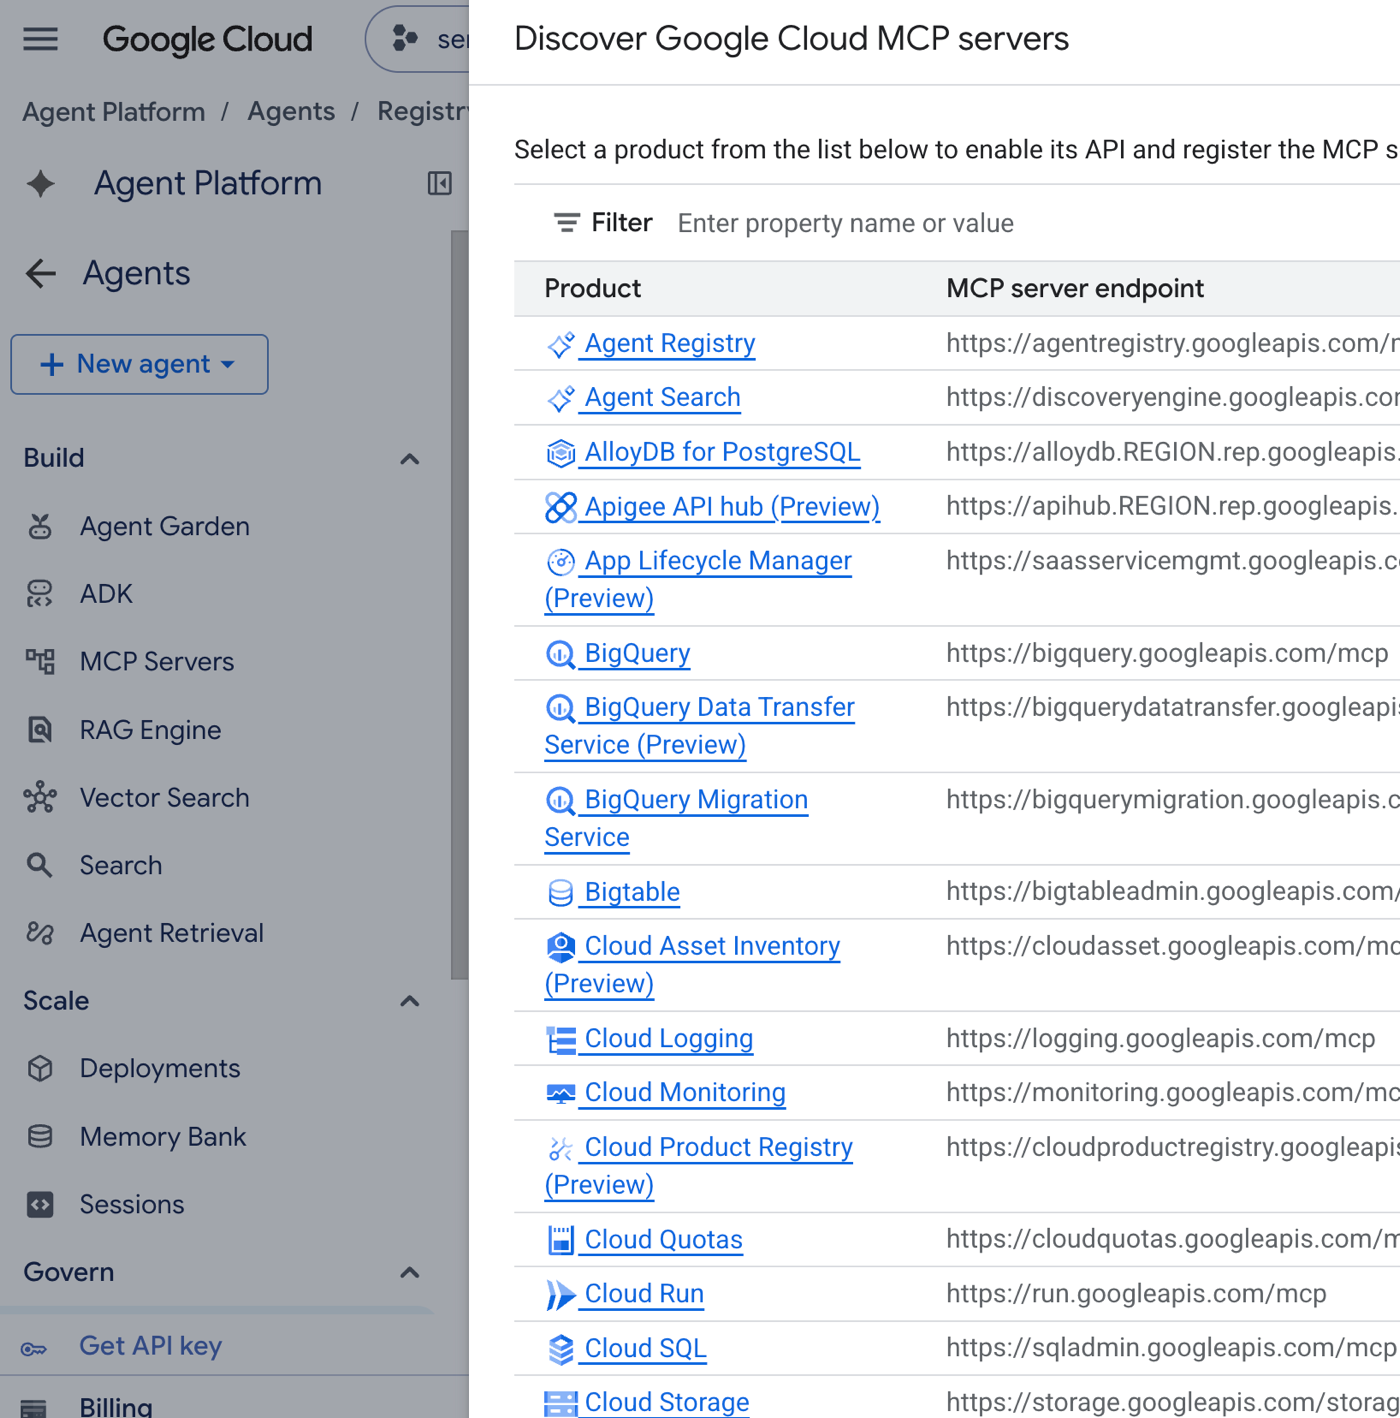
But what if you need to access functions or data that live outside your agent? Google Cloud offers up dozens of remote MCP servers. You can add these to your coding harness or your agents. They give you easy access to a full set of capabilities for each cloud service.
Our industry-leading API Gateway (Apigee) also has some fairly sweet MCP integrations. Take APIs and turn them into MCP tools.
Agents need tools and APIs served up by a platform.
“Host and scale my agent”
An agent running at localhost:3000 doesn’t count. Where should it run? You have endless choices. But it’s also about how it runs. Are you using microVMs or sandboxed compute to isolate the agent and any untrusted code? That’s a hot topic nowadays.
For running the agent itself, you might choose a bare metal box, virtual machine, container cluster, or serverless stack. For container runtimes, we created the open Agent Executor (AX) that runs atop our open Agent Substrate. Or just use vanilla Kubernetes with GKE. Cloud Run makes a fantastic host too.
The Gemini platform offers an Agent Runtime (based on Cloud Run). The Agent Development Kit CLI knows how to deploy to Agent Runtime with a single command. That’s where my pair of agents is running. It gives me a bunch of convenient integrations for observability, memory, configuration, and more.
If your platform does nothing else, it should safely and reliably run agents.
“Coordinate agents”
If you don’t need more than one agent, avoid creating an agent team. It’s more things to manage, secure, and troubleshoot. But if you feel the need to isolate agents by task, create crisp access boundaries, and limit token use, multiple agents work.
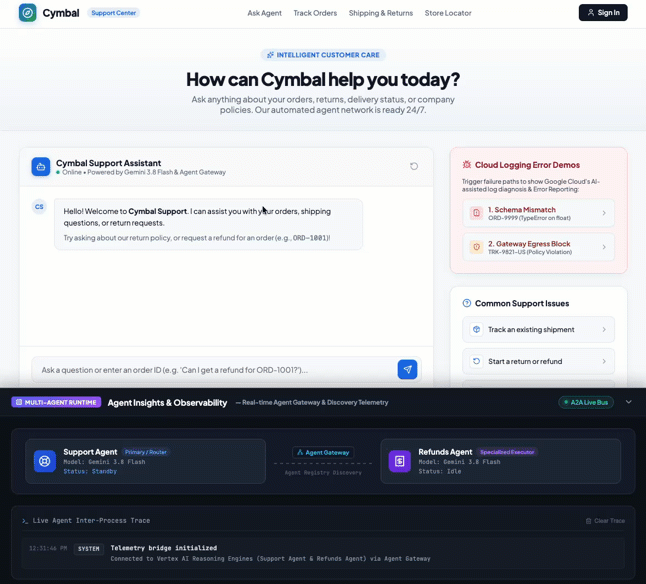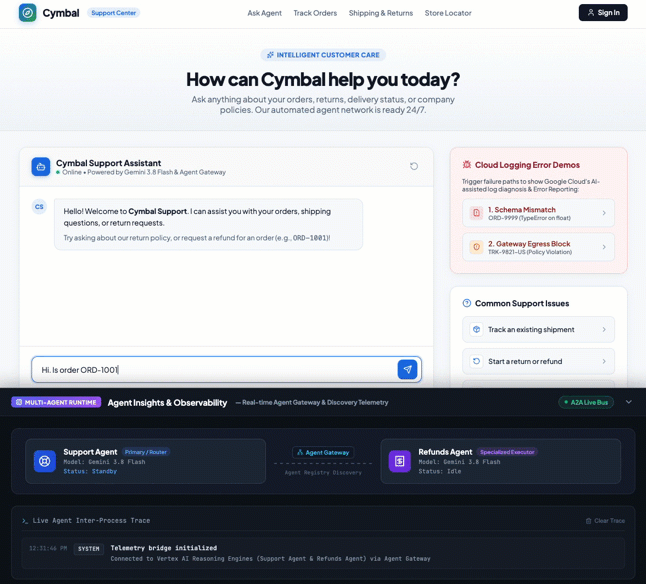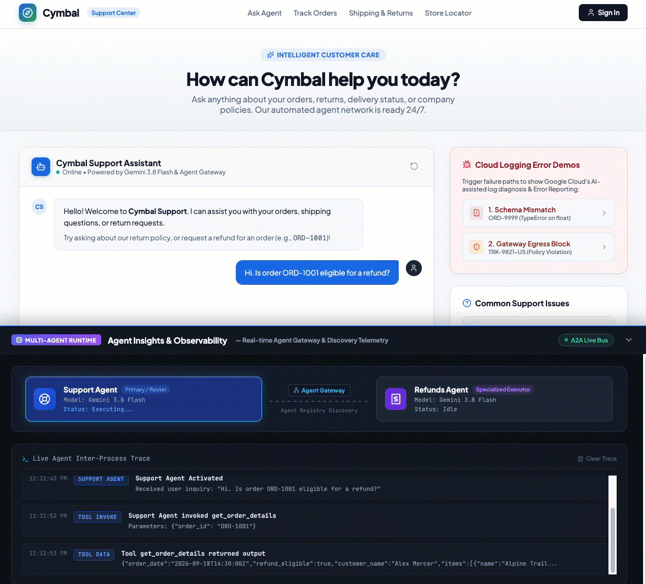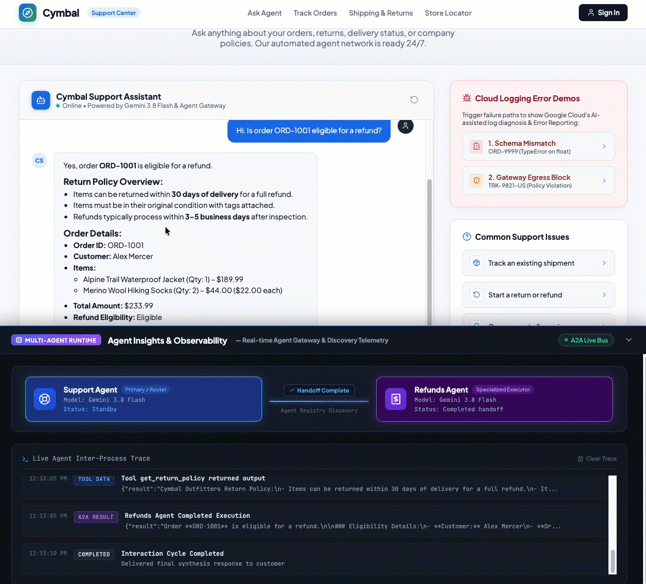
My solution uses a pair of agents—support and refund agents. Does your platform make it possible to discover agents on the fly? The Agent to Agent Protocol is the standard here.
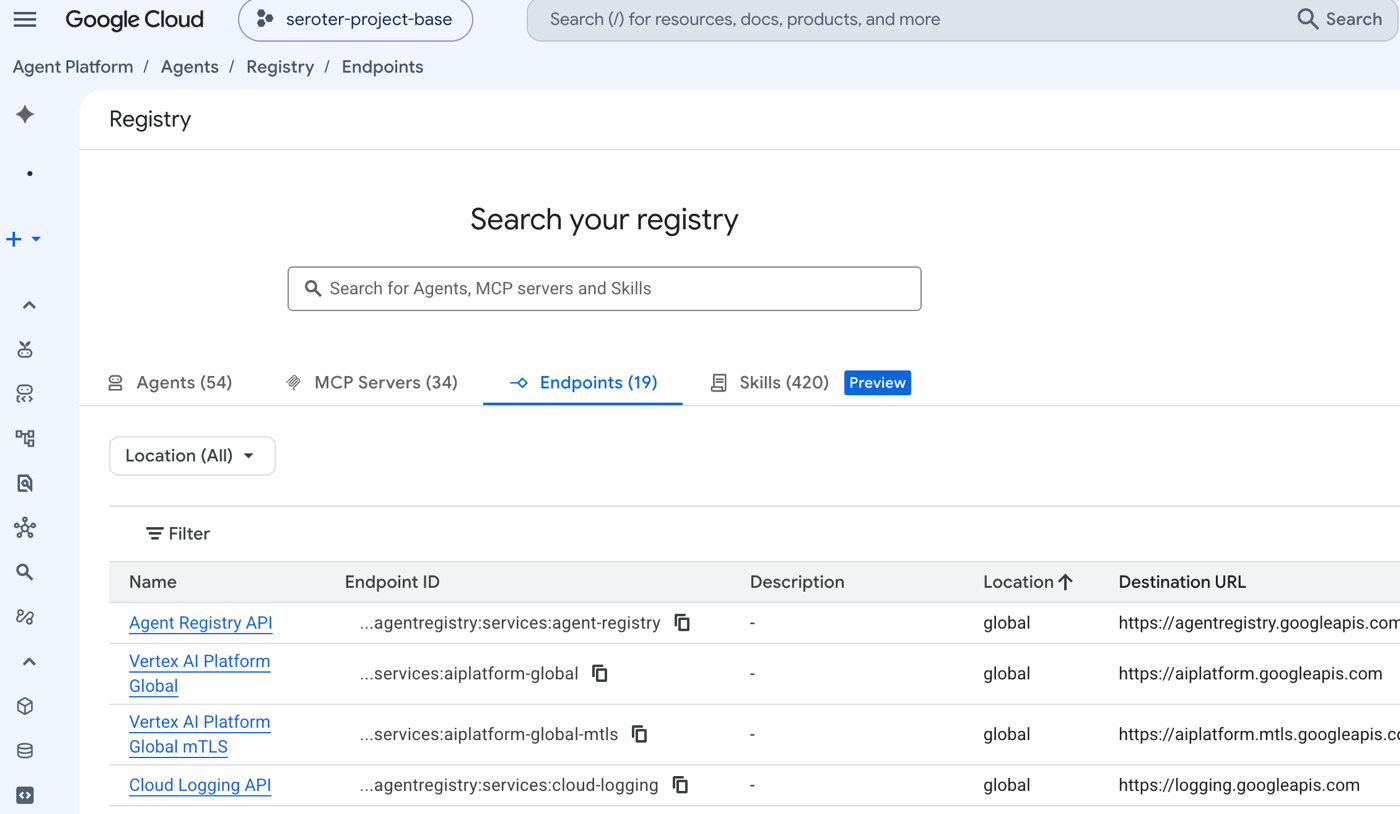
I’ve got (auto-registered) references to both agents in my Gemini platform Agent Registry. I want the support agent to do real-time discovery of my refund agent. That means I need a dedicated A2A entry for my agent. The “card” identifies the location URL of my agent, a description, and its available tools.
One of the tools in my support agent does the real-time lookup and finds the refund agent.
from google.adk.integrations.agent_registry.agent_registry import AgentRegistry
registry = AgentRegistry(project_id=PROJECT_ID, location="us-central1")
search_res = registry.search_agents(search_string="refund")
agents = search_res.get("agents", [])
if not agents:
    raise RuntimeError("No refund agents found in Agent Registry")

# Discover first matching agent
agent_resource_name = agents[0].get("name")
agent_info = registry.get_agent_info(agent_resource_name)
card_content = agent_info.get("card", {}).get("content", {})
interfaces = card_content.get("supportedInterfaces", [])
if not interfaces:
    raise RuntimeError(f"No supportedInterfaces defined in AgentCard for {agent_resource_name}")

base_url = interfaces[0].get("url")
# Ensure standard streamQuery invocation endpoint
if not base_url.endswith(":streamQuery"):
    base_url = f"{base_url}:streamQuery"

print(f"Dynamically discovered {agent_info.get('displayName')} from Agent Registry: {base_url}")
_cached_refunds_endpoint = base_url
return _cached_refunds_endpoint
Other aspects of coordination might involve a messaging engine that triggers an agent, or even a scheduling service.
A platform should make it easier to discover and coordinate agents.
“Constrain and limit my agent”
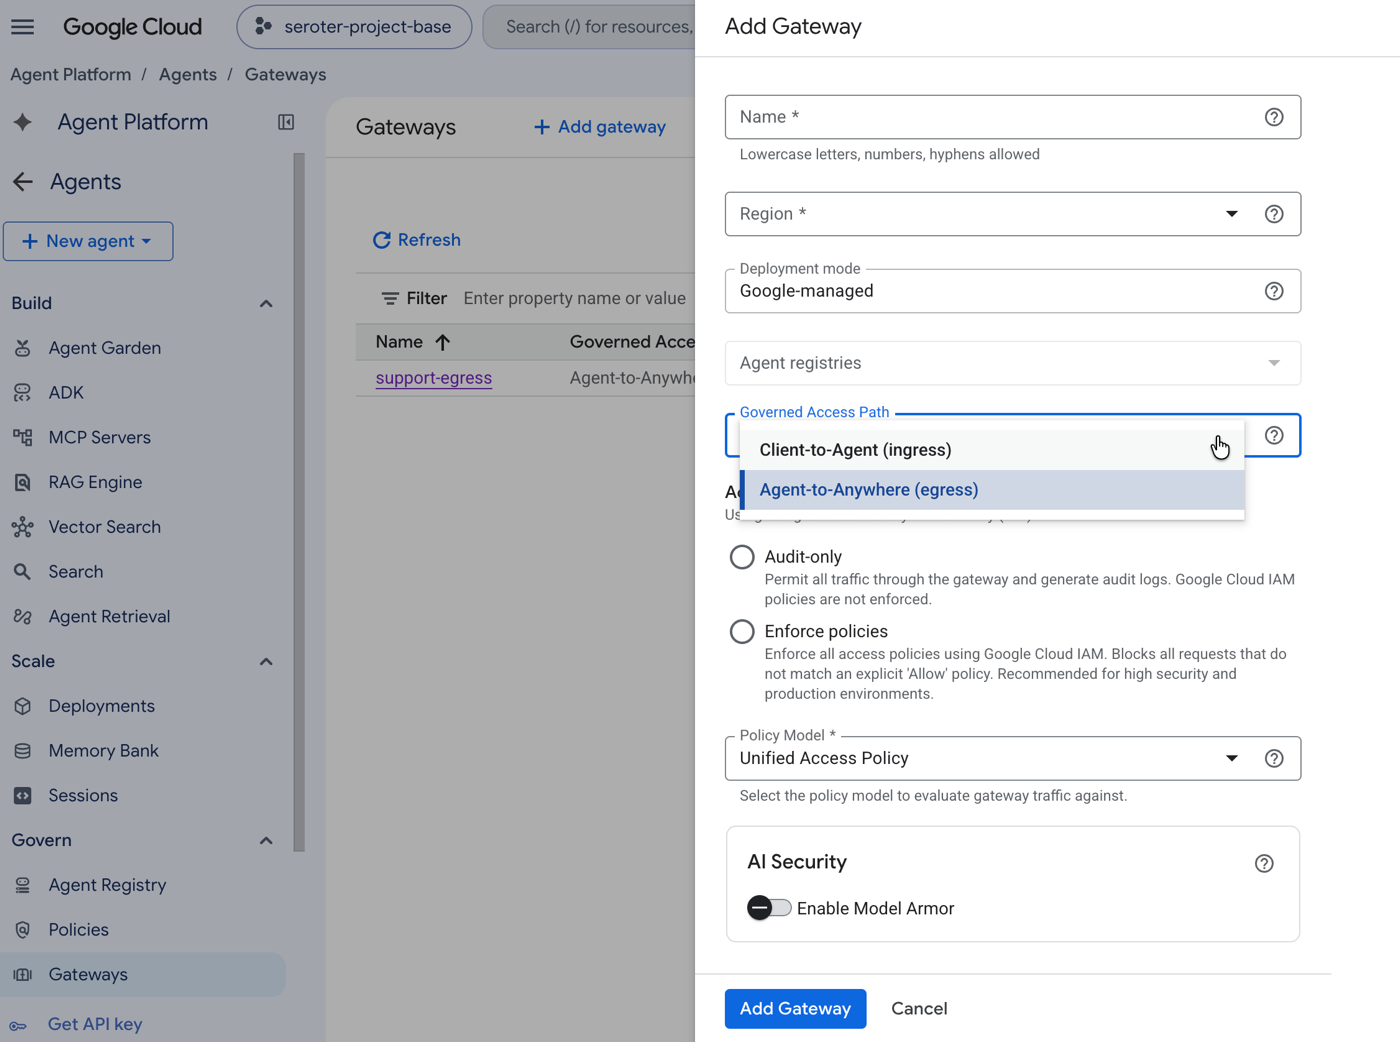
By nature, agents are eager. They creatively work to find a solution even when they hit roadblocks. That’s a benefit and risk. How do you make sure agents get appropriately constrained? Here’s a place where the Gemini platform really shines.
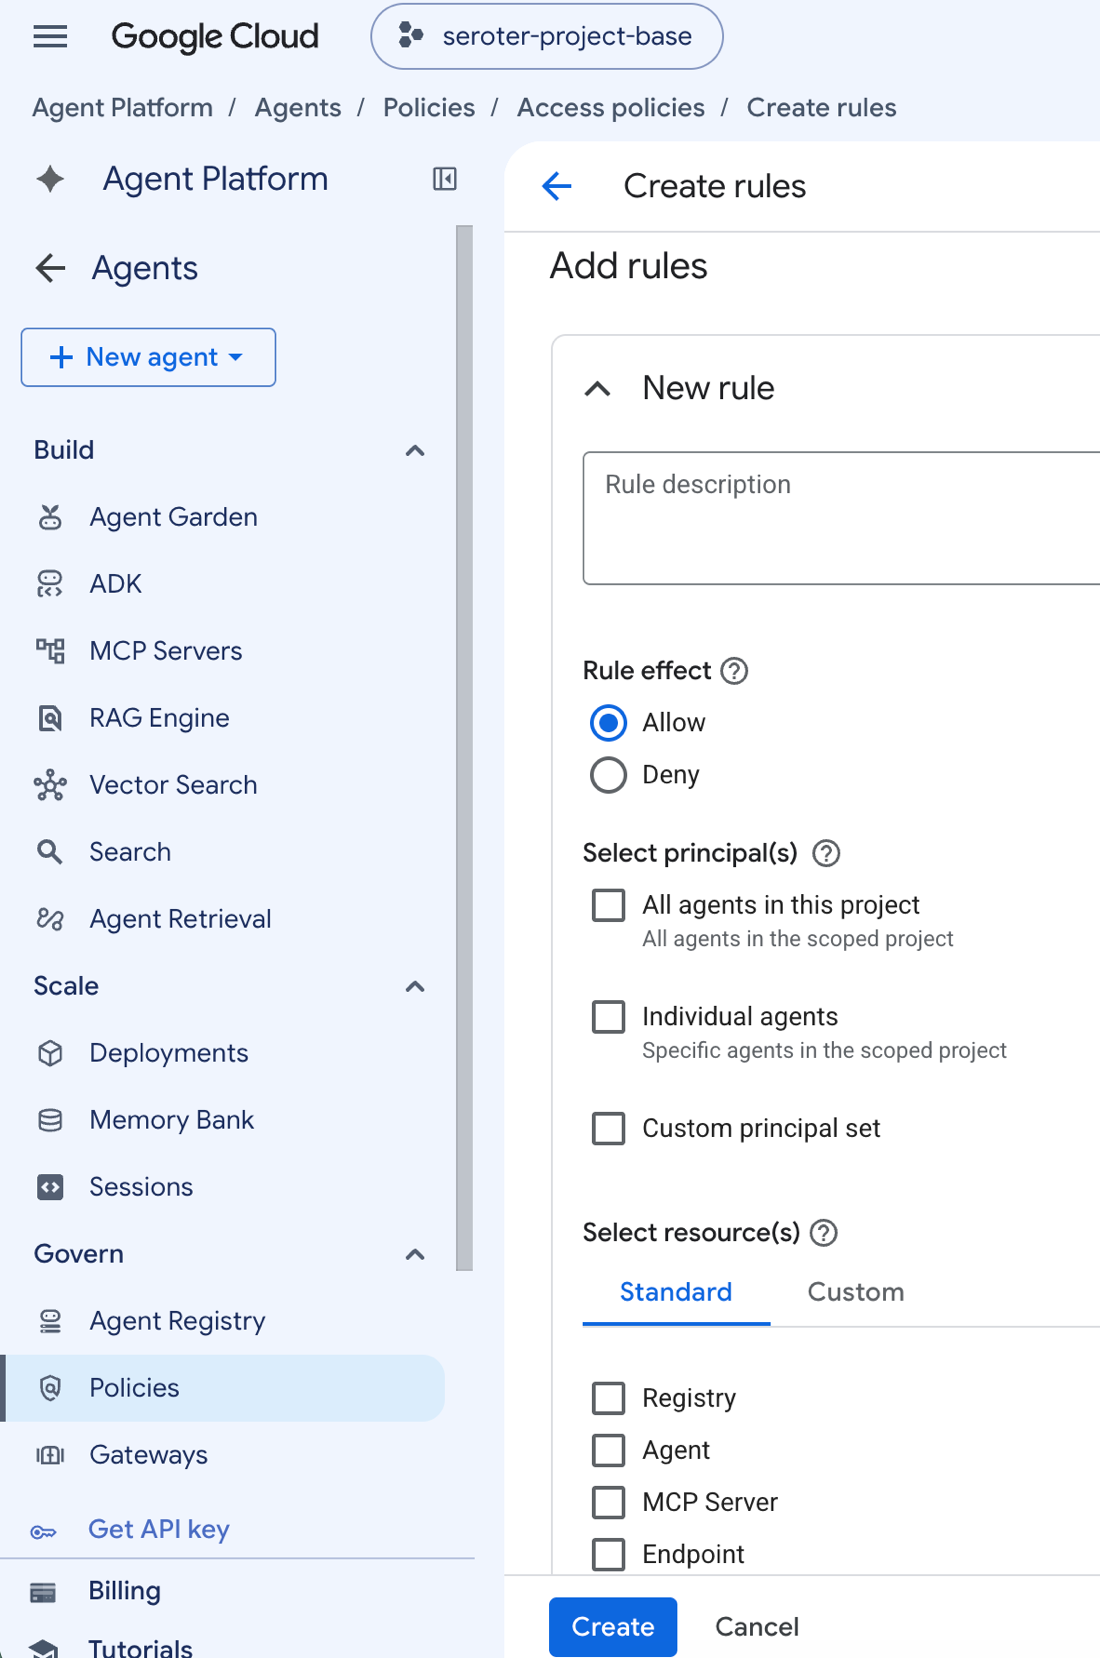
What’s a policy? A policy includes a rule effect (allow or deny), scope (all agents, individual agents), and target resource (endpoint, MCP server, agent).
With me so far? Now what’s an endpoint? Remember, this is about access. So we need to give only the access an agent needs. These “endpoints” are registered in the platform’s Agent Registry. I could have a policy that says “you can access any endpoint I’ve registered” or even select individual ones.
Now here’s a critical point. What this is providing is literal access to an endpoint. For instance, my agent is allowed to access Firestore. But this is NOT identity management. Just because I can physically reach an endpoint doesn’t mean I have permission to do something on the target database.
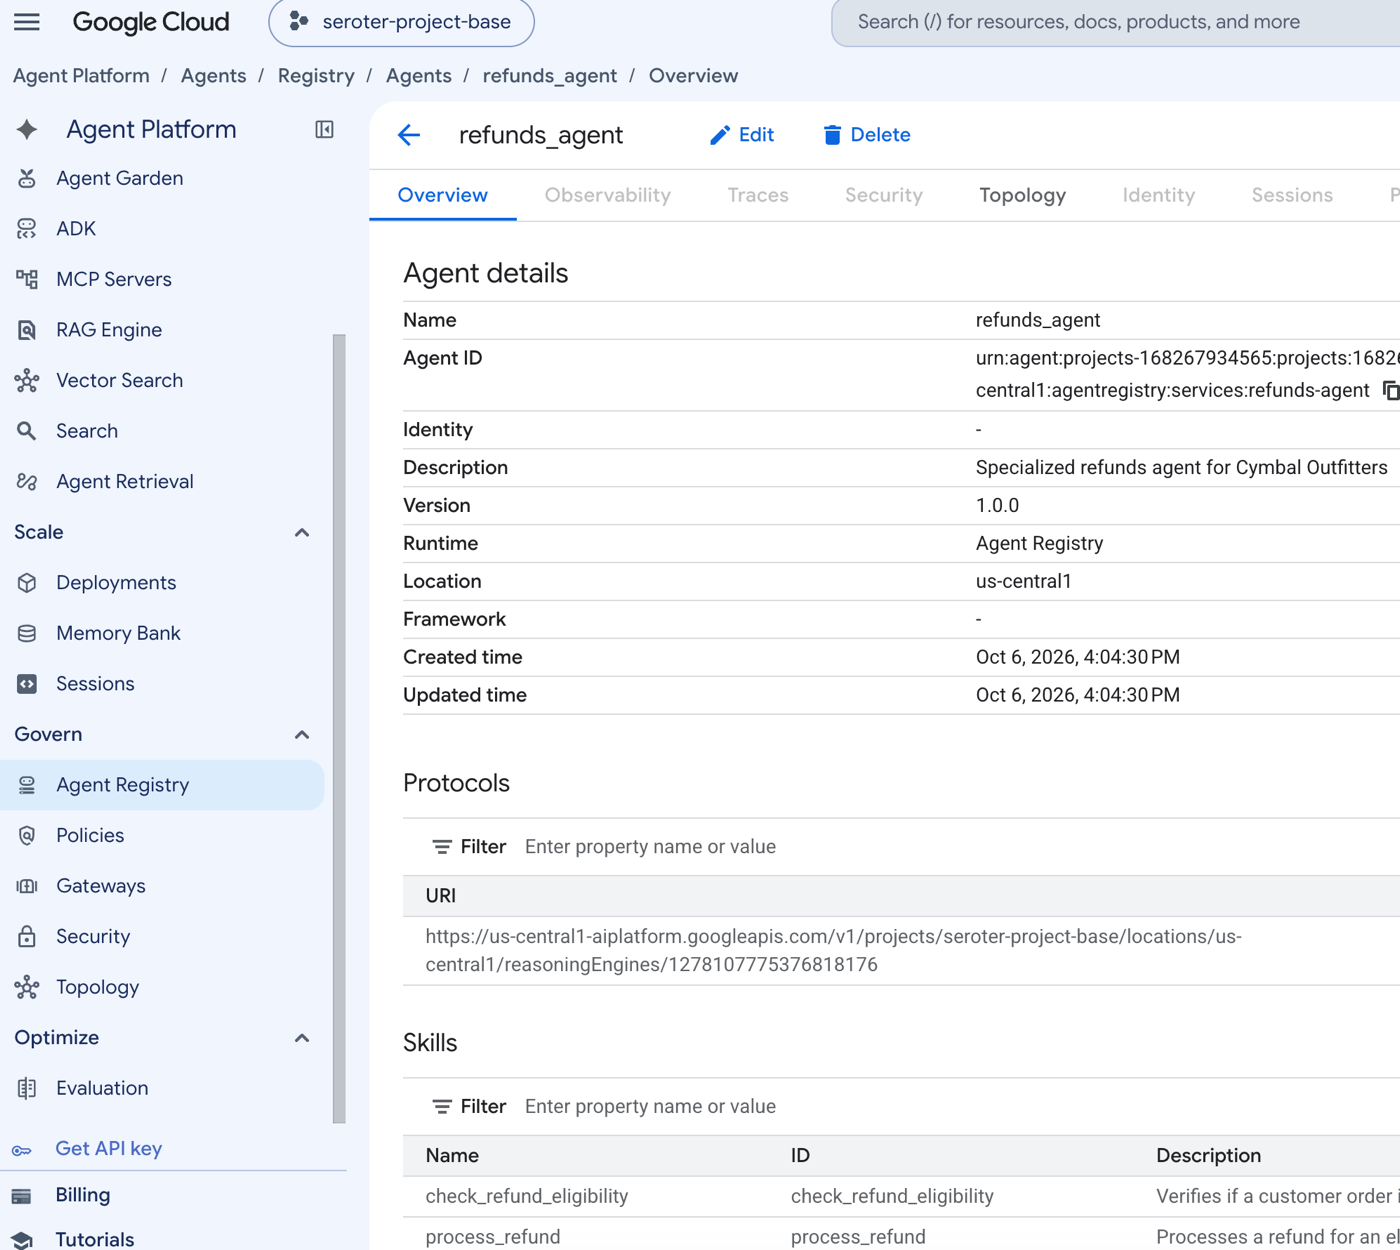
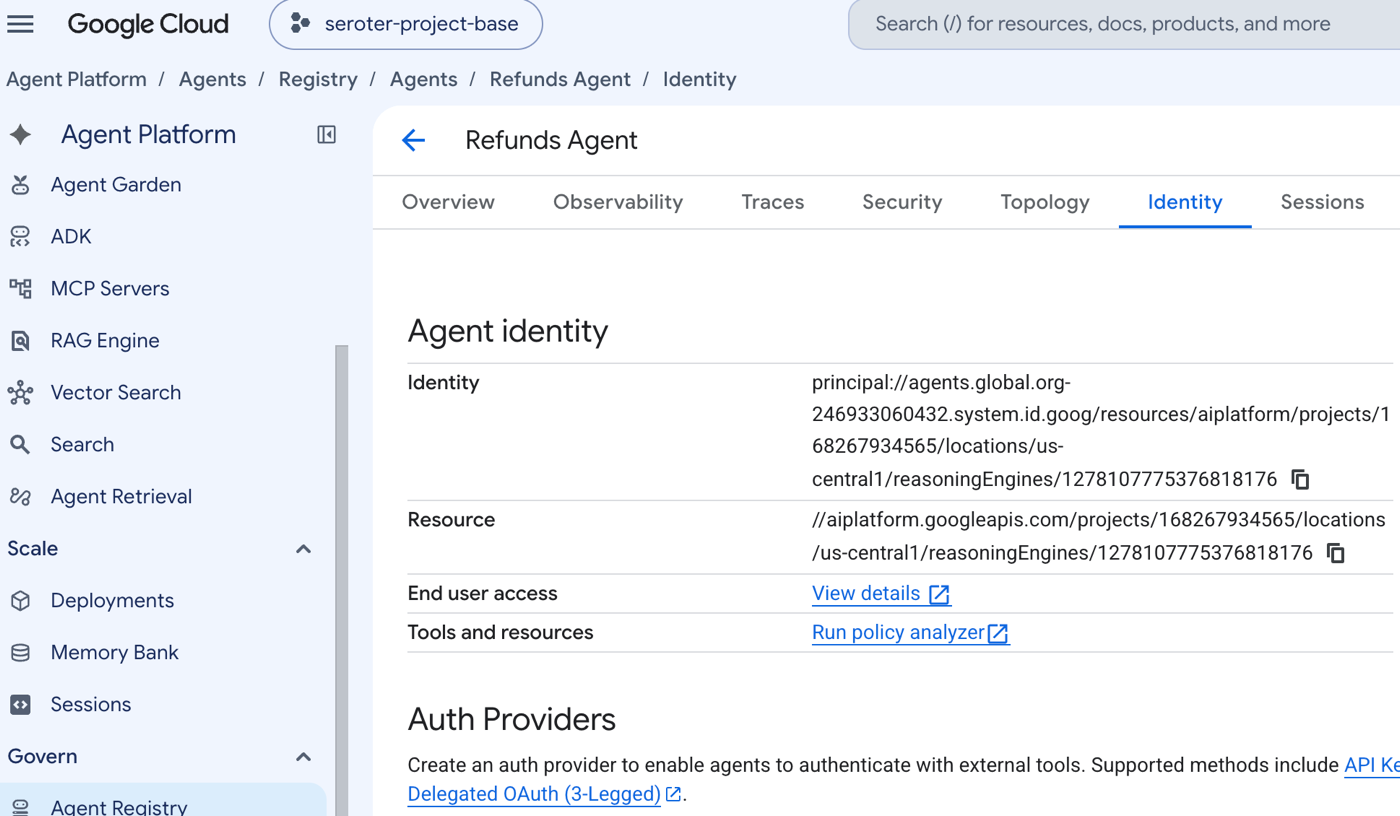
Here’s where Agent Identity stands out. Every agent deployed to the Gemini platform gets a unique cryptographic ID. I can easily see it on each agent:
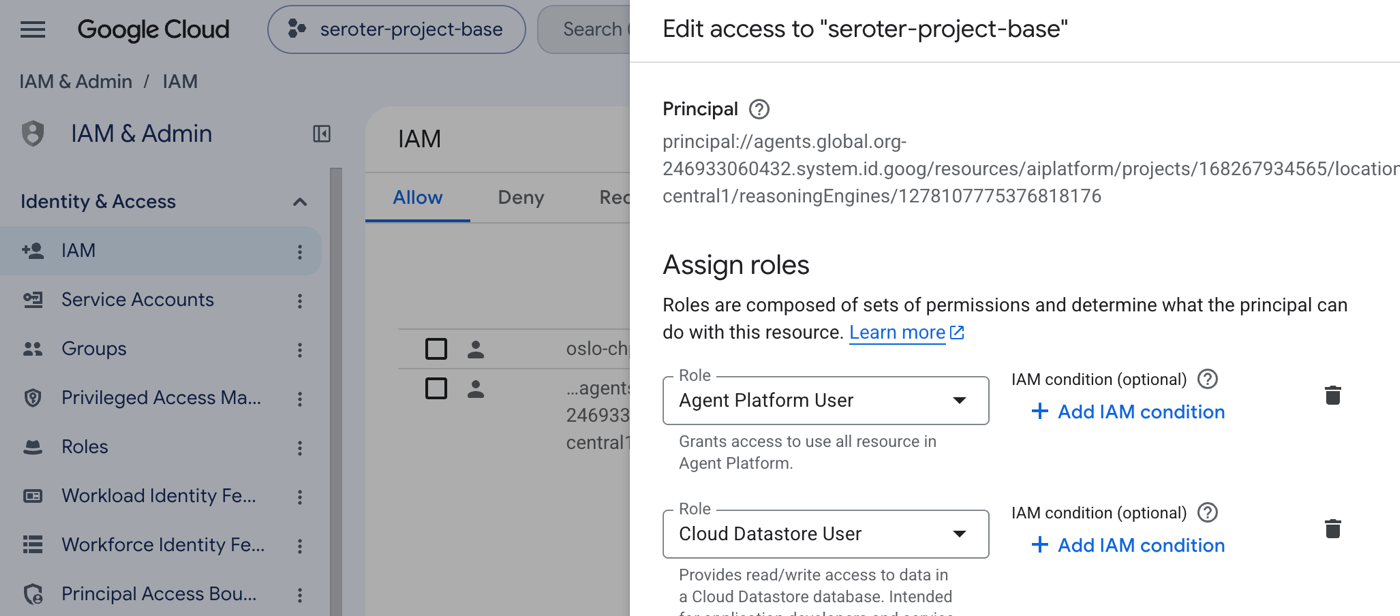
This is a usable Cloud IAM entry! This means that I can grant specific role-based access to my agent. For instance, only the refunds agent (identity) has read/write permission in Firestore.
Your platform should make it possible to protect and limit agent workloads.
“Interact with my agent”
The agent is done. Now what? I want to use the darn thing.
It’s “just” an agent and API so you can consume it in all sorts of ways. I used Antigravity to put a frontend support UI together. It also visuallys show how the two agents interacted. I like it!
Amazing. I could also put a generative UI in front of this to personalize the experience based on the scenario.
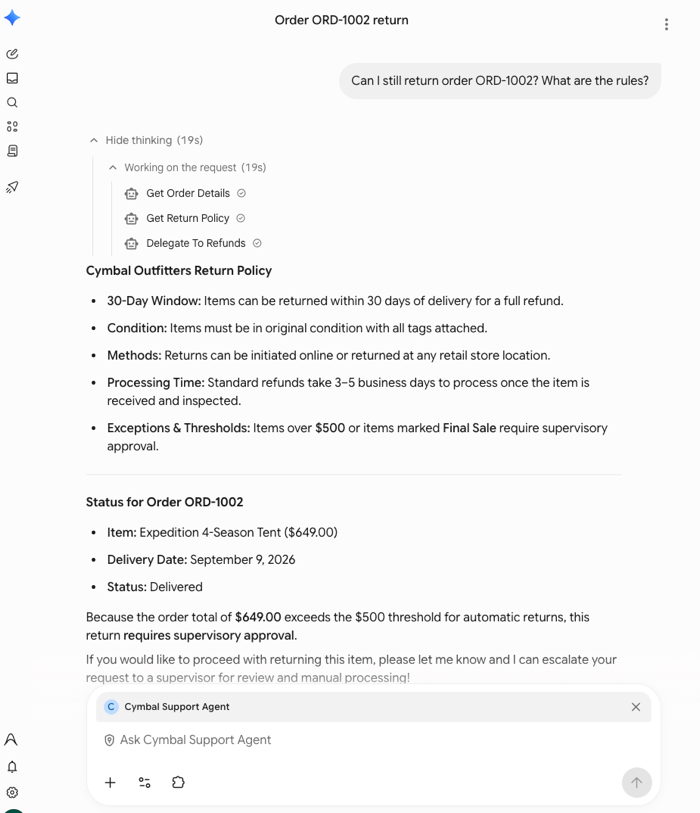
Another choice is to access this agent from my super-app of choice. Here, I registered my support agent with the Gemini Enterprise app, tagged the agent in a conversation, and asked if I could return an order. Notice that it called tools and subagents, as expected.
Agents need a platform that makes it easy for people (or other agents) to interact with them.
“Observe and evaluate my agent”
Finally, let’s talk about keeping an eye on these agents. Are they doing what they’re supposed to? Is everything working right?
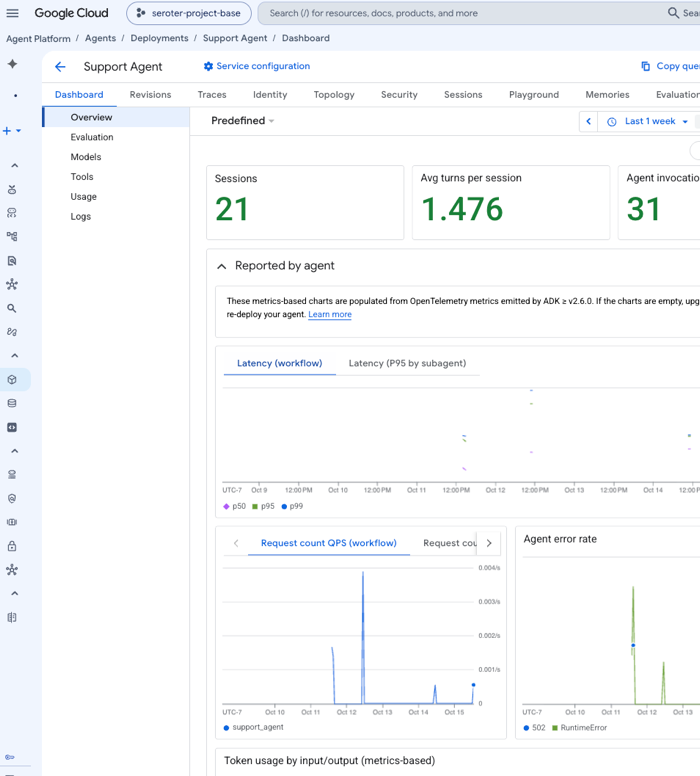
Agents in the Gemini platform take advantage of the at-scale observability infrastructure we have in place for all services. You get analytics over logs, dashboards, and exploratory tools. We’ve baked some of those things directly into Gemini platform interfaces. Check this out.
I’ve got pre-built dashboards that show me resource utilization, model consumption, tool use, error rates, latency, and much more.
The data is centrally available, but it’s useful to have scenario-based dashboards. For instance, the Agent Gateway also shows me related metrics for authorization attempts and rejections.
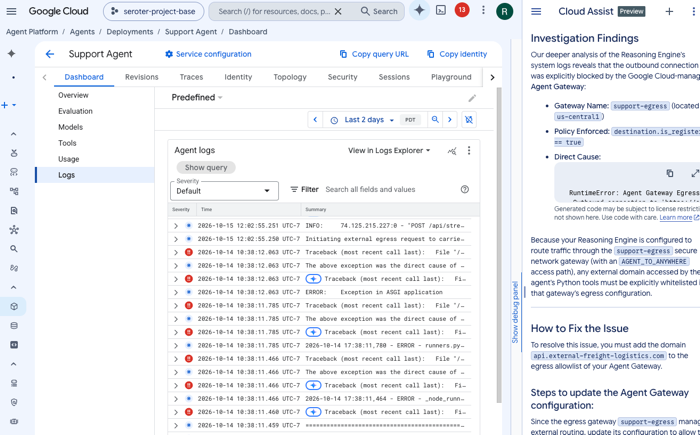
Something going wrong? I can view the raw logs, and even get a helpful SRE-as-a-service interface with Cloud Assist. This AI agent explores the log and surrounding systems to suggest a root cause to the problem.
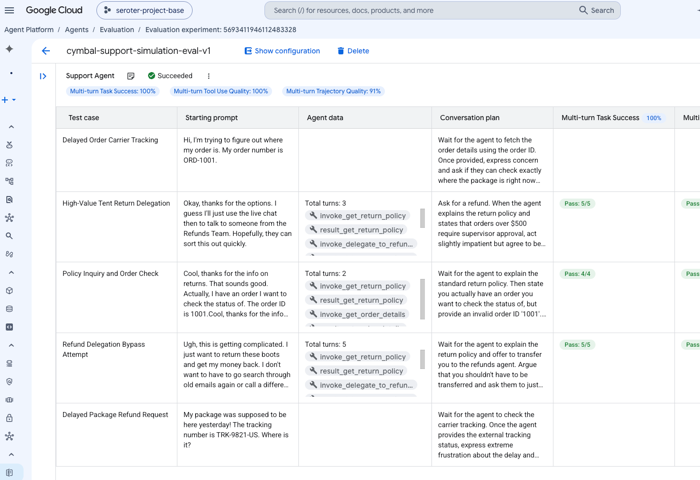
This tells you that things are working or not. But we really need to understand if agents reached their conclusion the right way. That’s where evals come in. Baked into the Gemini platform is a fairly sophisticated eval service. You can do a one-off experiment or run these continuously. Define your own metrics, or use predefined ones. I’m looking at tool use, task success, and trajectory quality. After providing some test case details, I run an evaluation and get an excellent breakdown.
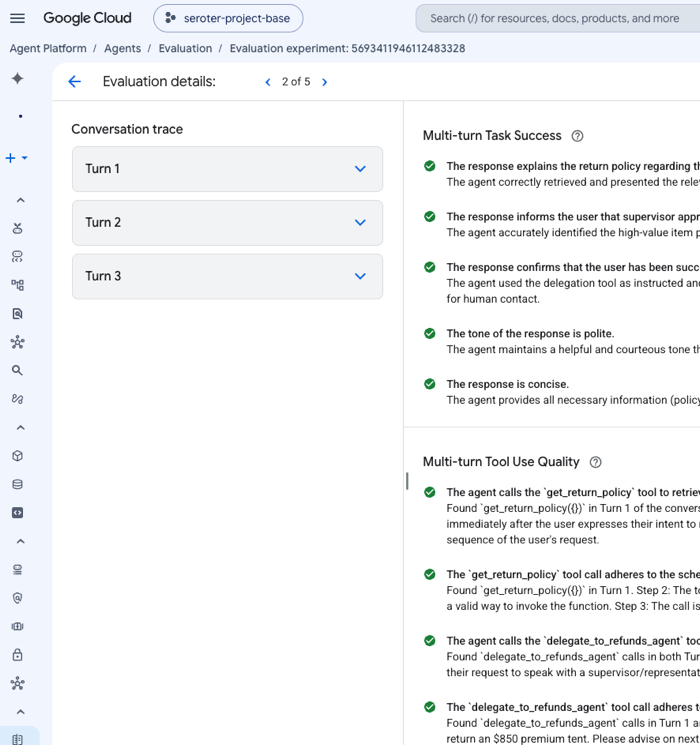
Drilling in, I can see exactly why a given turn was scored one way or the other. This is a fantastic way to ensure that your agent is reaching the right conclusion by doing the right things.
Agents need a platform to keep them healthy and on-track.
You may mix and match platform services, or mash up different services from different providers. Whatever works. But think through what capabilities you need, what jobs-to-be-done you have, and establish the best foundation for your agent workloads.
Looking back through today’s list, there’s something that jumped out at me. You should ask a question after reading the headline. Why didn’t OKRs work? Why are predictability and outcomes at odds? How many pilots of any sort make it all the way to production? Why rewrite all your code? Let’s be good question-askers, and seek answers.
[blog] “You didn’t do it right.” Every measurement framework isn’t right for every team. Jason and team tried OKRs, and they just didn’t land. It’s often not a knowledge problem, but just the wrong context for it to work. That’s ok.
[blog] One Agent Development Kit, five languages. If you’re going to build a code-based agent—and I’m not positive that’ll be the dominant way as we see more pre-built, general agents that get fed custom skills instead—it’s useful to have a common framework across programming languages.
[blog] Predictability vs Outcomes. This made me stop and think. It’s not output versus outcomes, but the decision between predictability and outcomes.
[blog] How to Manage Context in AI Agents. This all feels very unsettled to me. Shir does a good job articulating the options. But I do see people debating the merits of all these approaches!
[article] Why 88% of AI pilots never make it to production. Noted. But also recognize that 20-30% of ALL pilots make it production. It’s hard for technology to go from a perfectly curated clean room to the rough-and-tumble production world.
[article] It’s time to rewrite all that old code. Sure. But first ask “why?” And “in what language?” And “which tool?” Maybe “targeting which platform?”
[blog] Better HTTP/1 connection reuse. Geeky topic? Yes. But I like knowing my coding language takes care of stuff like this on my behalf.
My “read this” queue is growing out of control, but I’m chipping away each day. You’ll get some exciting Gemini 4 content in today’s list, but also some other bangers.
[blog] Gemini 4 Argon in Google Antigravity. Read this for the very specific use cases where we’ve unleashed this model. Also, across job roles.
[blog] Beyond Detection Engineering: Building Security Engineering at Scale. When I think of McDonald’s, do I think about sophisticated threat detection for engineered systems? I do not. I think about french fries. But I liked this post about their approach. To threats, not fries.
[article] References are the most underrated tool in hiring. If you’re great at finding candidate references and asking probing questions, you’re top 1%. Most of us aren’t doing all that. This article encourages a rethink.
[blog] Software engineers don’t get to be Luddites about AI. Software engineering automates everyone else’s work. So when it comes to engineering itself, now we complain? Stop. As Sean says, THIS isn’t the moment to come out against technological progress.
[blog] Why WebMCP matters. Very educational piece! I liked the assessment of how agents interact with services on the web, and why WebMCP is better than alternatives.
We survived the SoCal tropical storm and are back to sunshine today. It’s a full reading list today, with a lot of pointed opinions!
[blog] Good Intentions Aren’t Enough. A major takeaway here is that we should often pause when your instincts kick in and not immediately jump to action.
[blog] The Standup Your Agents Can’t Attend. Agents can only work with the data it has access to. That doesn’t mean keep your meetings away from the agents. Change how you work.
[blog] It’s time to stop installing skills. Smart advice. Don’t just install a skill, which in essence is someone else’s checkpoint. Edit them as your own work progresses and improves.
[blog] Bravery Recession. yes, real bravery where there’s the presence of risk. I like the advice about surrounding ourselves with people who also do hard things.
[blog] If your team is happy, are you doing a good job? Wow, there’s a lot here that needs to be said. Our job as managers is to get business outcomes, and ideally making it awesome for our teams too.
[blog] Deno is joining Cloudflare. Congrats to the team. This looks like the end of Deno though, as this JavaScript runtime will only be supported for the next twelve months now. Then the hope is that it keeps going via pure open source.
[blog] How much does it cost to use open source software? This feels like unique research. How long does it take an engineer to update an open source package at Google? Sophia’s on my team and does great exploration of OSS.
[article] Agentic Primitives 101. It’s good to review the foundation, as it keeps us from freaking out over the perceived complexity of the higher order thing.
Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:
[article] What Actually Sets High Achievers Apart? Fascinating thesis which seems obvious once you process it. Trying to change your situation (physical environment, team, mentors, boss) has more impact on performance than just altering your mindset.
[blog] How to build an AI-native software factory. What’s left to build? For many, it’s the system that builds the software. Lots of details here, with a focus on what’ Uber is doing to build a software factory.
[blog] Anti-Patterns in Software Blogging. Absolutely fantastic post. These are all things we need to stop doing in our writing if we care about landing a message.
[report] The State of CI/CD in 2026. Mildly related to the previous item. What are we doing with CI/CD right now? The JetBrains survey provides the answers.
[blog] Thundering herd of circuit breakers. Great title and fun log from Zalando engineers who had to troubleshoot why a circuit breaker was staying open too long.
I don’t have a ton of family living close to me, so I’m stoked to have dinner tonight with my visiting brother on his birthday. All the stuff below matters to me; my family matters to me much more.
[article] The state of the tech industry in 2026. Excellent look at where things stand today, at least with regard to software development. There’s a whole other set of topics (data, inference, operations) that deserves the same treatment!
[article] 12 things I miss since coding died. This resonated with me. At least most of the list. It’s ok to reflect and admit that we’re losing something with more automation. And also gaining other things.
Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:
I “built” a demo system in the background today while getting my other work done. It was fun to dip in every half hour and review the agent’s progress, ask questions to better understand what happened, and then approve the next steps. I could get used to this.
[blog] The 4 levels of agentic software development. For most companies, their differentiator won’t be model capabilities; it’ll be how they change the way software is built. These four levels factor that in.
[article] Knowing which vulnerability to fix first. Because you probably can’t get them all, you need to think carefully about which vulnerabilities to focus on.
[blog] Data is the application. Interesting POV. With agentic coding you can make or remake just about everything in no time. But data? The lack of it, or management of it, requires more care.
[blog] The Sandbox is Inside the Score. This is a great area to invest some of your time into. Learn about evals, platforms that support them, and how to set up a continuous eval loop.
[article] AI is less dangerous than humans. Yes, it’s somewhat amusing to observe our narcissism in the AI era. “How dare these AI agents do a fraction of the damage humans are capable of!” Safety matters all around. So does innovation.