Author: Richard Seroter

  • Build event handlers and scale them across regions, all with serverless cloud services? Let’s try it.

    Build event handlers and scale them across regions, all with serverless cloud services? Let’s try it.

    Is a serverless architecture realistic for every system? Of course not. But it’s never been easier to build robust solutions out of a bunch of fully-managed cloud services. For instance, what if I want to take uploaded files, inspect them, and route events to app instances hosted in different regions around the world? Such a solution might require a lot of machinery to set up and manage—file store, file listeners, messaging engines, workflow system, hosting infrastructure, and CI/CD products. Yikes. How about we do that with serverless technology such as:

    The final architecture (designed with the free and fun Architecture Diagramming Tool) looks like this:

    Let’s build this together, piece by piece.

    Step 1: Build Java app that processes CloudEvents

    The heart of this system is the app that processes “loan” events. The events produced by Eventarc are in the industry-standard CloudEvents format. Do I want to parse and process those events in code manually? No, no I do not. Two things will help here. First, our excellent engineers have built client libraries for every major language that you can use to process CloudEvents for various Google Cloud services (e.g. Storage, Firestore, Pub/Sub). My colleague Mete took it a step further by creating VS Code templates for serverless event-handlers in Java, .NET, Python, and Node. We’ll use those.

    To add these templates to your Visual Studio Code environment, you start with Cloud Code, our Google Cloud extension to popular IDEs. Once Cloud Code is installed, I can click the “Cloud Code” menu and then choose the “New Application” option.

    Then I chose the “Custom Application” option and “Import Sample from Repo” and added a link to Mete’s repo.

    Now I have the option to pick a “Cloud Storage event” code template for Cloud Functions (traditional function as a service) or Cloud Run (container-based serverless). I picked the Java template for Cloud Run.
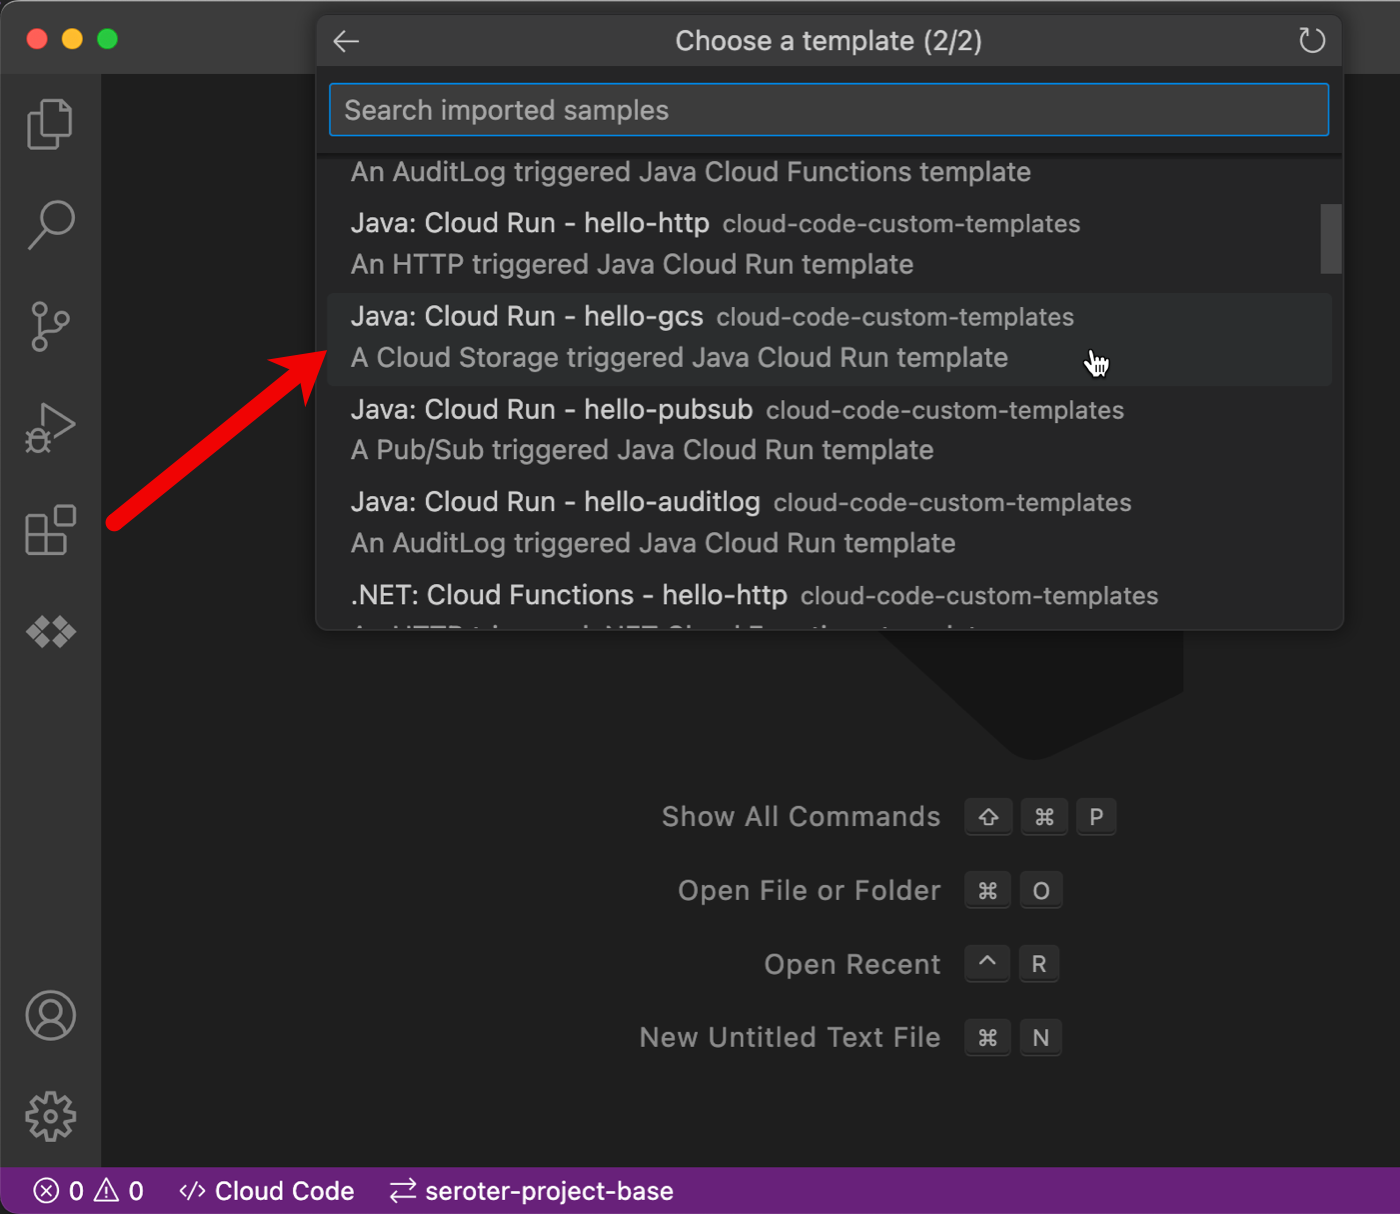
    The resulting project is a complete Java application. It references the client library mentioned above, which you can see as google-cloudevent-types in the pom.xml file. The code is fairly straightforward and the core operation accepts the inbound CloudEvent and creates a typed StorageObjectData object.

    @PostMapping("/")
    ResponseEntity<Void> handleCloudEvent(@RequestBody CloudEvent cloudEvent) throws InvalidProtocolBufferException {
    
          // CloudEvent information
          logger.info("Id: " + cloudEvent.getId());
          logger.info("Source: " + cloudEvent.getSource());
          logger.info("Type: " + cloudEvent.getType());
    
          String json = new String(cloudEvent.getData().toBytes());
          StorageObjectData.Builder builder = StorageObjectData.newBuilder();
          JsonFormat.parser().merge(json, builder);
          StorageObjectData data = builder.build();
    
          // Storage object data
          logger.info("Name: " + data.getName());
          logger.info("Bucket: " + data.getBucket());
          logger.info("Size: " + data.getSize());
          logger.info("Content type: " + data.getContentType());
    
          return ResponseEntity.ok().build();
     }
    

    This generated project has directions and scripts to test locally, if you’re so inclined. I went ahead and deployed an instance of this app to Cloud Run using this simple command:

    gcloud run deploy --source .
    

    That gave me a running instance, and, a container image I could use in our next step.

    Step 2: Create parallel deployment of Java app to multiple Cloud Run locations

    In our fictitious scenario, we want an instance of this Java app in three different regions. Let’s imagine that the internal employees in each geography need to work with a local application.

    I’d like to take advantage of a new feature of Cloud Deploy, parallel deployments. This makes it possible to deploy the same workload to a set of GKE clusters or Cloud Run environments. Powerful! To be sure, the MOST applicable way to use parallel deployments is a “high availability” scenario where you’d deploy identical instances across locations and put a global load balancer in front of it. Here, I’m using this feature as a way to put copies of an app closer to specific users.

    First, I need to create “service” definitions for each Cloud Run environment in my deployment pipeline. I’m being reckless, so let’s just have “dev” and “prod.”

    My “dev” service definition looks like this. The “image” name can be anything, as I’ll replace this placeholder in realtime when I deploy the pipeline.

    apiVersion: serving.knative.dev/v1
    kind: Service
    metadata:
      name: event-app-dev
    spec:
      template:
        spec:
          containers:
          - image: java-eventlistener
    

    The “production” YAML service is identical except for a different service name.

    Next, I need a Skaffold file that identifies the environments for my pipeline, and points to the respective YAML files that represent each environment.

    apiVersion: skaffold/v4beta1
    kind: Config
    metadata: 
      name: deploy-run-webapp
    profiles:
    - name: dev
      manifests:
        rawYaml:
        - run-dev.yaml
    - name: prod
      manifests:
        rawYaml:
        - run-prod.yaml
    deploy:
      cloudrun: {}
    

    The final artifact I need is a DeliveryPipeline definition. It calls out two stages (dev and prod), and for production that points to a multiTarget that refers to three Cloud Run targets.

    apiVersion: deploy.cloud.google.com/v1
    kind: DeliveryPipeline
    metadata:
     name: my-parallel-event-app
    description: event application pipeline
    serialPipeline:
     stages:
     - targetId: app-dev
       profiles: [dev]
     - targetId: app-prod-multi
       profiles: [prod]
    ---
    
    apiVersion: deploy.cloud.google.com/v1
    kind: Target
    metadata:
     name: app-dev
    description: Cloud Run development service
    run:
     location: projects/seroter-project-base/locations/us-central1
    
    ---
    
    apiVersion: deploy.cloud.google.com/v1
    kind: Target
    metadata:
     name: app-prod-multi
    description: production
    multiTarget:
     targetIds: [prod-east, prod-west, prod-northeast2]
    ---
    
    apiVersion: deploy.cloud.google.com/v1
    kind: Target
    metadata:
     name: prod-east
    description: production us-east1
    run:
     location: projects/seroter-project-base/locations/us-east1
    ---
    
    apiVersion: deploy.cloud.google.com/v1
    kind: Target
    metadata:
     name: prod-west
    description: production us-west1
    run:
     location: projects/seroter-project-base/locations/us-west1
    
    ---
    
    apiVersion: deploy.cloud.google.com/v1
    kind: Target
    metadata:
     name: prod-northeast2
    description: production northamerica-northeast2
    run:
     location: projects/seroter-project-base/locations/northamerica-northeast2 
    

    All set. It takes a single command to create the deployment pipeline.

    gcloud deploy apply --file=clouddeploy.yaml --region=us-central1 --project=seroter-project-base
    

    In the Google Cloud Console, I can see my deployed pipeline with two stages and multiple destinations for production.

    Now it’s time to create a release for this deployment and see everything provisioned.

    The command to create a release might be included in your CI build process (whether that’s Cloud Build, GitHub Actions, or something else), or you can run the command manually. I’ll do that for this example. I named the release, gave it the name of above pipeline, and swapped the placeholder image name in my service YAML files with a reference to the container image generated by the previously-deployed Cloud Run instance.

    gcloud deploy releases create test-release-001 \
    --project=seroter-project-base \
    --region=us-central1 \
    --delivery-pipeline=my-parallel-event-app \
    --images=java-eventlistener=us-south1-docker.pkg.dev/seroter-project-base/cloud-run-source-deploy/java-cloud-run-storage-event
    

    After a few moments, I see a deployment to “dev” rolling out.

    When that completed, I “promoted” the release to production and saw a simultaneous deployment to three different cloud regions.

    Sweet. Once this is done, I check and see four total Cloud Run instances (one for dev, three for prod) created. I like the simplicity here for shipping the same app instance to any cloud region. For GKE clusters, this also works with Anthos environments, meaning you could deploy to edge, on-prem or other clouds as part of a parallel deploy.

    We’re done with this step. I have an event-receiving app deployed around North America.

    Step 3: Set up Cloud Storage bucket

    This part is simple. I use the Cloud Console to create a new object storage bucket named seroter-loan-applications. We’ll assume that an application drops files into this bucket.

    Step 4: Write Cloud Workflow that routes events to correct Cloud Run instance

    There are MANY ways one could choose to architect this solution. Maybe you upload files to specific bucket and route directly to the target Cloud Run instance using a trigger. Or you route all bucket uploads to a Cloud Function and decide there where you’ll send it next. Plus dozens of other options. I’m going to use a Cloud Workflow that receives an event, and figures out where to send it next.

    A Cloud Workflow is described with a declarative definition written in YAML or JSON. It’s got a standard library of functions, supports control flow, and has adapters to lots of different cloud services. This Workflow needs to parse an incoming CloudEvent and route to one of our three (secured) Cloud Run endpoints. I do a very simple switch statement that looks at the file name of the uploaded file, and routes it accordingly. This is a terrible idea in real life, but go with me here.

    main:
        params: [eventmsg]
        steps:
            - get-filename:
                assign:
                    - filename: ${eventmsg.data.name}
            - choose_endpoint:
                switch:
                    - condition: ${text.match_regex(filename, "northeast")}
                      next: forward_request_northeast
                    - condition: ${text.match_regex(filename, "uswest")}
                      next: forward_request_uswest
                    - condition: ${text.match_regex(filename, "useast")}
                      next: forward_request_useast
            - forward_request_northeast: 
                call: http.post
                args:
                    url: https://event-app-prod-ofanvtevaa-pd.a.run.app
                    auth:
                        type: OIDC
                    headers:
                        Content-Type: "application/json"
                        ce-id: ${eventmsg.id} #"123451234512345"
                        ce-specversion: ${eventmsg.specversion} #"1.0"
                        ce-time: ${eventmsg.time} #"2020-01-02T12:34:56.789Z"
                        ce-type: ${eventmsg.type} #"google.cloud.storage.object.v1.finalized"
                        ce-source: ${eventmsg.source} #"//storage.googleapis.com/projects/_/buckets/MY-BUCKET-NAME"
                        ce-subject: ${eventmsg.subject} #"objects/MY_FILE.txt"
                    body:
                        ${eventmsg.data}
                result: the_message
                next: returnval
            - forward_request_uswest: 
                call: http.post
                args:
                    url: https://event-app-prod-ofanvtevaa-uw.a.run.app
                    auth:
                        type: OIDC
                    headers:
                        Content-Type: "application/json"
                        ce-id: ${eventmsg.id} #"123451234512345"
                        ce-specversion: ${eventmsg.specversion} #"1.0"
                        ce-time: ${eventmsg.time} #"2020-01-02T12:34:56.789Z"
                        ce-type: ${eventmsg.type} #"google.cloud.storage.object.v1.finalized"
                        ce-source: ${eventmsg.source} #"//storage.googleapis.com/projects/_/buckets/MY-BUCKET-NAME"
                        ce-subject: ${eventmsg.subject} #"objects/MY_FILE.txt"
                    body:
                        ${eventmsg.data}
                result: the_message
                next: returnval
            - forward_request_useast: 
                call: http.post
                args:
                    url: https://event-app-prod-ofanvtevaa-ue.a.run.app
                    auth:
                        type: OIDC
                    headers:
                        Content-Type: "application/json"
                        ce-id: ${eventmsg.id} #"123451234512345"
                        ce-specversion: ${eventmsg.specversion} #"1.0"
                        ce-time: ${eventmsg.time} #"2020-01-02T12:34:56.789Z"
                        ce-type: ${eventmsg.type} #"google.cloud.storage.object.v1.finalized"
                        ce-source: ${eventmsg.source} #"//storage.googleapis.com/projects/_/buckets/MY-BUCKET-NAME"
                        ce-subject: ${eventmsg.subject} #"objects/MY_FILE.txt"
                    body:
                        ${eventmsg.data}
                result: the_message
                next: returnval
            - returnval:    
                return: ${the_message}    
    

    This YAML results in a workflow that looks like this:

    Step 5: Configure Eventarc trigger to kick off a Cloud Workflow

    Our last step is to wire up the “file upload” event to this workflow. For that, we use Eventarc. Eventarc handles the machinery for listening to events and routing them. See here that I chose Cloud Storage as my event source (there are dozens and dozens), and then the event I want to listen to. Next I selected my source bucket, and chose a destination. This could be Cloud Run, Cloud Functions, GKE, or Workflows. I chose Workflows and then my specific Workflow that should kick off.

    All good. Now I have everything wired up and can see this serverless solution in action.

    Step 6: Test and enjoy

    Testing this solution is straightforward. I dropped three “loan application” files into the bucket, each named with a different target region.

    Sure enough, three Workflows kick off and complete successfully. Clicking into one of them shows the Workflow’s input and output.

    Looking at the Cloud Run logs, I see that each instance received an event corresponding to its location.

    Wrap Up

    No part of this solution required me to stand up hardware, worry about operating systems, or configure networking. Except for storage costs for my bucket objects, there’s no cost to this solution when it’s not running. That’s amazing. As you look to build more event-driven systems, consider stitching together some fully managed services that let you focus on what matters most.

  • Daily Wrap Up – March 24, 2023 (#053)

    On this Friday, I read a whole stash of interesting things. There thought-provoking content on “build versus buy”, analyzing logs in security scenarios, and helping robots navigate your living room.

    [blog] Hello Dolly: Democratizing the magic of ChatGPT with open models. It’ll be interesting to watch and see how many folks attempt to take base LLMs and customize for their needs. Databricks is trying to make that easier with an open source offering.

    [blog] Visual language maps for robot navigation. If reading this changes what you plan to do at work on Monday, I want to be friends with you. For most of us, it’s just neat research to read about.

    [blog] Buy vs Build… Over Time. Good post that emphasizes opportunity cost and the context of the current situation when deciding when to build or buy a solution.

    [article] Three multicloud myths that need to be crushed. Echoes what I’ve been saying for a while. If/when you do multicloud, do it for the right reasons and the right way. I talked about this topic on a Twitter Space yesterday.

    [blog] Nobody cares, train harder. Edgy post, but it resonates with me. Everyone’s got challenges and rarely is everything handed to you. If you want more, push through.

    [article] What’s the Difference between Flutter and React Native? Virtually every year, I threaten to learn a frontend web framework or mobile framework, and every year I don’t. But, I still like to pay attention to what’s out there. This is a good breakdown of two popular options.

    [article] Talking all things NBA with Google’s Bard AI chatbot. If you pay for access to The Athletic, read this surprisingly good back and forth with our AI chat experience.

    [blog] Improving Istio Propagation Delay. This is a good example of (a) why good infrastructure monitoring matters and (b) the value of open source software that you can explore and change if needed. The Airbnb engineering team walks through their experiences here.

    [blog] Gleaning security insights from audit logs with Log Analytics. Logs are a valuable data source, especially when considering security scenarios. This post looks at writing SQL queries to find anomalies and threats.

    ##

    Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:

  • Daily Wrap Up – March 23, 2023 (#052)

    Another day, another batch of AI-related announcements. So much going on in this space! Check out a couple related articles below, while also learning about app modernization challenges, good team cultures, and change data capture.

    [article] Society’s Technical Debt and Software’s Gutenberg Moment. It’s likely AI is going to cause a major disruption to lots of job roles in the short and long term, including those building software. Read this piece.

    [blog] Cheating is All You Need. Steve Yegge is good at rants. He makes great points about the fully disruptive nature of large language models what that means to many people.

    [article] Improving CI/CD Pipelines Through Observability. This isn’t something I’ve thought about very much, so it was useful to read an article about the tactics and useful metrics for a well-monitored set of pipelines.

    [blog] Configure Content-Based Routing to Kafka Topics with YugabyteDB’s Change Data Capture. It’s getting easier and easier to observe database changes. This post shows how Yugabyte does it.

    [blog] Boost your development on Cloud Spanner change streams with a new tail tool. Relatedly, here’s a new open source tool that lets you tap into Cloud Spanner DB changes and get a live local view.

    [blog] Unified Streaming And Batch Pipelines At LinkedIn: Reducing Processing time by 94% with Apache Beam. Good deep dive from LinkedIn that looks at data processing with the Apache Beam, a project Google started years ago.

    [blog] Announcing Google Cloud’s new Digital Sovereignty Explorer. Thinking about data, operational, or software sovereignty? Lots of folks are. This post introduces a tool for exploring key questions that lead you to a valid approach.

    [blog] The new Google Cloud region in Turin Italy is now open. Whenever I retire, I’ve thought about visiting every baseball stadium. Maybe I should also aim for visiting every city where Google Cloud offers a “region.”

    [news] Survey Surfaces Application Modernization Challenges. Oof, tough numbers here. Level of confidence in understanding modernization effort plummets once the work starts. Lots of challenges finding people to support existing apps. More in this depressing, but important data.

    [blog] 2022 State of DevOps Report data deep dive: good team culture. Do you know how to measure your team’s culture? We’ve got years of data that shows high performing teams have certain traits. This post highlights a few of them.

    ##

    Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:

  • Daily Wrap Up – March 22, 2023 (#051)

    Spent the day in Silicon Valley with our friends at GitLab. Was still able to consume some good content that you’ll find below.

    [youtube-video] Unboxing brand new Google Bard and GPT-4. Fun video by a colleague of mine who engages in a short conversation with two generative AI experiences.

    [blog] EA Principles Addendum: Build vs. Buy. This post highlights why blogs, social media, and chance interactions matter. We all learn from each other! Brian digs further into his “build vs buy” EA principle and how it’ll evolve a bit after feedback.

    [blog] Google Summer of Code 2023 contributor applications open! If you’re a student or open source beginner (or know one), apply to this impactful program by April 4th.

    [article] 5 Strategies to Empower Employees to Make Decisions. Read this post if you or your team struggles with empowerment and decision making.

    [blog] 16 tips to help you be more focused and organized at work. I think I do most of these. Good tips.

    [blog] Run your game infrastructure on GKE Autopilot to focus on player experience. Even if you’re not a gaming company, you PROBABLY think a lot about cost effectiveness, elasticity, and good performance. Read this post with than lens.

    [blog] Technology Lifecycle. The Slack Engineering team explores the stages of an infrastructure project (e.g. alpha, active, retirement) and what to consider at each stage.

    [blog] Lessons from the future: Why shared fate shows us a better cloud roadmap. Who does what in your cloud relationship? Is there a lot of unspoken expectation? Good post here that steers you towards a more realistic model.

    ##

    Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:

  • Daily Wrap Up – March 21, 2023 (#050)

    I’m on the way to the Google Cloud mothership in Sunnyvale (San Jose area) but still read a bunch of terrific things today. It includes new stuff to play with (Bard, code templates) and new ideas to chew on (product vision, testing, pragmatic pessimism).

    [blog] Try Bard and share your feedback. US and UK folks can jump into our generative AI experience. Have fun!

    [blog] Product Vision is Science Fiction. Excellent post that explains what a “product vision” really is, and how to generate one. And, how not to fear that you’ll be wrong. You will be.

    [blog] Choosing Sequential Testing Framework — Comparisons and Discussions. Check out this new post from the Spotify Engineering team that helps you decide how to run good online user experiments.

    [blog] Performance Optimization with BigQuery. Lots of very specific advice here for optimizing your data warehouse (BigQuery, in this case). It’s applicable to many products.

    [article] Developers, unite! Join the fight for code quality. Is the pursuit of “quality” the most exciting thing a developer can do? I dunno. But this article lays out why it matters, and how to build momentum for a focus on quality at your company.

    [blog] Extending Cloud Code with custom templates. My colleague created some very useful templates for languages like .NET and Java that make it simpler to build event-driven serverless apps. If you’re using Visual Studio Code, you can easily try it out.

    [article] Adobe is bringing generative AI features to Photoshop, After Effects and Premiere Pro. Figuring out what’s real and AI-generated is going to be quite tricky in the months and years ahead.

    [news] Awareness of Software Supply Chain Security Issues Improves. If you’ve been reading these updates, you’ve seen a lot of mentions of software supply chain security. That topic is now top of mind for a lot of technology leaders, and that’s a good thing.

    [blog] Lessons from a Pessimist: Make Your Pessimism Productive. I’m an annoying optimist, but hopefully a pragmatic person as well. This post looks at useful pessimism.

    [blog] Nvidia partners with Google Cloud to launch AI-focused hardware instances. For those building generative models, the cloud is going to be the place to do it. We announced some new instance types that will come to Vertex and GKE soon.

    [blog] Your cloud, your way: Google Distributed Cloud Hosted is generally available. If you can use the public cloud, do it. Every “private cloud” is only a shadow of what’s possible in a hyperscale cloud. But sometimes your use case demands it, and this new offering might be the right fit for you.

    ##

    Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:

  • Daily Wrap Up – March 20, 2023 (#049)

    Greetings. Today’s Wrap Up features a bunch of good media including some advice for getting feedback from your boss, setting up a good team structure for SREs, and reasons why serverless may work for you.

    [blog] Introducing Forrester’s Function-As-A-Service Platforms Landscape. This post highlights what Forrester Research sees the current FaaS landscape.

    [article] Docker’s bad week. There was some messy communication from Docker last week about sunsetting their Free Teams service, but Matt focuses here on the bigger (positive) picture.

    [blog] The power of single-method interfaces in Go. Are single-method interfaces more powerful than higher order functions? Educational post.

    [blog] 6 Ways to Get Specific Feedback from Your Boss. Does your manager give you feedback? Often? Read this if you need help getting something useful from your boss.

    [blog] In defense of serverless. The “this computing paradigm is awful” posts are usually just click-bait, but some warrant further discussion. In this post, Hendrik answers the question of whether serverless is useful or not.

    [blog] Early-bird registration for Google Cloud Next ‘23 is open now. I can promise that this will be a major event. You should come. We’ll hang out!

    [youtube-playlist] Making Friends with Machine Learning. This is a tremendous YouTube playlist that features 100+ short videos for learning all about ML. It’s worth a listen!

    [blog] One’s attire says something to the world, and these days, it’s not nice. Some of you will violently agree with this, and others will violently disagree. But how you dress absolutely impacts how others see you!

    [blog] Who builds it and who runs it? SRE team topologies. If you’re investing in an SRE function, how are you building your team? This post offers some configurations.

    [blog] Pub/Sub schema evolution is now GA. Cloud message brokers still mostly take whatever you throw in there. If you want to limit the types of messages you accept, you’ll like Google Cloud’s Pub/Sub schema support. And now, you can create revisions and accept ranges of revisions in each Topic.

    ##

    Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:

  • Daily Wrap Up – March 17, 2023 (#048)

    Happy Friday. Today, I read a handful of great posts. Check out some insightful stuff about microservices, serverless, lowcode, and how to get un-frustrated (is that a word?) with your team.

    [article] 6 Questions to Ask Yourself When You’re Frustrated with Your Team. Do you ever feel like your team is not clicking? Something’s off? I thought this was a good piece if you need a tune-up.

    [blog] Why does everyone “suddenly” hate Single Page Apps? Here’s a guarantee for you. Something you’re obsessed with right now will be considered a “bad idea” in three years. It’s inevitable. As an individual, get good at learning how to learn. As a leader, build teams that are nimble and unafraid to adapt to changing circumstances.

    [blog] Microservices Best Practices. Simple title to this post, but you’ll find some lengthy advice. Not every architecture should be oriented around microservices—most shouldn’t?—but this is helpful advice if you’re taking that route.

    [blog] Build your first AppSheet app: how I built a food tracker. It’ll probably never be the “year of low code”, but tools like AppSheet definitely have a place at most any company. This is a excellent little walkthrough of building a simple data-driven app.

    [blog] Serverless in 2023. Has “serverless” had its moment yet? I’m not sure. It’s still lurking as a powerful architecture that many don’t take advantage of.

    [blog] BigQuery under the hood: Behind the serverless storage and query optimizations that supercharge performance. Check out this good deep-dive into one aspect of BigQuery and the technology (and tradeoffs) that go into running a high-performing, scalable data service.

    [blog] An End to End Machine Learning Model Development Guide Using BigQuery ML. More BigQuery stuff. This analytics service offers a fairly straightforward way to create and execute machine learning models directly within the service.

    [blog] Accelerating Ulta Beauty’s modernization with managed containerized microservices. Good case study that looks at fleet management of Kubernetes clusters.

    ##

    Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:

  • Daily Wrap Up – March 16, 2023 (#047)

    In today’s reading, I came across some great technical content—service mesh sidecars, zero trust architectures, ML model training—along with good professional content on topics like attention management and figuring out roles and responsibilities. Enjoy!

    [blog] Case Study: Cloud Native Finance at CS. Keep it simple, but not TOO simple. I liked this case study from the Container Solutions team that didn’t want to settle for data spread out all over the place. They built a solution to funnel it to a single data warehouse for analysis.

    [article] The Future of Istio: Sidecar-Less and Sidecar with Ambient Mesh. Good look at some changes to how the most popular service mesh works. I suspect that this direction will make the mesh less challenging for people to take advantage of.

    [blog] New Neuroscience Reveals 6 Secrets That Will Increase Your Attention Span. You doing well at staying focus on a given task? If so, you’re unusual. We all seem to be getting worse at maintaining attention. I liked this post which offered some perspective on how to improve.

    [blog] Learning from deep learning: a case study of feature discovery and validation in pathology. Exciting look at applying ML in a way that complements important healthcare activities.

    [blog] Intro to Kubernetes – Containers at Scale. Great communicators don’t show off how smart they are; rather, they focus on clearly explaining the point they want to make. Kaslin does that in this post.

    [paper] Advancing Zero Trust Maturity Throughout the User Pillar. Here’s a direct link to a PDF from the NSA that shares new guidance around zero trust security.

    [blog] Optimize PyTorch training performance with Reduction Server on Vertex AI. You may find yourself training ML models in the near future. I learned a few things from this post.

    [blog] Mitigate mainframe migration risks with Dual Run. Mainframe modernization seems like the dream of every cloud provider, but nobody has unlocked it. Here’s a new post on one option.

    [blog] When is RACI the Right Tool? If you work in a large org on an a very cross-functional project, it’s important to be clear on everyone’s role. This post explores when a RACI (responsible-accountable-consulted-informed) matrix makes sense.

    [blog] How Async/Await Really Works in C#. Huge post, but good deep dive into asynchronous programming in .NET and how it’s evolved over the years.

    ##

    Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:

  • Daily Wrap Up – March 15, 2023 (#046)

    Take a run through some of the thought-provoking content I came across today. There’s some useful material for designing SLOs, soliciting feedback, and using modern dev workstations.

    [blog] Adopting SRE: Standardizing your SLO design process. Useful content here, but the best thing is a link to a template you can download and use to define service level objectives for your workload. Adopting SLOs is a powerful way to create a common language around what’s important for your service.

    [article] How Leaders Can Get the Feedback They Need to Grow. this post has wonderful advice for soliciting and processing feedback, even the tough feedback we don’t love hearing.

    [blog] What Google Cloud VMware Engine can do for you: Three customers talk TCO. Lifting and shifting your hypervisor to the cloud doesn’t FEEL to me like the best long term strategy. But there are lots of reasons it works in the short term, and I liked this post which called out one or two benefits I hadn’t really thought of before.

    [article] The Great Lambda Migration to Kubernetes Jobs—A Journey in Three Parts. I think I see more folks go the other direction (from VMs or Kubernetes into something serverless), but this happens too. If you use a container-based set of runtimes (hint, GKE, Cloud Run, and even Compute Engine) this migration isn’t that big of a deal.

    [blog] Building a Media Understanding Platform for ML Innovations. The engineering team at Netflix built a platform to help their teams find just the right dialog or media from their movies to use in promotional videos.

    [blog] Reducing GKE Log Ingestion. This solves a fairly specific problem, but I like reading blog posts that walk you through a solution after explaining the problem area.

    [youtube-video] How to create a serverless Cloud Workstation. Here’s a five minute video that digs into online dev environments. Whether you code every day, or open an IDE once a week, this model has a lot of benefits.

    [blog] AWS’s Anti-Competitive Move Hidden in Plain Sight. Interesting. I honestly had to look and see if we’re any better. Appears that we charge a single price for cross-region replicas, whether you’re using VMs or managed DBs.

    [repo] GitHub OSPO. Building out an open source program office internally to support your consumption and participation in open source communities? GitHub just published some useful guidance.

    ##

    Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:

  • Daily Wrap Up – March 14, 2023 (#045)

    Big day for AI. OpenAI shipped GPT4 and Google announced a host of AI-infused Cloud products. Sit back and learn, even if you’re not ready to dive into that domain. Check out lots of other things below that I consumed today.

    [blog] The next generation of AI for developers and Google Workspace. One way or another, office work won’t be the same. Generative AI is going to have an impact. As you might expect, I’m fairly intrigued and excited about what we’re doing, and there’s a lot more to come.

    [youtube-video] A new era for AI and Google Workspace. What might “new” office work look like? This video gives you a glimpse into what assistive AI can do.

    [article] How to Help Superstar Employees Fulfill Their Potential. I needed this. Sometimes I feel stuck about which direction to go when mentoring folks at work. This gives me a few structured dimensions to focus on.

    [article] The problem with development speed. Good stuff here on not accidentally focusing on pure velocity. More code doesn’t equal more impact. Learn faster. That’s the key.

    [blog] Failure Mitigation for Microservices: An Intro to Aperture. This is an excellent post on the types of failures that can happen in a distributed, microservices architecture and how you might mitigate.

    [blog] Unlocking Real-time Predictions with Shopify’s Machine Learning Platform. “The cloud” is really a platform for your platform. Here, the Shopify team goes deeper into the ML experience they built for their users.

    [youtube-video] Pub/Sub Best Practices: Patterns, Experimentation, and Testing. Even if you’re not using Pub/Sub (I’ll still be friends with you) there’s advice here that impacts many messaging scenarios.

    [blog] What is fault tolerance, and how to build fault-tolerant systems. The team at CockroachDB looked at what fault tolerance means, how it differs from high availability, and how to architect for fault tolerance.

    [blog] Building the most open and innovative AI ecosystem. You can likely count on one hand the number of companies with the necessary compute capacity to train and serve massive large language models. It’s all about the ecosystem, as this post explores.

    ##

    Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below: