Starting with mainframes, ending with AI apps. Sounds about right for 2024. I’ve got a big reading list for you today, as I was able to consume a good amount of content today.
[article] Tech leaders struggle to rescue data trapped in mainframes. Twice last week during in-person customer briefings, I mentioned mainframes and caught knowing looks between audience members. Folks are hungry for ways to effectively tap into what’s there.
[blog] 8 expert tips for getting started with NotebookLM. I haven’t formed any habits around this product yet, but I suspect that this amazing service is going to become part of the daily workflow for MANY folks in the months ahead.
[blog] 5 Chunking Strategies For RAG. It’s cool seeing a sophistication of techniques getting widely shared now that many have embraced the fundamentals of LLMs.
[blog] Unpopular opinion about “Moving back to on-prem.” You can find a story that “proves” anything. Yes, some folks move workloads out of the cloud. No, it’s not a trend that I can see. Smart folks recognize what’s a differentiating investment, and what enables growth.
[blog] Vertex AI in Firebase is now Generally Available. I’m doubtful that tons of folks will regularly build “AI apps”, but I do expect that many of us will call LLMs as part of our “regular” apps. And integration with something like Firebase is awesome.
[article] Container Security, with Michele Chubrika. Listen to this podcast episode or read the transcript to get smart insights into modern security with Kubernetes and containers.
[blog] BigQuery Change Data Capture (CDC) using Pub/Sub. if your system can’t “speak” the language of the downstream system, sometimes you throw a proxy in between. This post shows how to use the gRPC API by sending data through Pub/Sub.
[article] Why developers lose trust in AI tools. This reviews a paper of ours and identifies what causes distrust in AI tools, and recommendations for growing user trust.
Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:
There’s a handful of career-oriented content in today’s list. You might always be thinking about your next step, or never thinking about it, but it’s not a bad idea to assess your current state every now and then!
[article] More attrition awaits overworked IT teams. Don’t just focus on employee satisfaction when the job market is hot. Continually try and build a good environment so that folks want to stay.
[blog] Management or IC: What’s Your Next Move? There are some good myths and realities in this post. I’ve definitely learned that management is a new job, not a variation of IC work.
[blog] gRPC: 5 Years Later, Is It Still Worth It? This is widely used, but I wouldn’t call it mainstream. But support for gRPC in products as an available communication protocol is growing.
[article] Is Your Career Heading in the Right Direction? No idea, but I’m enjoying myself. It’s always good to check in with yourself (and trusted folks) to see if you’re satisfied and growing.
I had a trip up to Sunnyvale today and some great chats with a pair of customers. Tomorrow, I’m speaking at an event and jetting back home. I enjoy testing out new ideas and messaging on unsuspecting folks!
[article] How CIOs are reskilling their workforce. You’re not going to hire a ton of AI experts. They’re not out there. But you can reskill and upskill your existing talent.
[blog] Google Cloud Is Making GenAI Boring. You’re welcome? This post points out that we’re not playing follow-the-leader. We’re blending AI into our platform in creative ways, and making it easier to do important things.
[blog] Fine-tuning Gemma, the journey from beginning to end. It doesn’t matter if you care about Gemma, or prefer other open LLMs. Read this post to learn some of the terminology and activities that matter when fine tuning models.
[blog] SMURF: Beyond the Test Pyramid. This short post from our Testing experts encourages a more robust way to think about your test suite and identifies where tension can exist.
Check out a mix of content in today’s reading list. The one on “red flags from hiring managers” got me thinking of interviews I’ve conducted recently. FYI, you’re not as stealth using ChatGPT or Gemini as you think you are 🙂
[blog] Ray Batch Inference at Pinterest (Part 3). The team at Pinterest has seen better performance and lower cost by using the Ray framework for offline batch interference of ML models.
[article] Friday Forward – Great Company. What are the traits of a great company? Bob says it’s about a product/service people love, great culture and people, and operational excellence.
[blog] Advanced RAG Techniques. The slides and video here will definitely up your game on retrieval augmented generation. I’m impressed with how the topic is covered.
[article] How Fireship became YouTube’s favorite programmer. I’ll admit that I’m not a “watch YouTube videos for hours” kinda guy, but it’s easy to go down the rabbit hole with Fireship videos. And I learn a bunch about tech!
[blog] Firebase Data Connect: now in public preview! I’m going to get hands-on with this myself, as it seems like a remarkably developer-friendly way to access robust database services.
[blog] Announcing Deno 2. In exploring this latest release of the JavaScript runtime, Simon uncovered a Jupyter notebook kernel in there. Nice option for those that want notebooks!
Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:
Trust. Without trust, AI coding assistants won’t become a default tool in a developer’s toolbox. Trust is the #1 concern of devs today, and it’s something I’ve struggled with in regards to getting the most relevant answers from an LLM. Specifically, am I getting back the latest information? Probably not, given that LLMs have a training cutoff date. Your AI coding assistant probably doesn’t (yet) know about Python 3.13, the most recent features of your favorite cloud service, or the newest architectural idea shared at a conference last week. What can you do about that?
To me, this challenge comes up in at least three circumstances. There are entirely new concepts or tools that the LLM training wouldn’t know about. Think something like pipe syntax as an alternative to SQL syntax. I wouldn’t expect a model trained last year to know about that. How about updated features to existing libraries or frameworks? I want suggestions that reflect the full feature set of the current technology and I don’t want to accidentally do something the hard (old) way. An example? Consider the new “enum type” structured output I can get from LangChain4J. I’d want to use that now! And finally, I think about improved or replicated framework libraries. If I’m upgrading from Java 8 to Java 23, or Deno 1 to Deno 2, I want to ensure I’m not using deprecated features. My AI tools probably don’t know about any of these.
I see four options for trusting the freshness of responses from your AI assistant. The final technique was brand new to me, and I think it’s excellent.
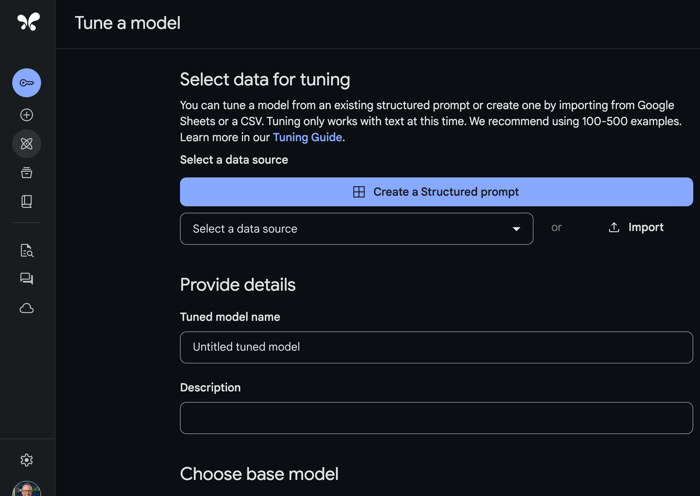
Fine-tune your model
Use retrieval augmented generation (RAG)
Ground the results with trusted sources
“Train” on the fly with input context
Let’s briefly look at the first three, and see some detailed examples of the fourth.
Fine-tune your model
Whether using commercial or open models, they all represent a point-in-time based on their training period. You could choose to repeatedly train your preferred model with fresh info about the programming languages, frameworks, services, and patterns you care about.
The upside? You can get a model with knowledge about whatever you need to trust it. The downside? It’s a lot of work—you’d need to craft a healthy number of examples and must regularly tune the model. That could be expensive, and the result wouldn’t naturally plug into most AI coding assistance tools. You’d have to jump out of your preferred coding tool to ask questions of a model elsewhere.
Use RAG
Instead of tuning a serving a custom model, you could choose to augment the input with pre-processed content. You’ll get back better, more contextual results when taking into account data that reflects the ideal state.
The upside? You’ll find this pattern increasingly supported in commercial AI assistants. This keeps you in your flow without having to jump out to another interface. GitHub Copilot offers this, and now our Gemini Code Assist provides code customization based on repos in GitHub or GitLab. With Code Assist, we handle the creation and management of the code index of your repos, and you don’t have to manually chunk and store your code. The downside? This only works well if you’ve got the most up-to-date data in an indexed source repo. If you’ve got old code or patterns in there, that won’t help your freshness problem. And while these solutions are good for extra code context, they may not support a wider range of possible context sources (e.g. text files).
Ground the results
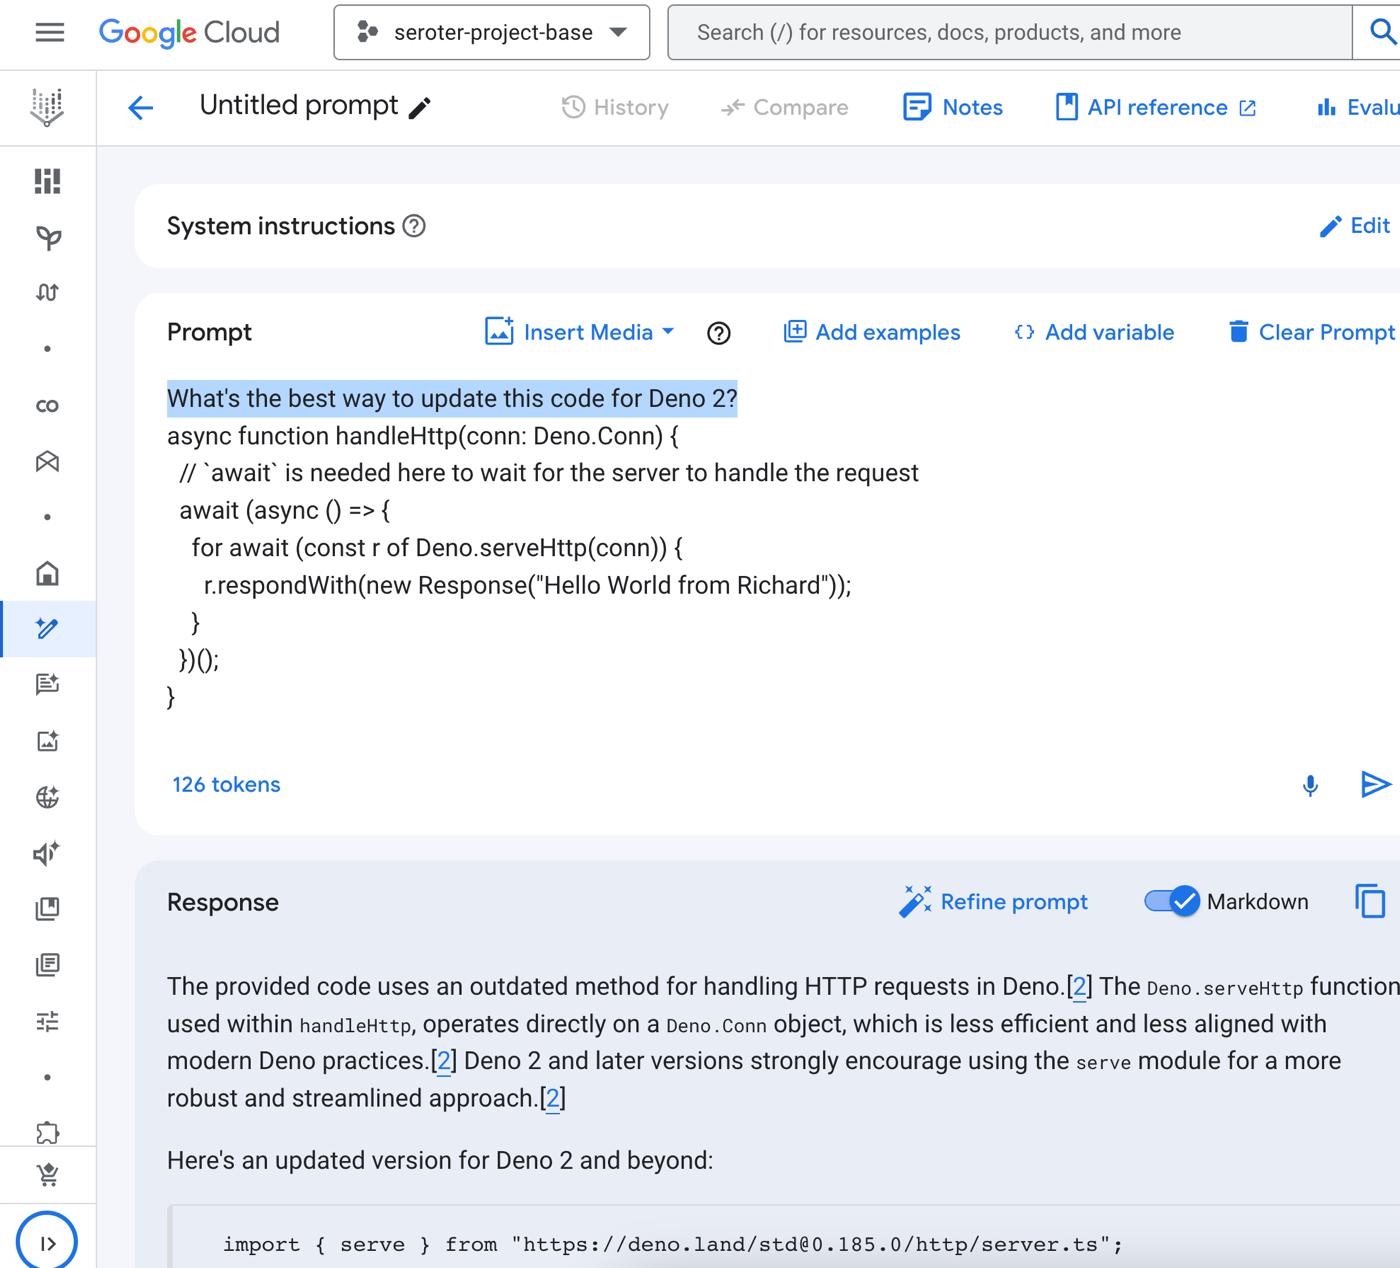
This approach gives you more confidence that the results are accurate. For example, Google Cloud’s Vertex AI offers “ground with Google Search” so that responses are matched to real, live Google Search results.
If I ask a question about upgrading an old bit of Deno code, you can see that the results are now annotated with reference points. This gives me confidence to some extent, but doesn’t necessarily guarantee that I’m getting the freshest answers. Also, this is outside of my preferred tool, so it again takes me out of a flow state.
Train on the fly
Here’s the approach I just learned about from my boss’s boss, Keith Ballinger. I complained about freshness of results from AI assistance tools, and he said “why don’t you just train it on the fly?” Specifically, pass the latest and greatest reference data into a request within the AI assistance tool. Mind … blown.
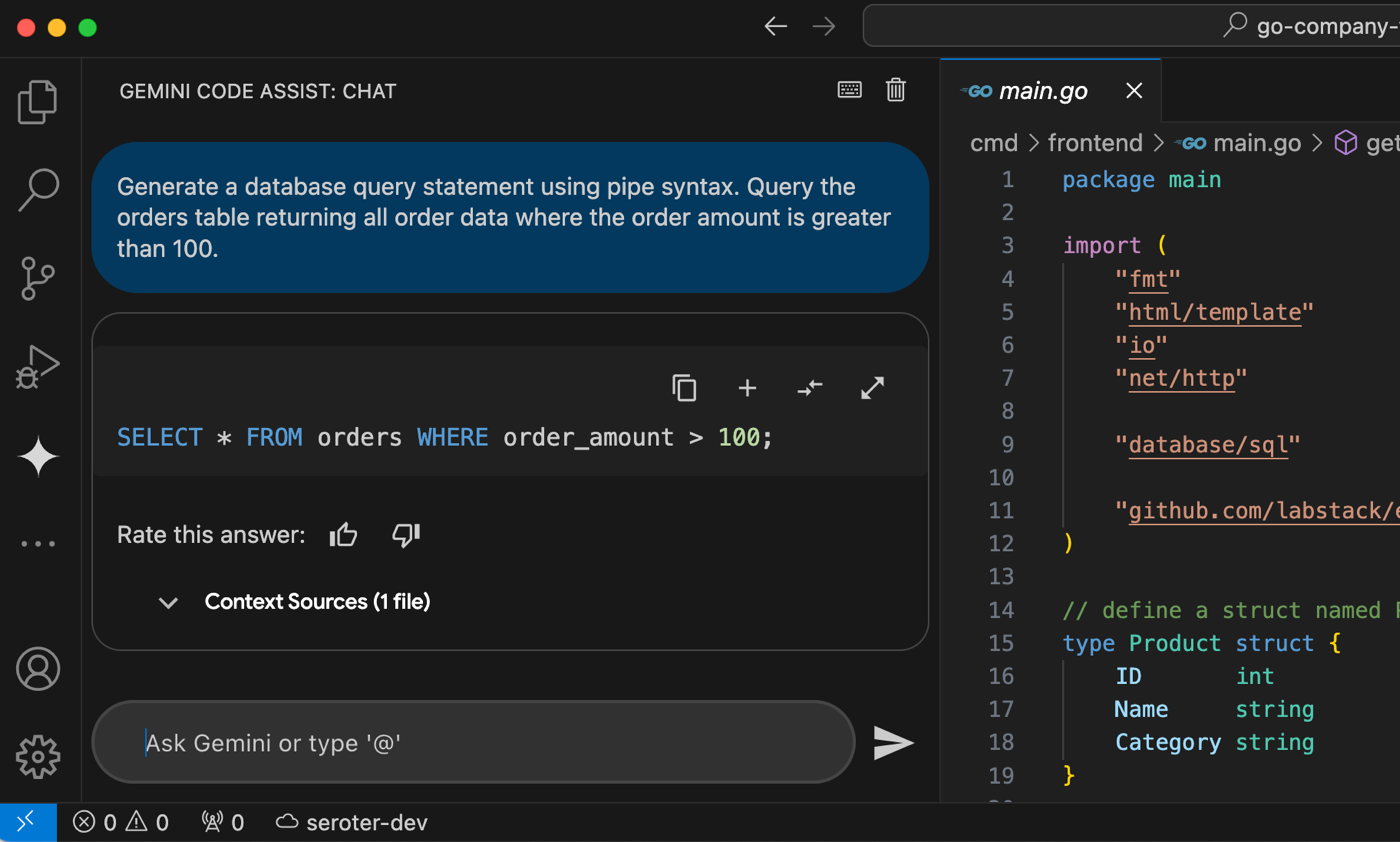
How might it handle entirely new concepts or tools? Let’s use that pipe syntax example. In my code, I want to use this fresh syntax instead of classic SQL. But there’s no way my Gemini Code Assist environment knows about that (yet). Sure enough, I just get back a regular SQL statement.
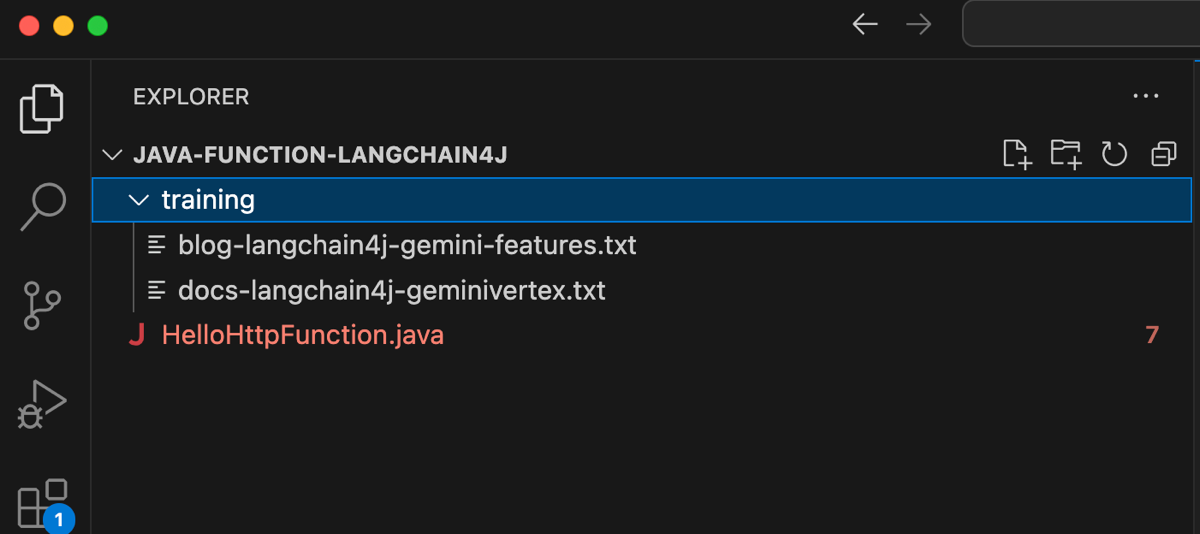
But now, Gemini Code Assist supports local codebase awareness, up to 128,000 input tokens! I grabbed the docs for pipe query syntax, saved as a PDF, and then asked Google AI Studio to produce a Markdown file of the docs. Note that Gemini Code Assist isn’t (yet) multi-modal, so I need Markdown instead of passing in a PDF or image. I then put a copy of that Markdown file in a “training” folder within my app project. I used the new @ mention feature in our Gemini Code Assist chat to specifically reference the syntax file when asking my question again.
Wow! So by giving Gemini Code Assist a reference file of pipe syntax, it was able to give me an accurate, contextual, and fresh answer.
What about updated features to existing libraries or frameworks? I mentioned the new feature of LangChain4J for the Gemini model. There’s no way I’d expect my coding assistant to know about a feature added a few days ago. Once again, I grabbed some resources. This time, I snagged the Markdown doc for Google Vertex AI Gemini from the LangChain4J repo, and converted a blog post from Guillaume to Markdown using Google AI Studio.
My prompt to the Gemini Code Assist model was “Update the service function with a call to Gemini 1.5 Flash using LangChain4J. It takes in a question about a sport, and the response is mapped to an enum with values for baseball, football, cricket, or other.” As expected, the first response was a good attempt, but it wasn’t fully accurate. And it used a manual way to map the response to an enum.
What if I pass in both of those training files with my prompt? I get back exactly the syntax I wanted for my Cloud Run Function!
So great. This approach requires me to know what tech I’m interested in up front, but still, what an improvement!
Final example. How about improved or replicated framework libraries? Let’s say I’ve got a very old Deno app that I created when I first got excited about this excellent JavaScript runtime.
// from https://deno.com/blog/v1.35#denoserve-is-now-stable
async function handleHttp(conn: Deno.Conn) {
  // `await` is needed here to wait for the server to handle the request
  await (async () => {
    for await (const r of Deno.serveHttp(conn)) {
      r.respondWith(new Response("Hello World from Richard"));
    }
  })();
}

for await (const conn of Deno.listen({ port: 8000 })) {
  handleHttp(conn);
}
This code uses some libraries and practices that are now out of date. When I modernize this app, I want to trust that I’m doing it the best way. Nothing to fear! I grabbed the Deno 1.x to 2.x migration guide, a blog post about the new approach to web servers, and the launch blog for Deno 2. The result? Impressive, including a good description of why it generated the code this way.
I could imagine putting the latest reference apps into a repo and using Gemini Code Assist’s code customization feature to pull that automatically into my app. But this demonstrated technique gives me more trust in the output of tool when freshness is paramount. What do you think?
Flying home today, and thankful for decent wifi on this flight. Not good enough to do real work, but good enough to catch up email and do some tech reading. Enjoy the weekend.
[article] How to Give Busy People the Time to Innovate. I liked many of the points in this article, and it’s something that matters if you need time for innovation, or want to free up your team to do creative work.
[blog] Valkey Momentum: Seven Months In. Here’s some excellent, well-rounded research from Rachel that explores the Redis project and its viable alternatives.
Today was the last full day of my trip to Sweden, and it was a busy one. I was part of the keynote at our Google Cloud Summit Nordics, participated in a panel interview, did three customer briefings, delivered a 45-minute talk and demo, and did a press interview. Back home tomorrow!
[article] The State of Security in 2024. Here’s new survey data from O’Reilly that tells us what security professionals are worried about, and what they’re learning about.
Another packed day in Stockholm, with a keynote rehearsals for keynotes tomorrow. What a treat to get to work with and learn from folks around the world!
[blog] What is Infrastructure as Data? What does this even mean? Is it all about having a serializable data structure that gets applied to infrastructure? Brian explores.
[article] Stop Ignoring Your High Performers. I was convicted about this point when I read Andy Grove’s book a few years back. You might mistakenly think high performers have it all figured out and should be left alone. That’s wrong. Spend MORE time with these folks.
[blog] Don’t deploy these applications on serverless. For those whose serverless worldview consists of Amazon Lambda, this advice makes sense. For devs that use more modern runtimes (*cough* Cloud Run *cough*), these aren’t necessarily the same concerns.
[blog] Defining statistical models in JAX? We don’t make a lot of noise about JAX and why it’s awesome for ML Engineers. But many folks love using it.
[blog] Writing a circuit breaker in Go. How are you protecting your systems from cascading failures? Circuit breaker is one pattern to apply. This post looks at building one in Go.